Sparse prefill for GLM
GLM prefill now attends only to the keys its indexer picks

This pull request makes long prompts much faster to prefill on GLM models with DeepSeek sparse attention. The indexer already picks the top-k keys for each query. Now prefill attention reads only those keys, gathered from the cache, instead of masking all the others. It's on by default once the cache holds about 16,000 tokens.
The dense mask
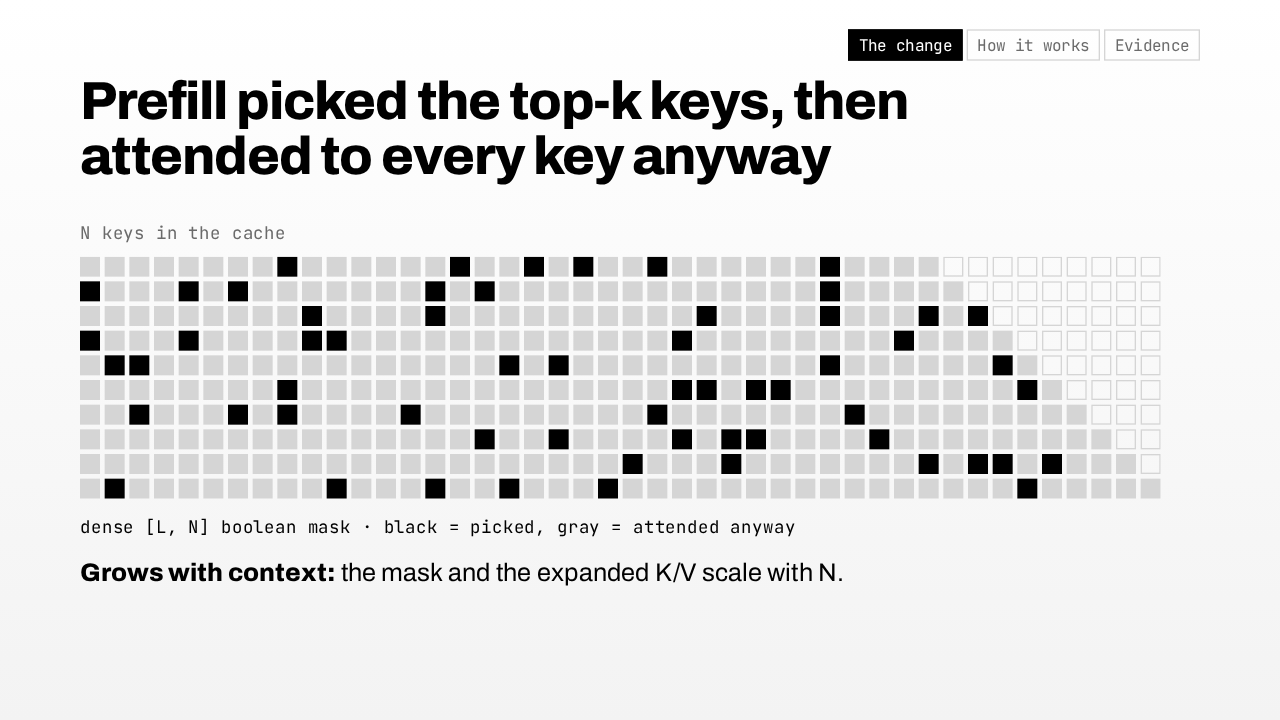
Prefill picked the top-k keys, then attended to every key anyway
Before this change, prefill turned the indexer's selection into a dense boolean mask, one row per query and one column per key, and then ran masked attention over every key. In the author's words, the selection is computed, then the work is spent on all N keys anyway. The mask and the expanded keys and values also grow linearly with context.
1 · How it works
How the sparse path works
Here's how the sparse path works.
When it runs
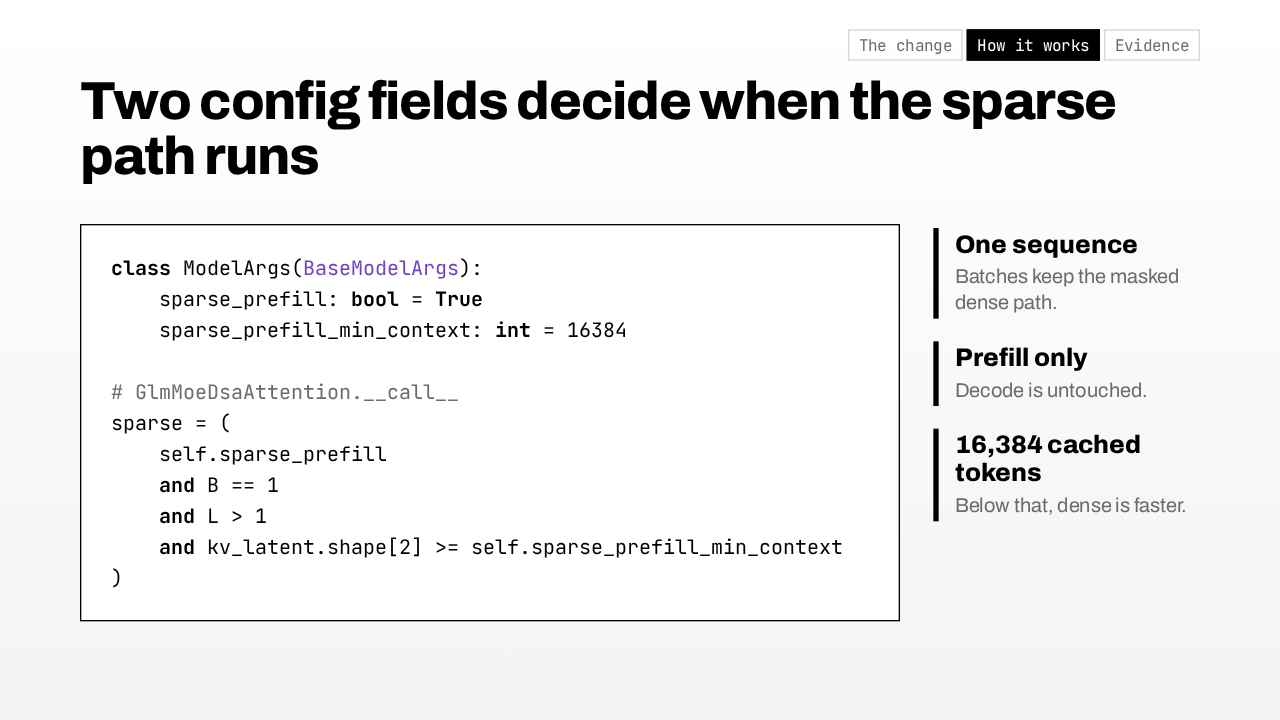
Two config fields decide when the sparse path runs
class ModelArgs(BaseModelArgs):
    sparse_prefill: bool = True
    sparse_prefill_min_context: int = 16384

# GlmMoeDsaAttention.__call__
sparse = (
    self.sparse_prefill
    and B == 1
    and L > 1
    and kv_latent.shape[2] >= self.sparse_prefill_min_context
)Two new fields on ModelArgs control it. Sparse prefill is on by default, with a minimum context of 16,384 tokens. It only runs for a single sequence, so batches keep the masked dense path. It only runs in prefill, so decode is untouched. And below the minimum context the dense path is faster, so the code keeps it there.
Sparse attention
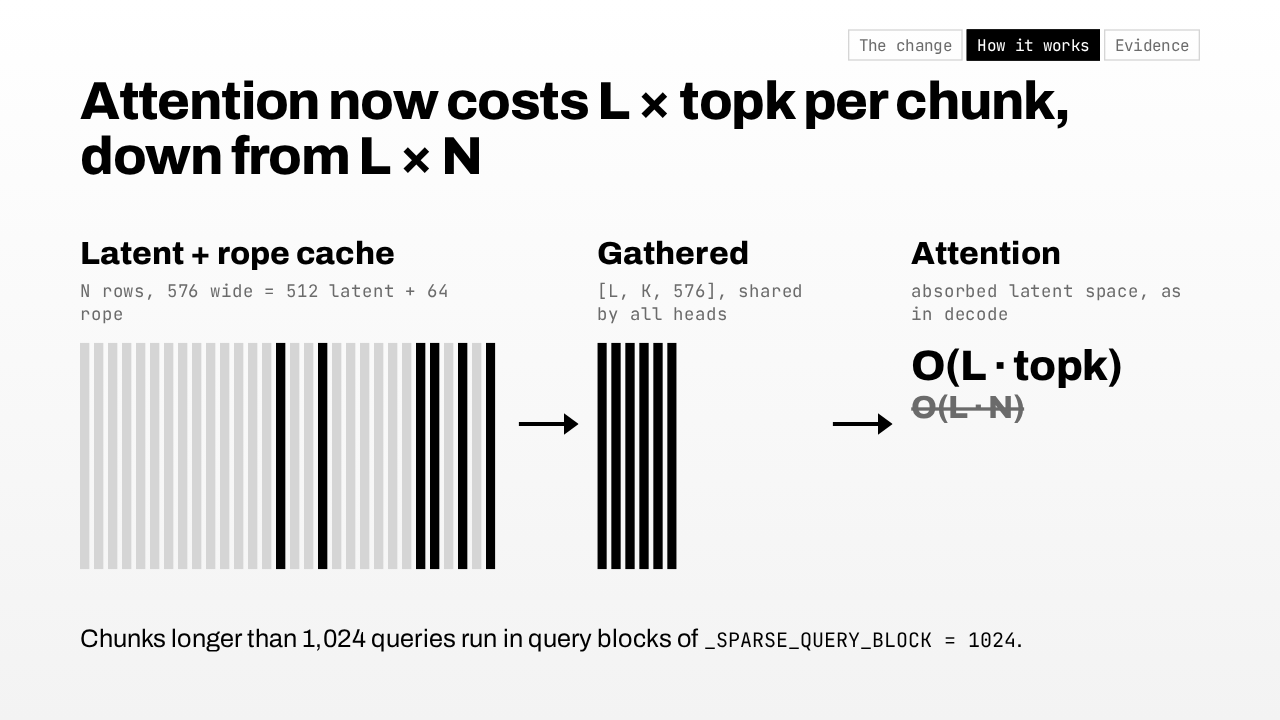
Attention now costs L × topk per chunk, down from L × N
The attention half is a new function, sparse prefill. It joins the latent and rope caches into one 576-wide key per position, then gathers just the top-k rows each query picked. All heads share that gathered block. Attention runs in the absorbed latent space, the same form decode already uses, so each chunk costs L times top-k instead of L times N. Chunks longer than 1,024 queries split into query blocks, which keeps the gathered keys small.
Blocked top-k
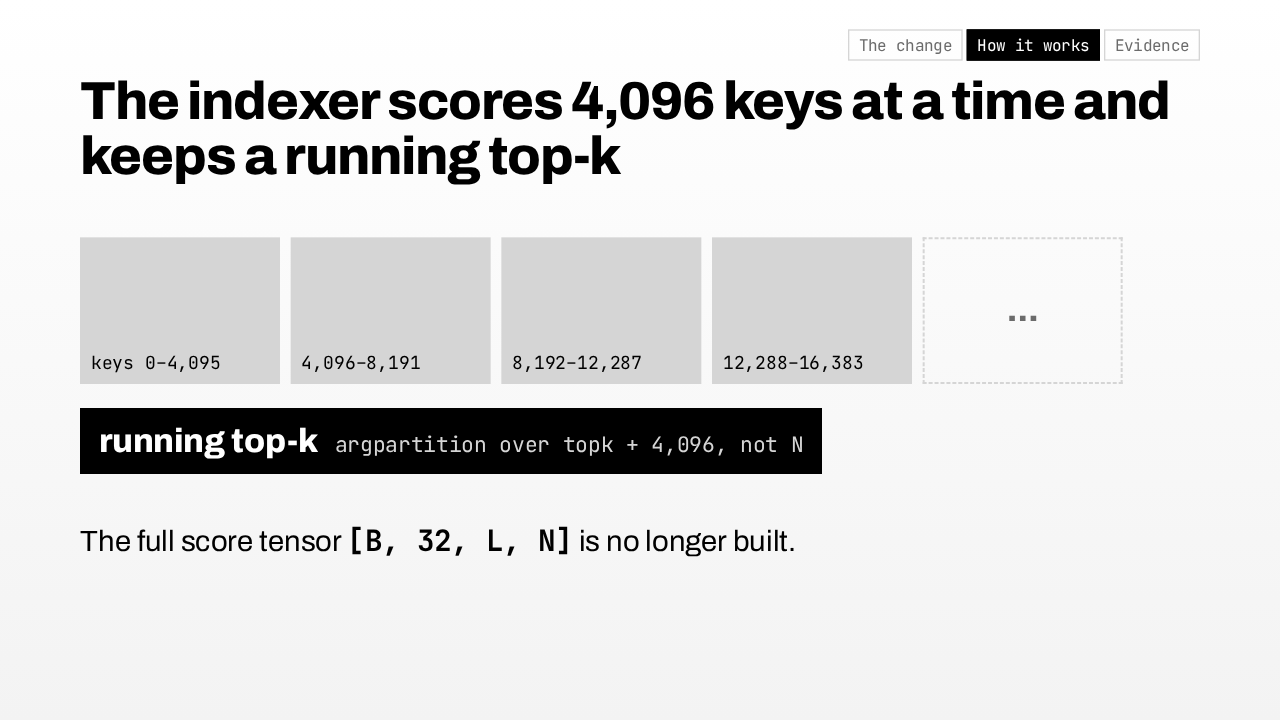
The indexer scores 4,096 keys at a time and keeps a running top-k
The indexer gets the same treatment, in a function called blocked top-k. It scores the keys in blocks of 4,096 and folds each block into a running top-k list, so each argpartition sorts rows of top-k plus 4,096 instead of N. The full score tensor, batch by 32 heads by L by N, is no longer built. It selects the same keys as the stock indexer, up to the order of equal scores.
What it touches
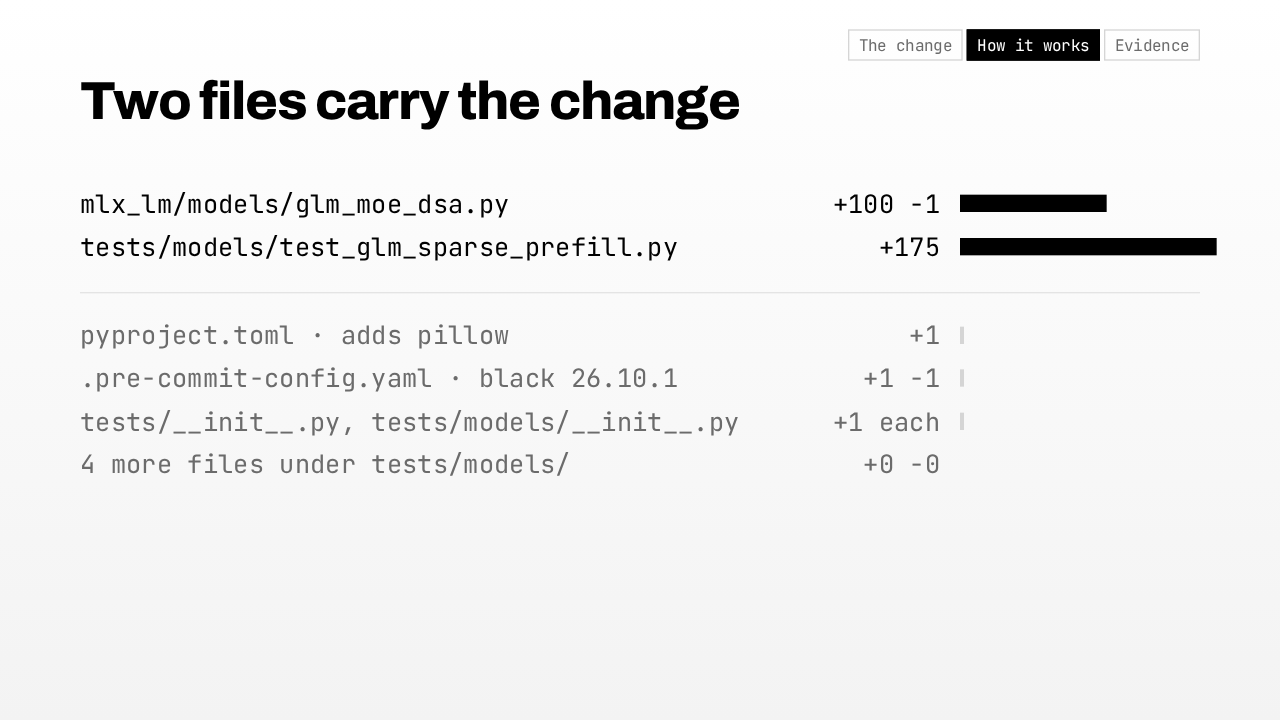
Two files carry the change
Almost all of it lands in two files: the model file, with about 100 added lines, and a new test file of 175 lines. The rest rides along. Pillow joins the package dependencies, the black pre-commit hook gets a version bump, and two init files turn the test folders into packages.
2 · Evidence
The evidence
Now the evidence.
Prefill speed
At 128K context, prefill runs about 8× faster
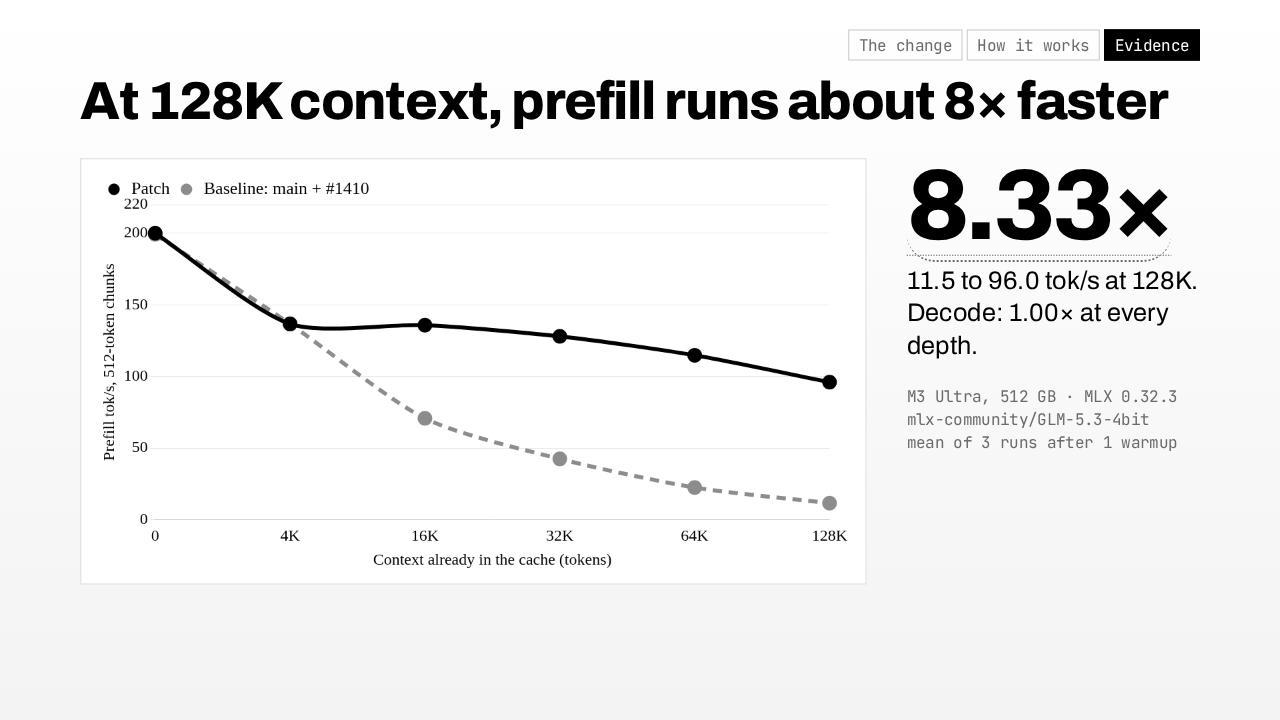
Prefill throughput at 128K context, 512-token chunks: 11.5 tok/s baseline, 96.0 tok/s patch.
With mlx_lm.benchmark: 32K prompt 87.3 to 159.3 tok/s (1.82×); 64K prompt 51.6 to 142.2 tok/s (2.76×).
11.5 to 96.0 tok/s at 128K.
Decode: 1.00× at every depth.
M3 Ultra, 512 GB · MLX 0.32.3
mlx-community/GLM-5.3-4bit
mean of 3 runs after 1 warmup
This is an M3 Ultra running GLM 5.3 at 4-bit, with 512-token prefill chunks. Black is the patch, and the dashed gray line is the baseline. Up to 4,000 tokens of context the two match, because the gate keeps the dense path. From 16,000 on, the baseline falls off, and the patch slows far more gently. At 128,000 tokens, prefill goes from about 12 to 96 tokens per second, roughly eight times faster. Decode speed is unchanged.
Peak memory
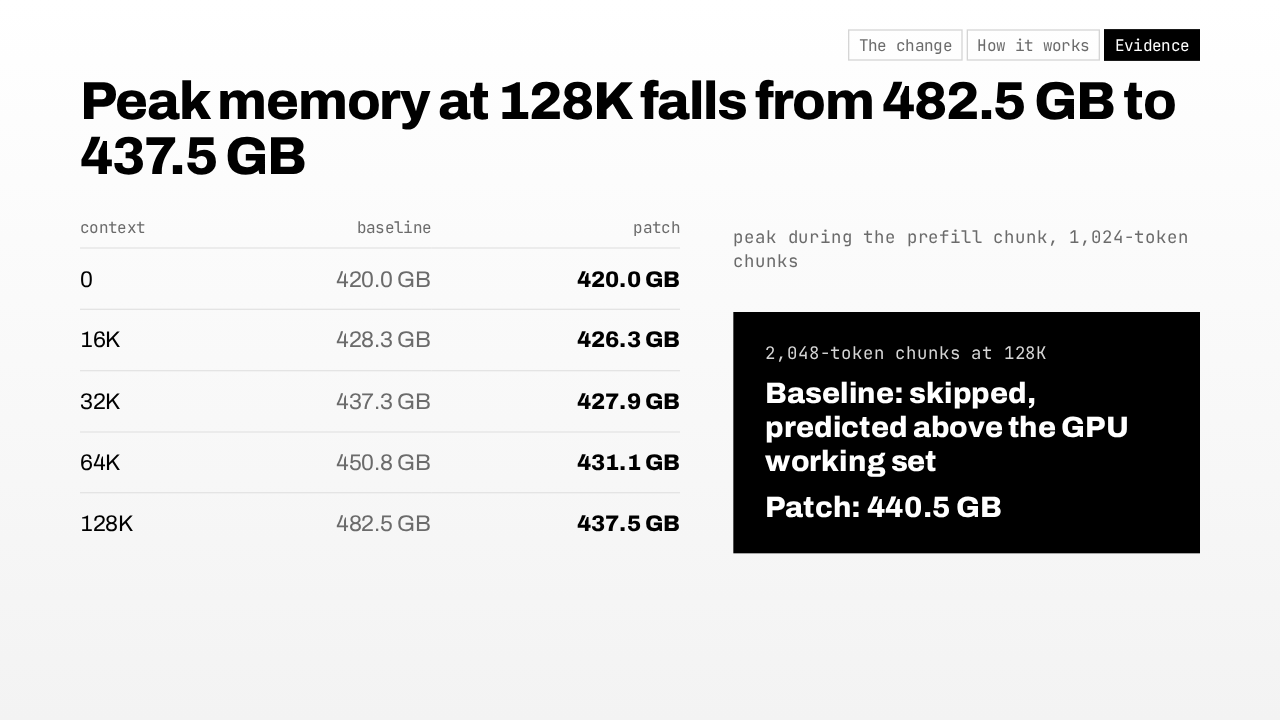
Peak memory at 128K falls from 482.5 GB to 437.5 GB
| context | baseline | patch |
|---|---|---|
| 0 | 420.0 GB | 420.0 GB |
| 16K | 428.3 GB | 426.3 GB |
| 32K | 437.3 GB | 427.9 GB |
| 64K | 450.8 GB | 431.1 GB |
| 128K | 482.5 GB | 437.5 GB |
Memory follows the same curve. With 1,024-token chunks, the baseline's peak climbs fast with context, and the patch's climbs slowly. At 128,000 tokens it drops from about 480 to about 440 gigabytes. With 2,048-token chunks at 128,000 tokens, the baseline was skipped because its predicted peak was above the GPU working set. The patch ran it, peaking at about 440 gigabytes.
Accuracy and tests
Sparse prefill keeps the stock top token at almost every position
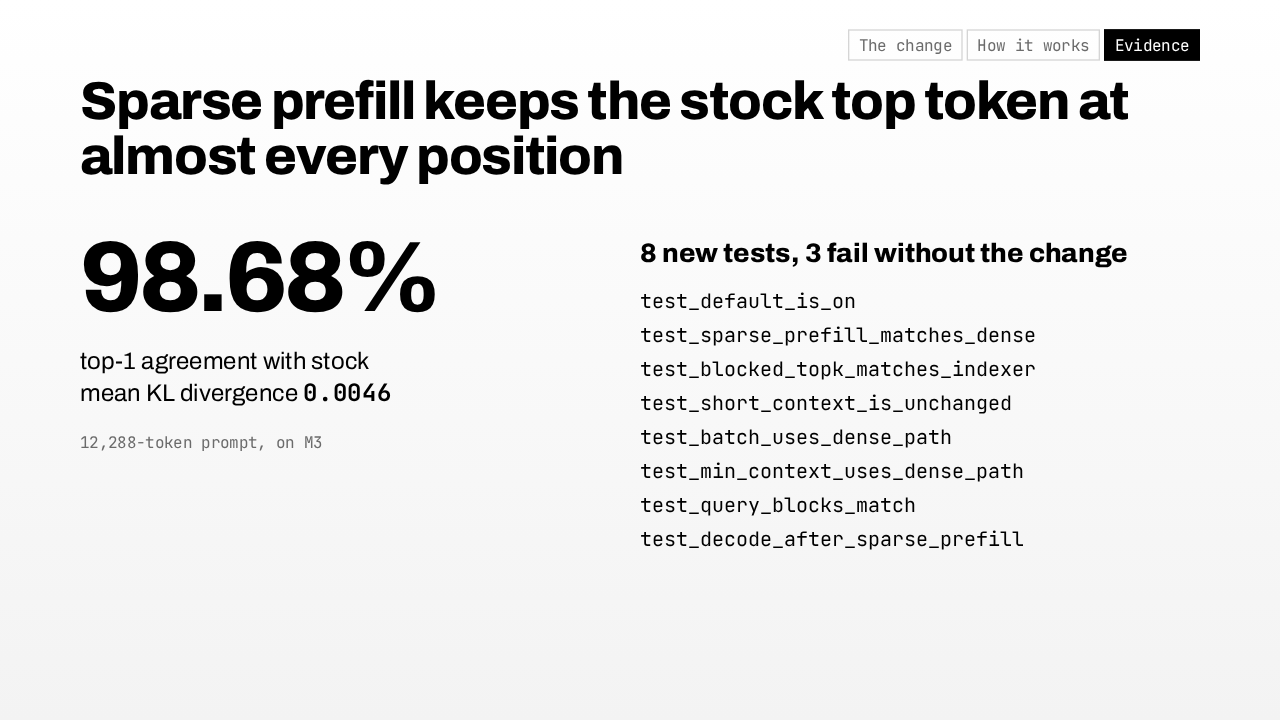
top-1 agreement with stock
mean KL divergence 0.0046
12,288-token prompt, on M3
test_sparse_prefill_matches_dense
test_blocked_topk_matches_indexer
test_short_context_is_unchanged
test_batch_uses_dense_path
test_min_context_uses_dense_path
test_query_blocks_match
test_decode_after_sparse_prefill
Output stays close to stock. On a prompt of about 12,000 tokens, mean KL divergence is 0.0046, and the top token matches stock at almost 99 of every 100 positions. Eight new tests cover the path. Sparse output matches dense within a ten-thousandth, batches and short or gated contexts take the dense path unchanged, query blocks match, and decode works after a sparse prefill. Three of them fail without this change.
Limits and what to do
Long GLM prompts prefill faster, one sequence at a time
On by default. To turn it off, set "sparse_prefill": false in the model config.
Two limits. Batches still take the dense path, and DeepSeek models with sparse attention aren't covered yet. They're planned for a follow-up, with a smaller expected gain, since their indexer runs on every layer. It's on by default, and setting sparse prefill to false in the model config turns it off. GLM prefill now attends only to the keys its indexer picks.