mlx-lm 0.32.2 loads Muse Spark from its Hugging Face checkpoint

2 days ago

Version 0.32.2 of mlx-lm is a small release, and Muse Spark users need to know about it. Muse Spark now loads from its Hugging Face checkpoint, using the Hugging Face names. The release also fixes attention value scaling in MiMo-V2-Flash, and padded prompts in state-space models.

Ask about this presentation

Chapters
  1. 0:00mlx-lm 0.32.2
  2. 0:21Hugging Face names
  3. 0:42Images and tool calls
  4. 1:072 · Fixes
  5. 1:10MiMo-V2-Flash
  6. 1:36Padded SSM prompts
  7. 1:583 · Upgrading
  8. 2:00Breaking: Muse Spark names
  9. 2:26Upgrade
Show transcript
  1. Version 0.32.2 of mlx-lm is a small release, and Muse Spark users need to know about it. Muse Spark now loads from its Hugging Face checkpoint, using the Hugging Face names. The release also fixes attention value scaling in MiMo-V2-Flash, and padded prompts in state-space models.

    Slide text
    Muse Spark Fixes Upgrading

    mlx-lm 0.32.2 loads Muse Spark from its Hugging Face checkpoint

    Also fixed: MiMo-V2-Flash attention value scaling, and padded prompts in state-space models.

    MLX
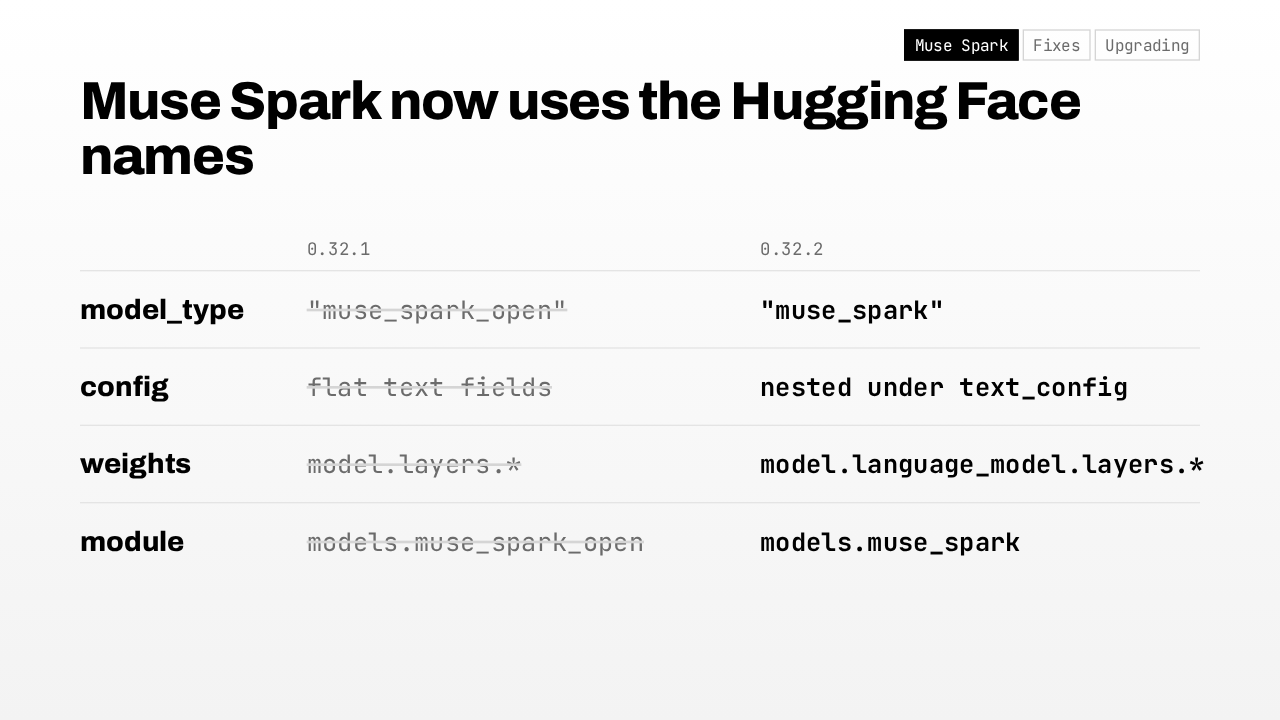
  2. Until this release, Muse Spark support used its own names for the model type, the config and the weights. Now they match the Hugging Face checkpoint. The model type drops the word open. Text settings move under text config, with the Hugging Face field names. The language model weights load from model dot language model, and the module is renamed to match.

    Slide text
    Muse Spark Fixes Upgrading

    Muse Spark now uses the Hugging Face names

    0.32.1 0.32.2
    model_type
    "muse_spark_open"
    "muse_spark"
    config
    flat text fields
    nested under text_config
    weights
    model.layers.*
    model.language_model.layers.*
    module
    models.muse_spark_open
    models.muse_spark
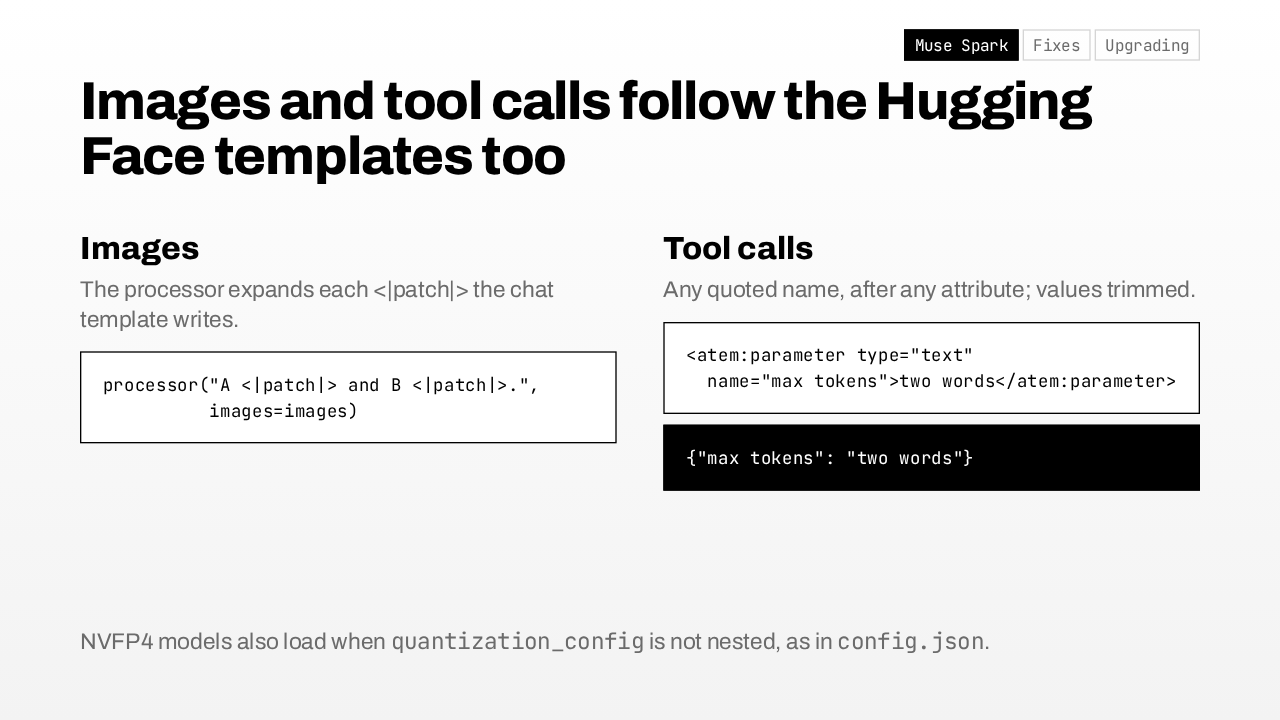
  3. The inputs follow the same templates. The image processor now expands each patch token that the chat template writes, where it used to look for an image placeholder. The tool-call parser takes any parameter name inside double quotes, even after another attribute, and trims whitespace from text values. And NVFP4 models load when the quantization settings sit directly in the model config.

    Slide text
    Muse Spark Fixes Upgrading

    Images and tool calls follow the Hugging Face templates too

    Images

    The processor expands each <|patch|> the chat template writes.

    processor("A <|patch|> and B <|patch|>.",
              images=images)
    Tool calls

    Any quoted name, after any attribute; values trimmed.

    <atem:parameter type="text"
      name="max tokens">two words</atem:parameter>
    {"max tokens": "two words"}

    NVFP4 models also load when quantization_config is not nested, as in config.json.

  4. Next, two fixes to model outputs.

    Slide text
    2

    Two output fixes

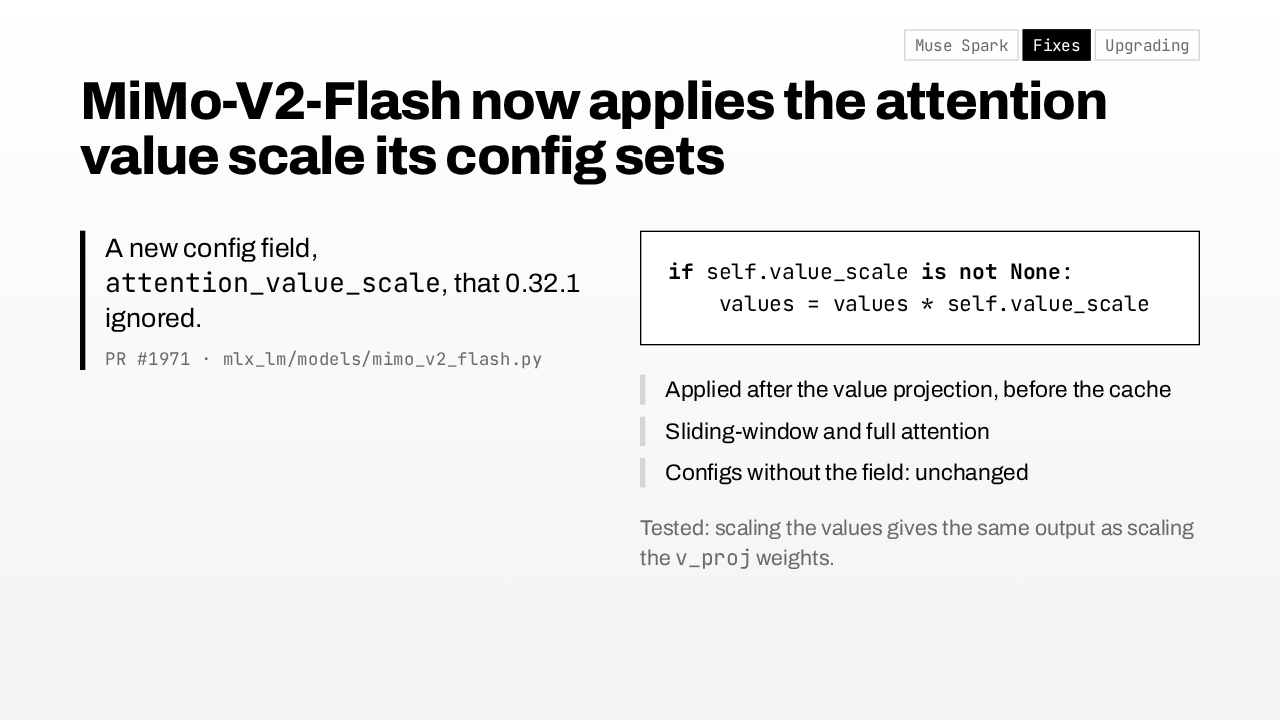
  5. MiMo-V2-Flash configs can carry a scale for the attention values, and until this release that field was ignored. Now the scale is read from the config and applied right after the value projection, before the cache, in both sliding-window and full attention layers. A new test checks that scaling the values gives the same output as scaling the value projection weights. Configs without the field behave as before.

    Slide text
    Muse Spark Fixes Upgrading

    MiMo-V2-Flash now applies the attention value scale its config sets

    A new config field, attention_value_scale, that 0.32.1 ignored.PR #1971 · mlx_lm/models/mimo_v2_flash.py

    if self.value_scale is not None:
        values = values * self.value_scale
    Applied after the value projection, before the cache
    Sliding-window and full attention
    Configs without the field: unchanged

    Tested: scaling the values gives the same output as scaling the v_proj weights.

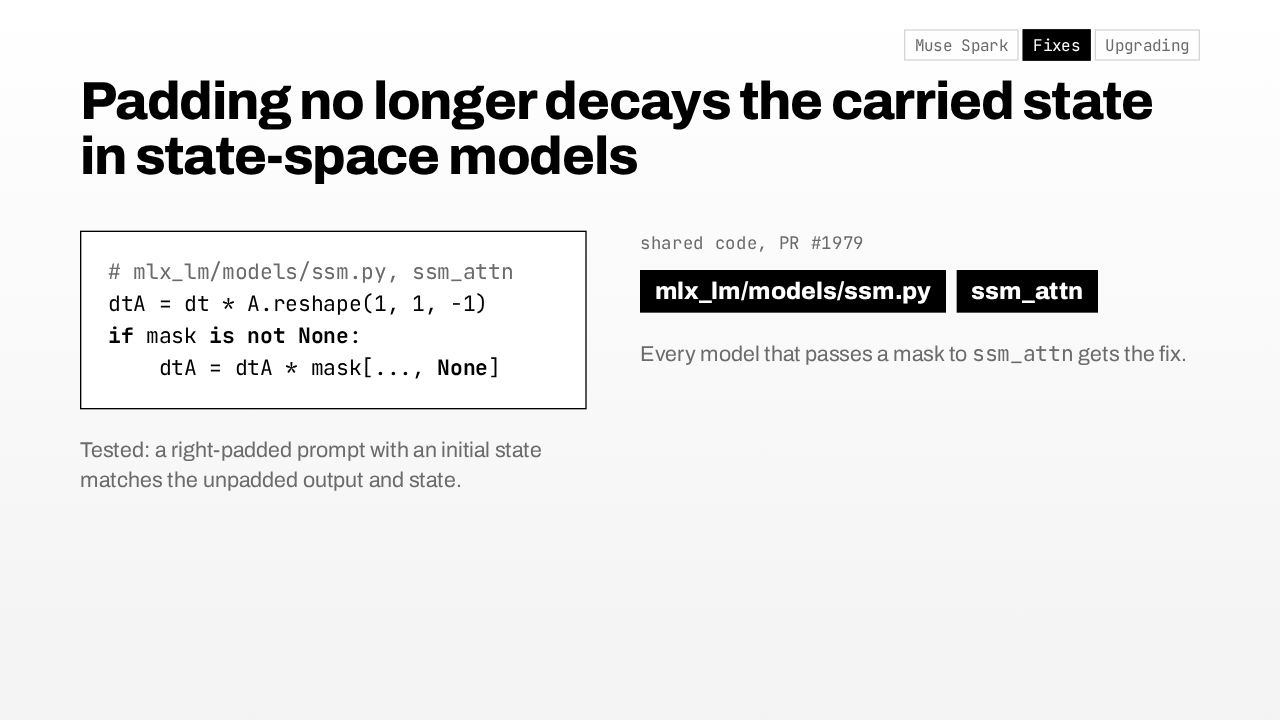
  6. The second fix is in the shared state-space code. When a prompt was padded and the model already carried state from earlier tokens, the padded positions still decayed that state. Now the decay is multiplied by the mask, so padding leaves the state alone, and a right-padded prompt matches the unpadded one. Every model that passes a mask through that code gets the fix.

    Slide text
    Muse Spark Fixes Upgrading

    Padding no longer decays the carried state in state-space models

    # mlx_lm/models/ssm.py, ssm_attn
    dtA = dt * A.reshape(1, 1, -1)
    if mask is not None:
        dtA = dtA * mask[..., None]

    Tested: a right-padded prompt with an initial state matches the unpadded output and state.

    shared code, PR #1979
    mlx_lm/models/ssm.py ssm_attn

    Every model that passes a mask to ssm_attn gets the fix.

  7. Now, upgrading.

    Slide text
    3

    Upgrading

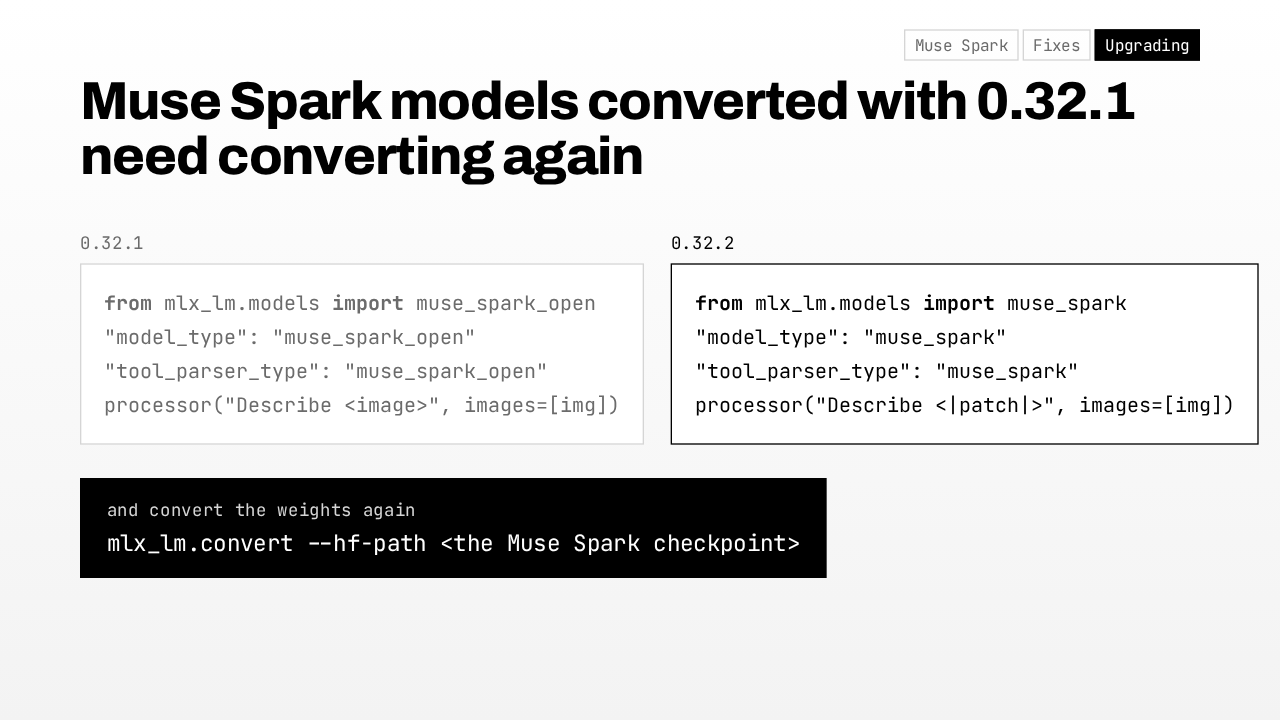
  8. There's one breaking change, and it only affects Muse Spark. Version 0.32.2 drops the muse spark open model type, module and tool parser, and the processor stops looking for an image placeholder. So a Muse Spark model converted with 0.32.1 won't load. Convert it again from the Hugging Face checkpoint, and point any imports or prompts at the new names. Everyone else has nothing to migrate.

    Slide text
    Muse Spark Fixes Upgrading

    Muse Spark models converted with 0.32.1 need converting again

    0.32.1
    from mlx_lm.models import muse_spark_open
    "model_type": "muse_spark_open"
    "tool_parser_type": "muse_spark_open"
    processor("Describe <image>", images=[img])
    0.32.2
    from mlx_lm.models import muse_spark
    "model_type": "muse_spark"
    "tool_parser_type": "muse_spark"
    processor("Describe <|patch|>", images=[img])
    and convert the weights againmlx_lm.convert --hf-path <the Muse Spark checkpoint>
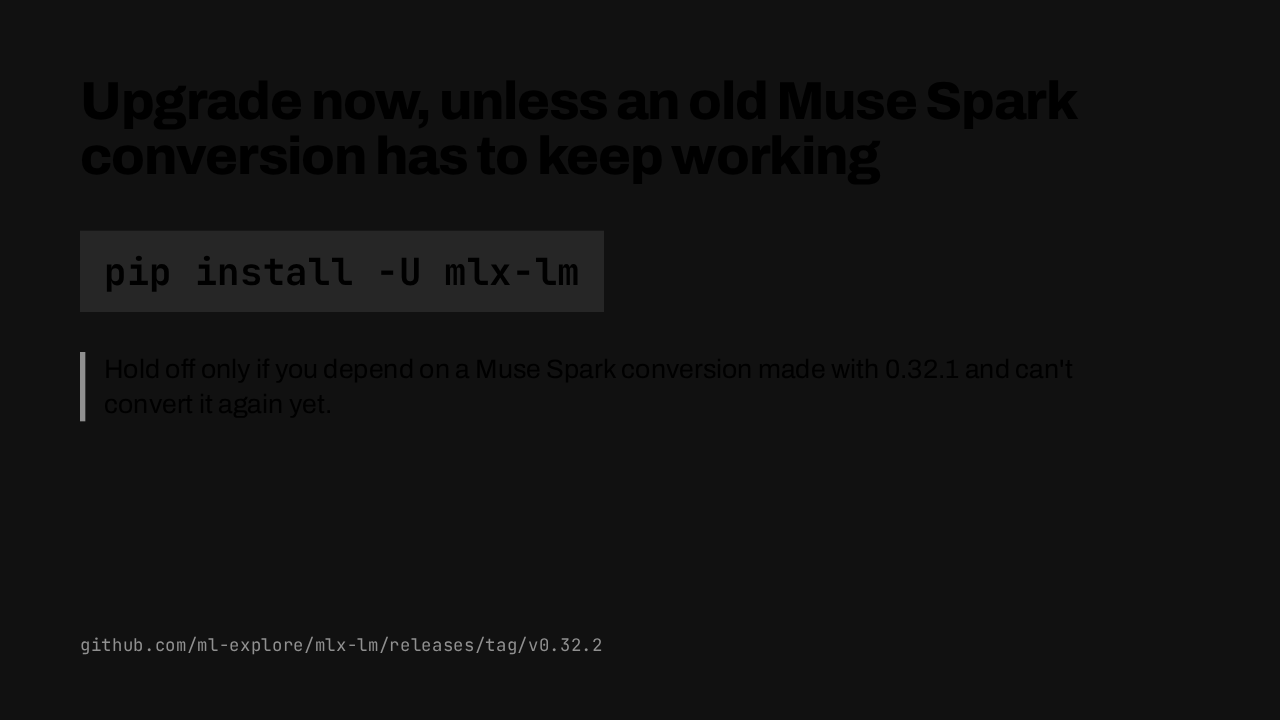
  9. To upgrade, run pip install with the upgrade flag. The one reason to wait is a Muse Spark conversion made with 0.32.1 that you can't convert again yet. Everyone else gets the MiMo-V2-Flash value scale and correct padded prompts in state-space models. And mlx-lm 0.32.2 loads Muse Spark from its Hugging Face checkpoint.
    Slide text

    Upgrade now, unless an old Muse Spark conversion has to keep working

    pip install -U mlx-lm

    Hold off only if you depend on a Muse Spark conversion made with 0.32.1 and can't convert it again yet.

    github.com/ml-explore/mlx-lm/releases/tag/v0.32.2

What happened in AI today, in your inbox

One short email each evening. Read it and you’re caught up.

Built in New York with ❤️