AssemblyAI TTS in LiveKit Agents
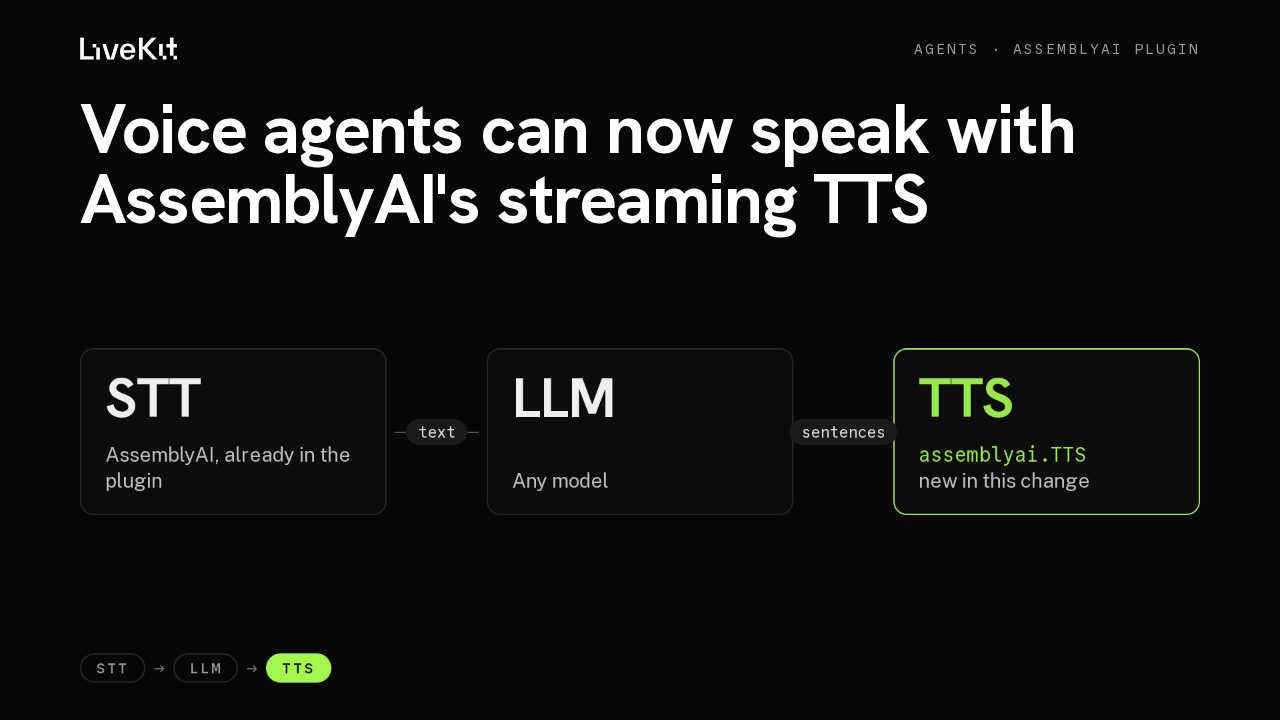
 Agents · AssemblyAI plugin
Voice agents can now speak with AssemblyAI's streaming TTS
new in this change
This change adds a text-to-speech class to LiveKit's AssemblyAI plugin. It runs on assemblyai-tts-1, AssemblyAI's first text-to-speech model, and it streams. Audio starts as soon as the first sentence of the LLM's reply arrives. The plugin already handled speech-to-text, so one provider can now sit at both ends of a voice agent's pipeline.
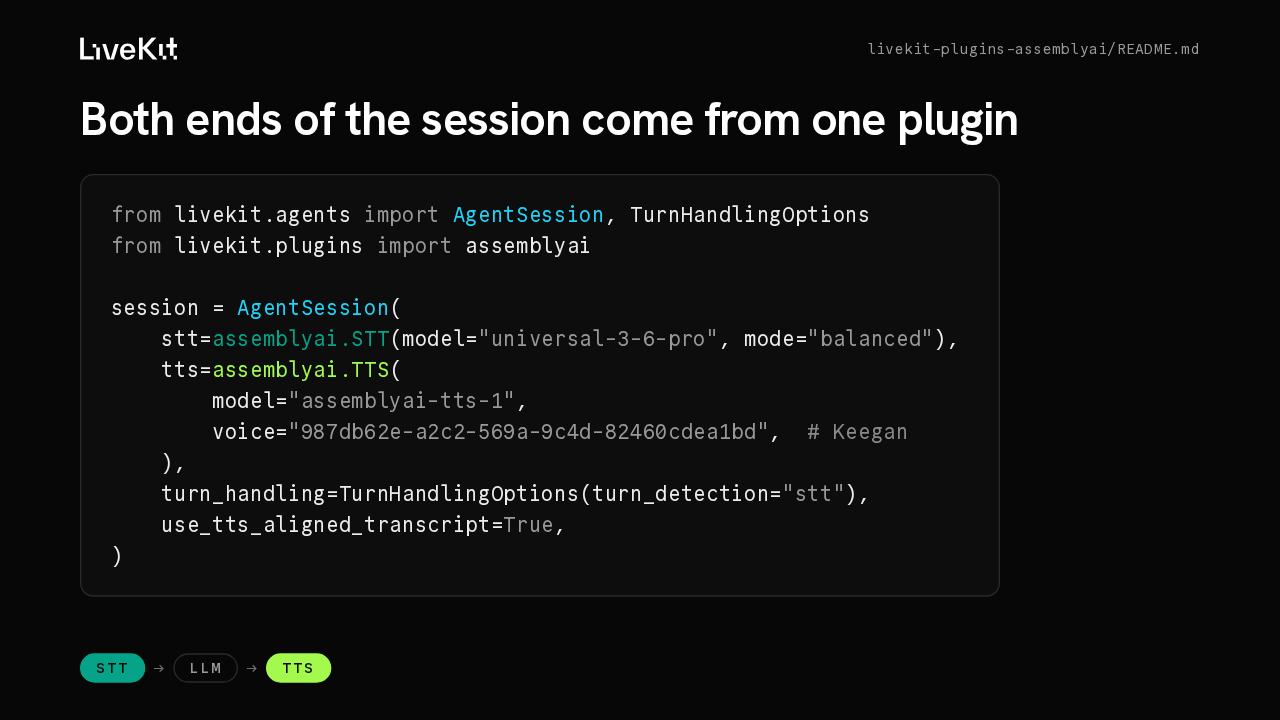
The session, from the README
livekit-plugins-assemblyai/README.mdBoth ends of the session come from one plugin
from livekit.agents import AgentSession, TurnHandlingOptions
from livekit.plugins import assemblyai

session = AgentSession(
    stt=assemblyai.STT(model="universal-3-6-pro", mode="balanced"),
    tts=assemblyai.TTS(
        model="assemblyai-tts-1",
        voice="987db62e-a2c2-569a-9c4d-82460cdea1bd",  # Keegan
    ),
    turn_handling=TurnHandlingOptions(turn_detection="stt"),
    use_tts_aligned_transcript=True,
)Here's the session from the plugin's new README. Speech-to-text was already AssemblyAI's. The new TTS class takes a model and a voice id, and this one is Keegan, the default voice. Turn detection comes from the speech-to-text side, and the aligned transcript flag tells LiveKit to use the TTS word timings.
What the model brings
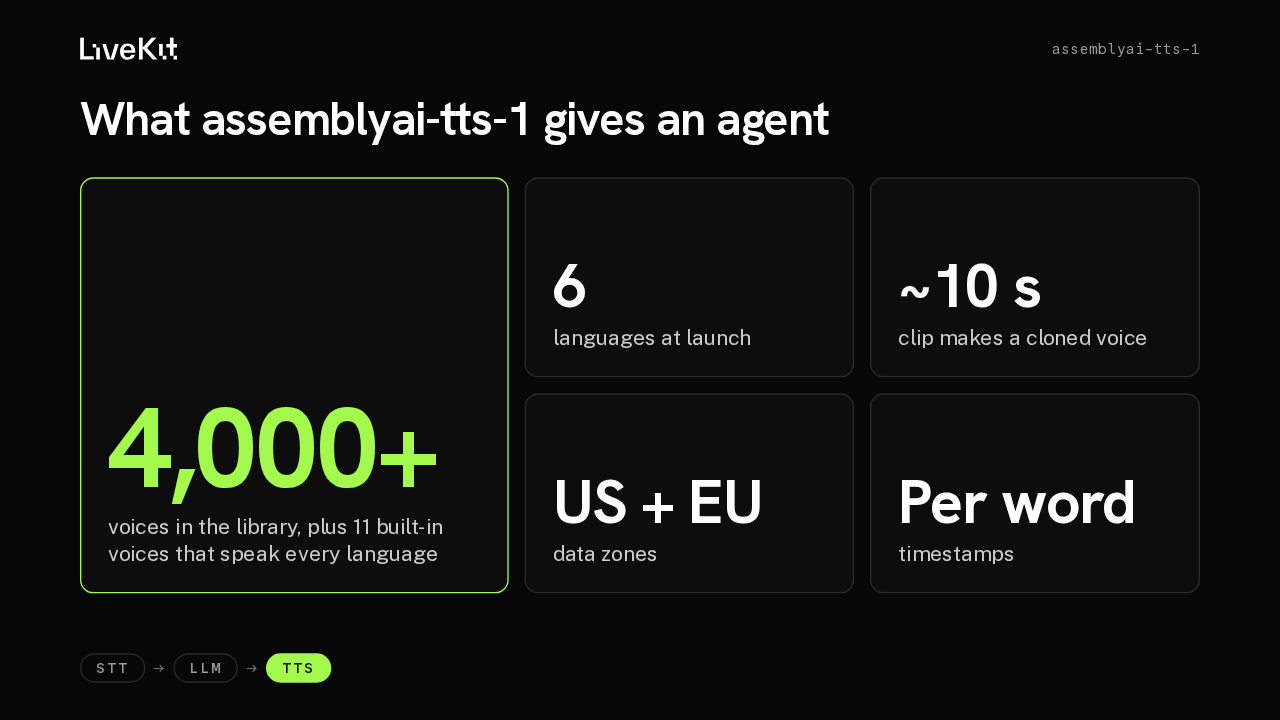
assemblyai-tts-1What assemblyai-tts-1 gives an agent
The model is built for voice agents and sounds like a person on the phone. The library holds more than four thousand voices, and eleven built-in voices speak every supported language. English, Spanish, German, French, Italian and Portuguese ship first. A clip of about ten seconds gives you a cloned voice right away, delivery follows the emotion of the text, and there are US and EU data zones.
One request per sentence, one pooled session
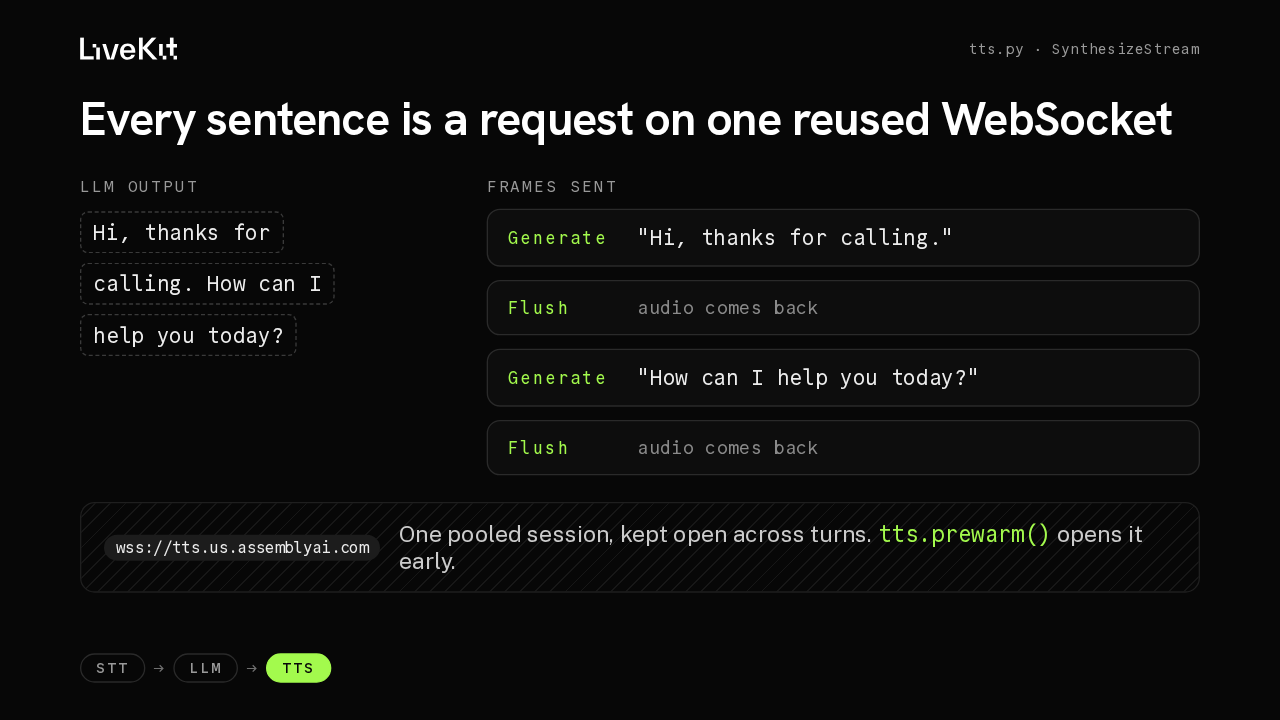
tts.py · SynthesizeStreamEvery sentence is a request on one reused WebSocket
This exchange comes from the plugin's tests. The LLM streams its reply in fragments. The plugin cuts them into sentences and sends each one as its own Generate and Flush, so the first sentence is already speaking while the second is being written. It all rides one pooled session that stays open across turns. AssemblyAI meters new sessions per account, and a reused one skips the handshake. Calling prewarm opens it before the first reply.
Barge-in without reconnecting
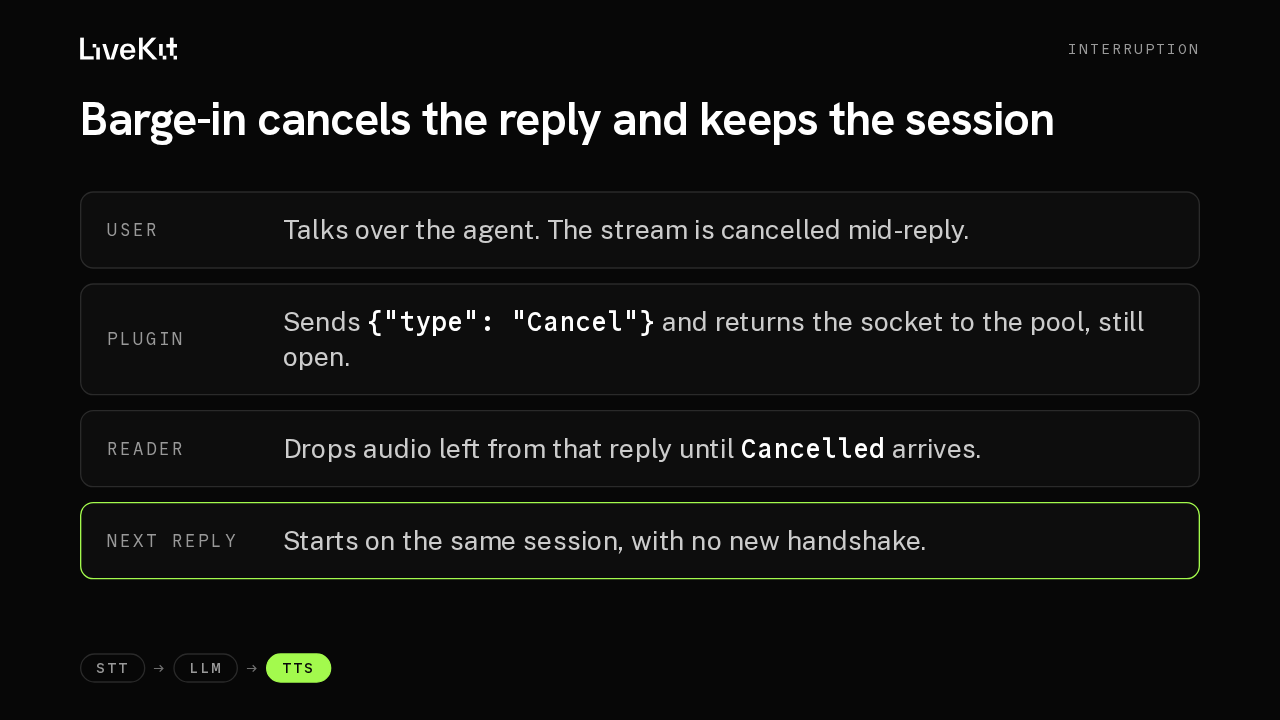
InterruptionBarge-in cancels the reply and keeps the session
When the user talks over the agent, the stream is cancelled in the middle of a reply. The plugin sends a Cancel frame and hands the socket back to the pool, still open. Audio the server already sent for that reply is dropped by the socket's reader until a Cancelled frame confirms the server has moved on. The next reply goes out on the same session, without a reconnect.
Word-aligned transcripts
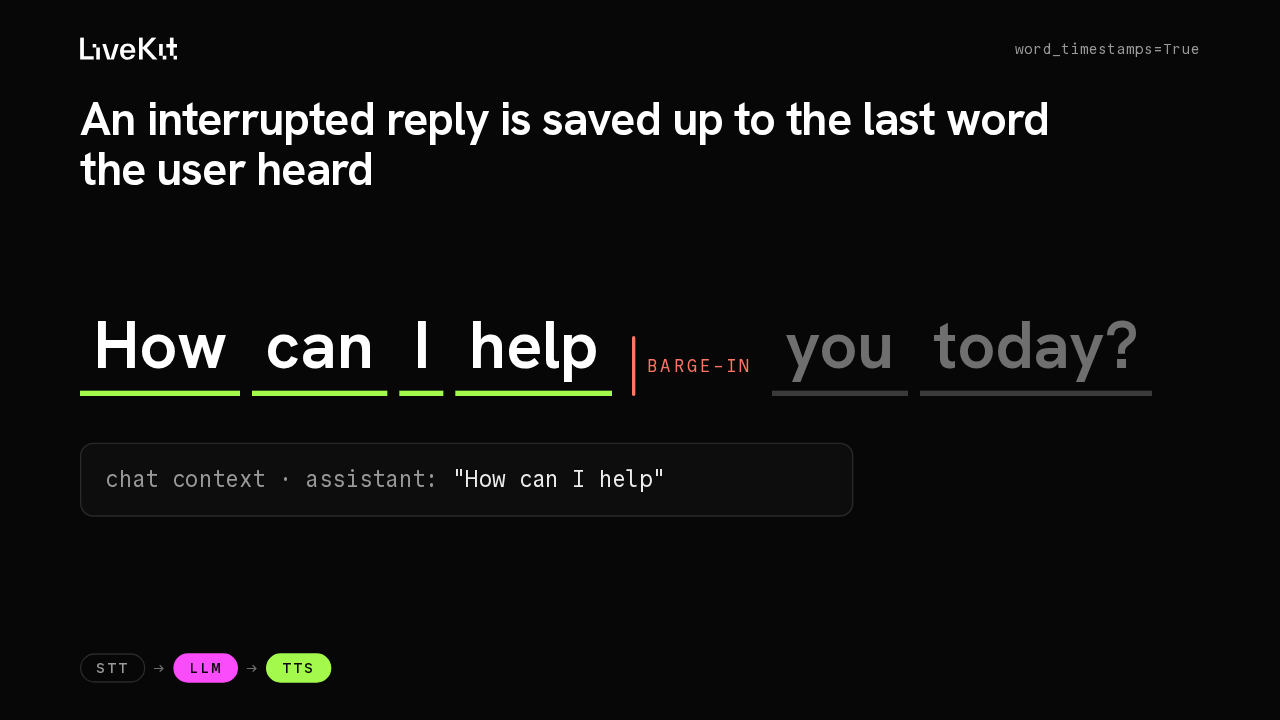
word_timestamps=TrueAn interrupted reply is saved up to the last word the user heard
Word timestamps are on by default. Every synthesized word comes back with its timing, and the plugin publishes them as an aligned transcript. With the session's aligned transcript option turned on, an interrupted reply goes into the chat context only up to the word the user actually heard, so the LLM's history matches the call.
Retries and text limits
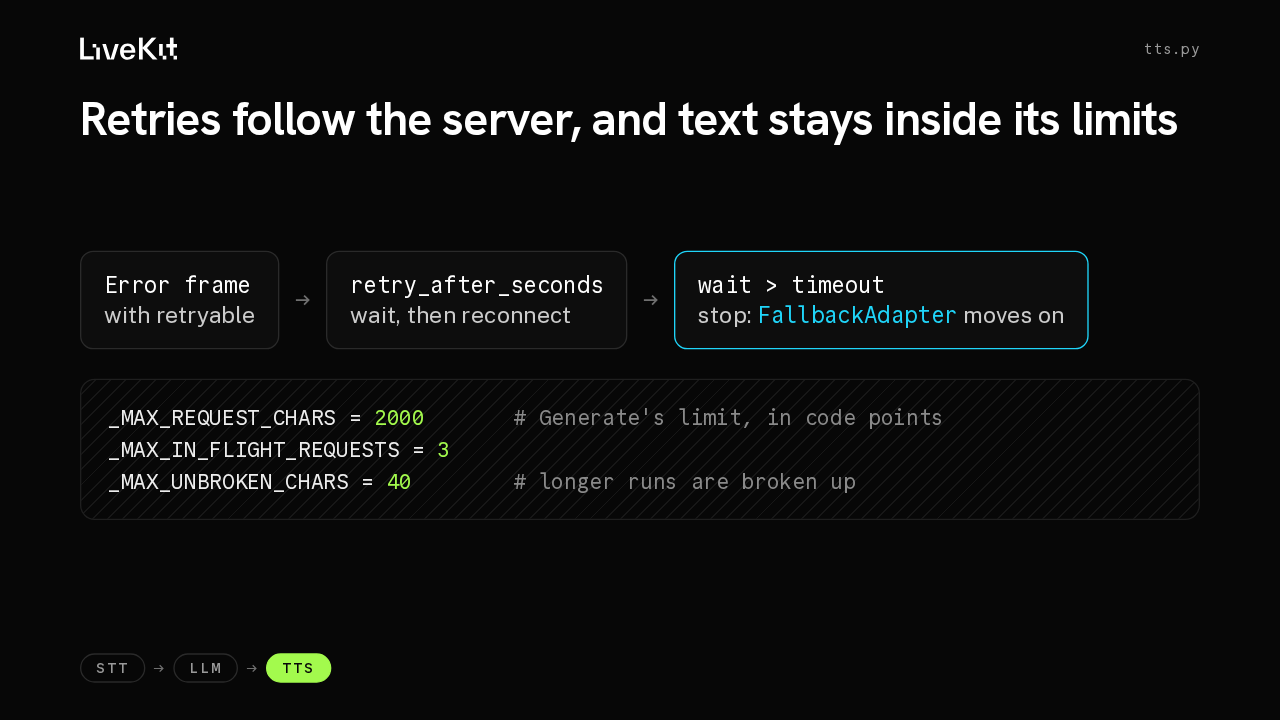
tts.pyRetries follow the server, and text stays inside its limits
_MAX_REQUEST_CHARS = 2000       # Generate's limit, in code points
_MAX_IN_FLIGHT_REQUESTS = 3
_MAX_UNBROKEN_CHARS = 40 # longer runs are broken upError frames carry a retryable flag and sometimes a retry-after value, and the plugin follows both. If the server asks for a wait longer than the connect timeout, retries stop, so a FallbackAdapter can move on to another TTS. Each request stays within two thousand characters, with at most three in flight. A run of more than forty characters without a space, like a hash, gets broken up so the server accepts it.
What review changed
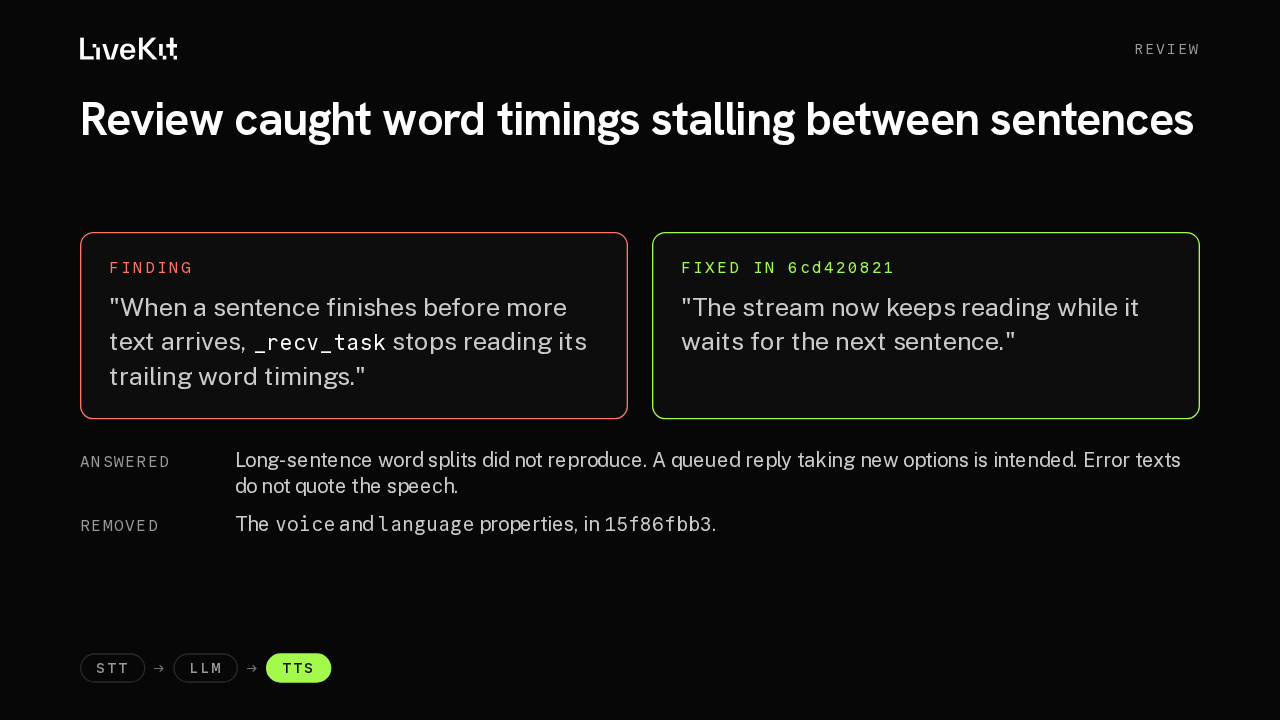
ReviewReview caught word timings stalling between sentences
The automated reviewer found a real gap. When a sentence finished before more text arrived, its trailing word timings sat unread, and an interruption in that pause lost them. The fix keeps the stream reading while it waits, with a new test for that case. Three other findings were answered in the thread, and at a maintainer's request the class now exposes only model and provider, like the other TTS plugins.
Evidence
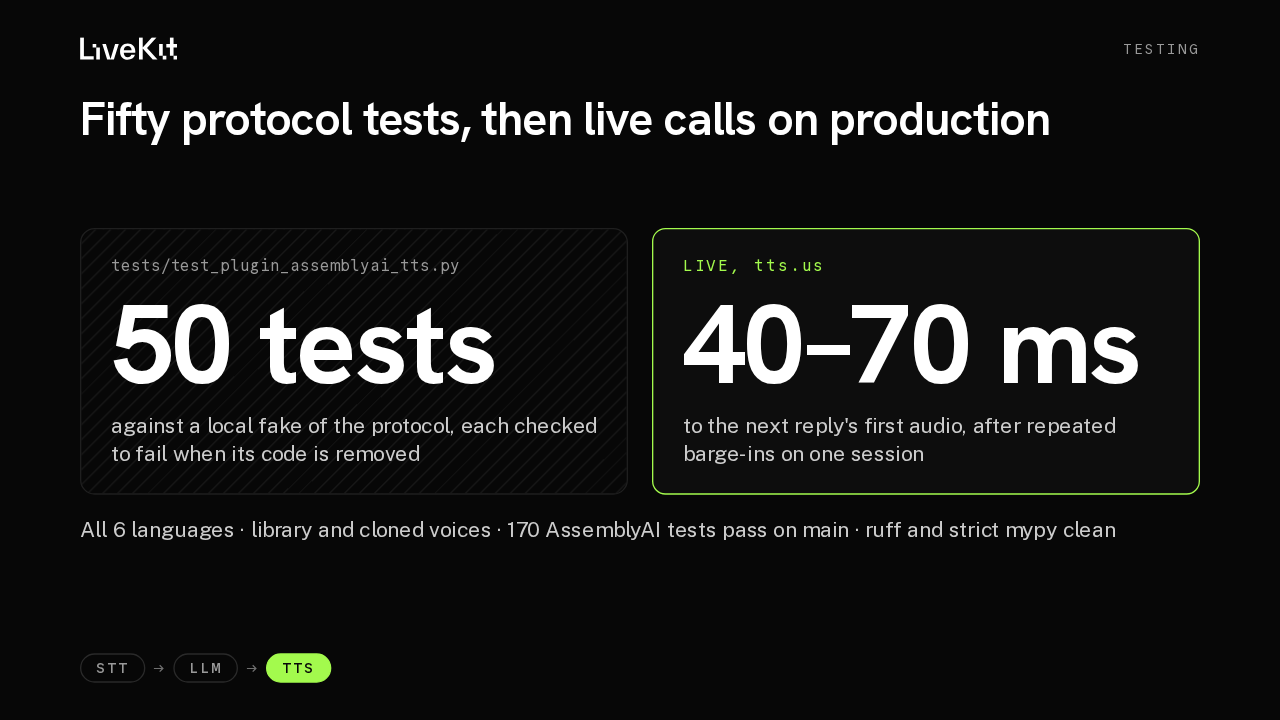
TestingFifty protocol tests, then live calls on production
The new test file runs fifty tests against a local fake of AssemblyAI's protocol, covering pooling, barge-in races, retries, session expiry, text splitting and word timings, and each one was checked to fail when the code it covers is removed. In live calls against production and the sandbox, all six languages played with library and cloned voices, and after repeated barge-ins on one session the next reply's first audio arrived in forty to seventy milliseconds.
Try it
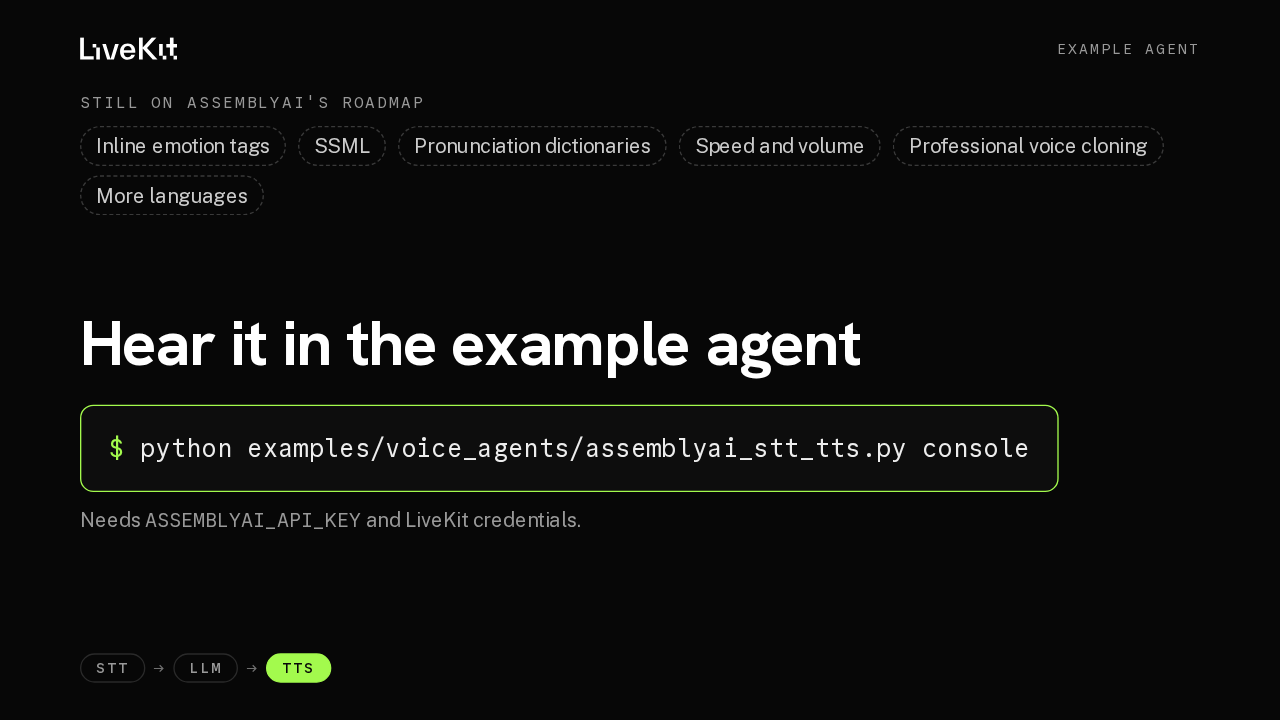
Example agentHear it in the example agent
Needs ASSEMBLYAI_API_KEY and LiveKit credentials.
Some controls are still on AssemblyAI's roadmap, including inline emotion tags, SSML, pronunciation dictionaries, and speed and volume. Voices and languages are plain strings, so new ones work without a plugin release. To hear it, run the new example agent in console mode with an AssemblyAI key. Voice agents can now speak with AssemblyAI's streaming TTS.