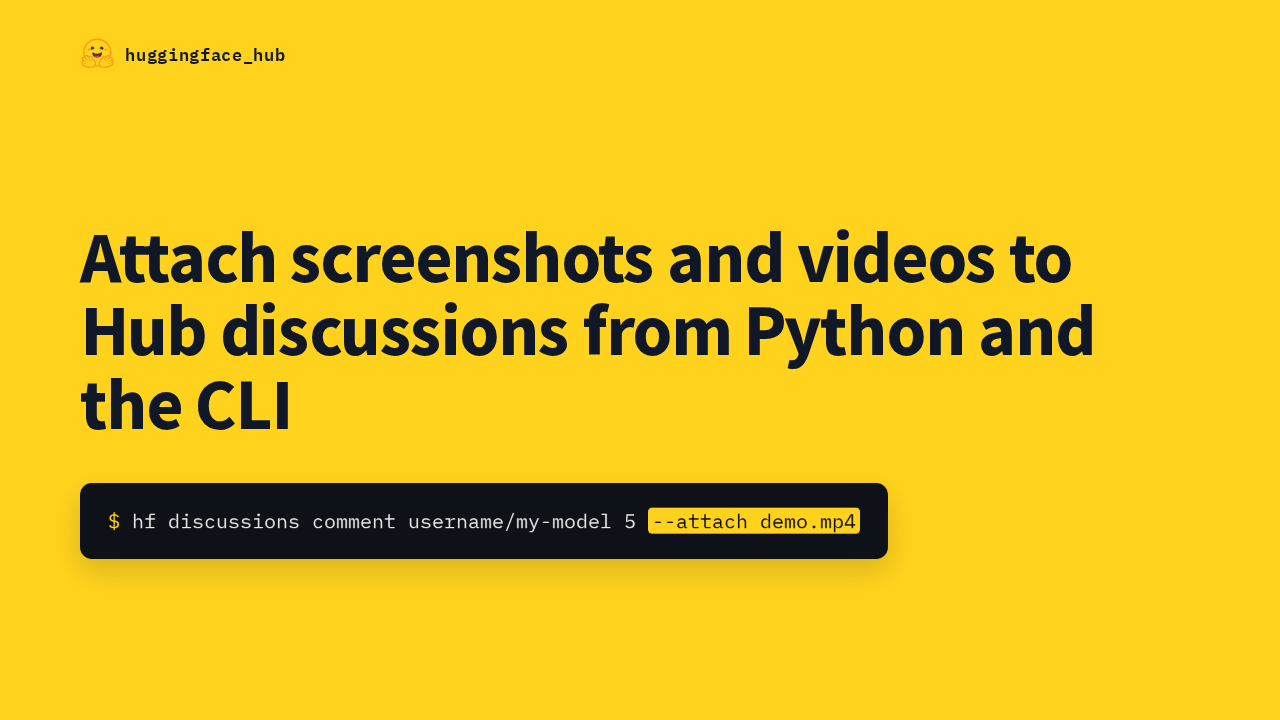
Version 2.3 makes recursive listings on large repos fast. A find over the Objaverse dataset, about 800,000 files, used to take 13 minutes. Now it takes about 20 seconds. The same glob and find calls get faster with no code changes.
Version 2.3 makes recursive listings on large repos fast. A find over the Objaverse dataset, about 800,000 files, used to take 13 minutes. Now it takes about 20 seconds. The same glob and find calls get faster with no code changes.
Slide text
huggingface_hub v2.3.0
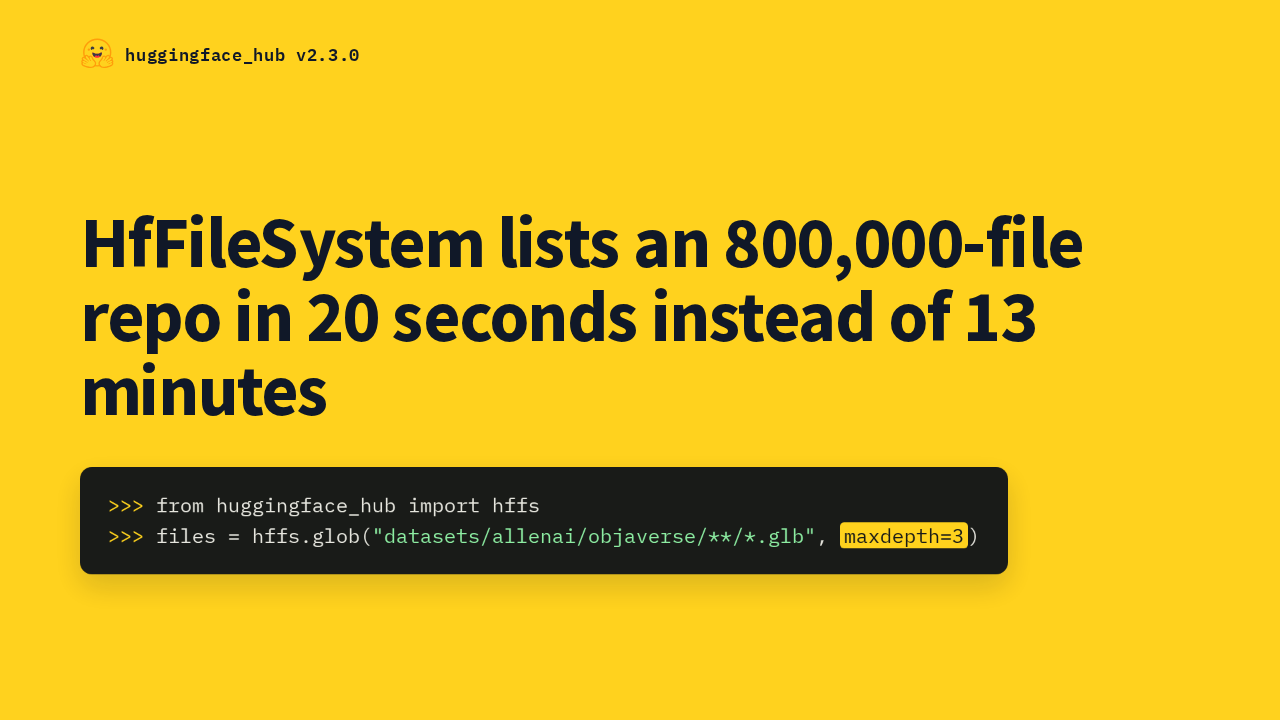
HfFileSystem lists an 800,000-file repo in 20 seconds instead of 13 minutes
>>> from huggingface_hub import hffs
>>> files = hffs.glob("datasets/allenai/objaverse/**/*.glb", maxdepth=3)
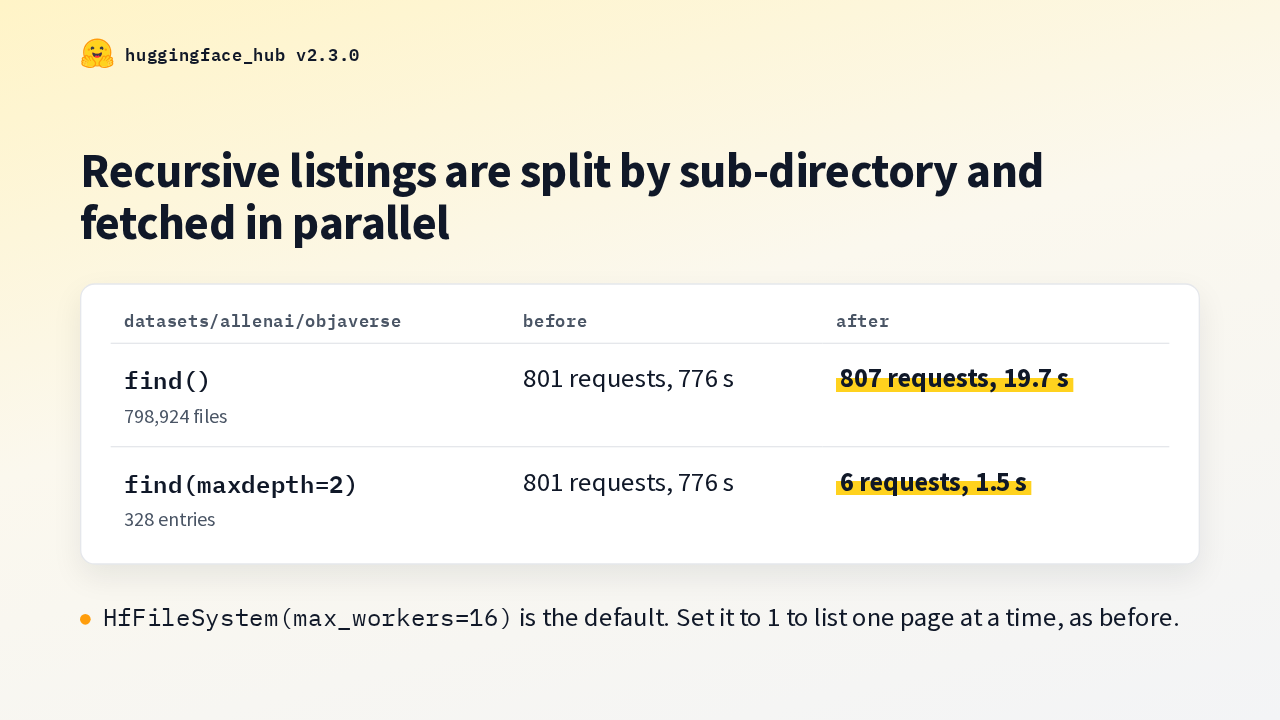
The Hub returns a file tree 1,000 entries at a time, one page after another. Now the listing is split by sub-directory and run in parallel. A full find makes about the same 800 requests in 20 seconds. With a max depth, it takes 6 requests and under 2 seconds. The new max workers argument sets the concurrency.
Slide text
huggingface_hub v2.3.0
Recursive listings are split by sub-directory and fetched in parallel
datasets/allenai/objaverse
before
after
find()
798,924 files
801 requests, 776 s
807 requests, 19.7 s
find(maxdepth=2)
328 entries
801 requests, 776 s
6 requests, 1.5 s
HfFileSystem(max_workers=16) is the default. Set it to 1 to list one page at a time, as before.
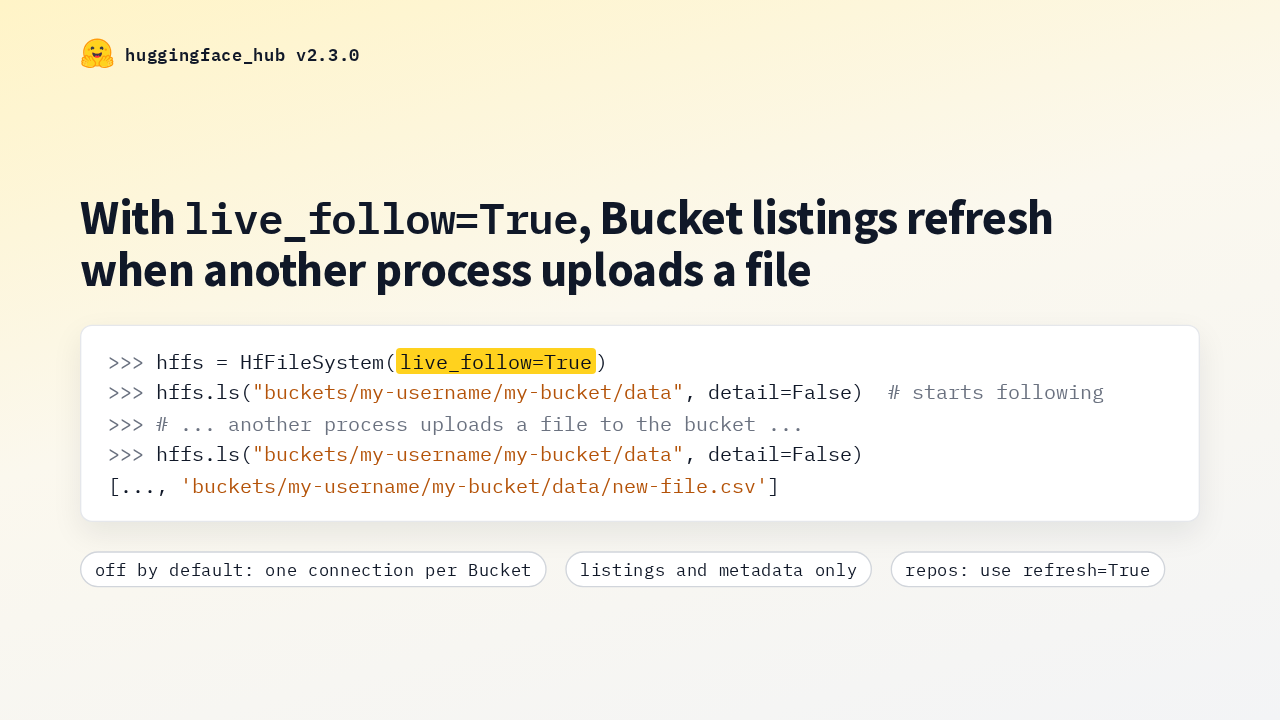
Cached listings used to miss files another process added to a Bucket. With live follow turned on, each listed Bucket gets a background connection that receives changes from the Hub and drops stale listings. It works through fsspec and pandas too. It's off by default, and it's for Buckets only.
Slide text
huggingface_hub v2.3.0
With live_follow=True, Bucket listings refresh when another process uploads a file
>>> hffs = HfFileSystem(live_follow=True)
>>> hffs.ls("buckets/my-username/my-bucket/data", detail=False) # starts following>>> # ... another process uploads a file to the bucket ...>>> hffs.ls("buckets/my-username/my-bucket/data", detail=False)
[..., 'buckets/my-username/my-bucket/data/new-file.csv']
off by default: one connection per Bucketlistings and metadata onlyrepos: use refresh=True
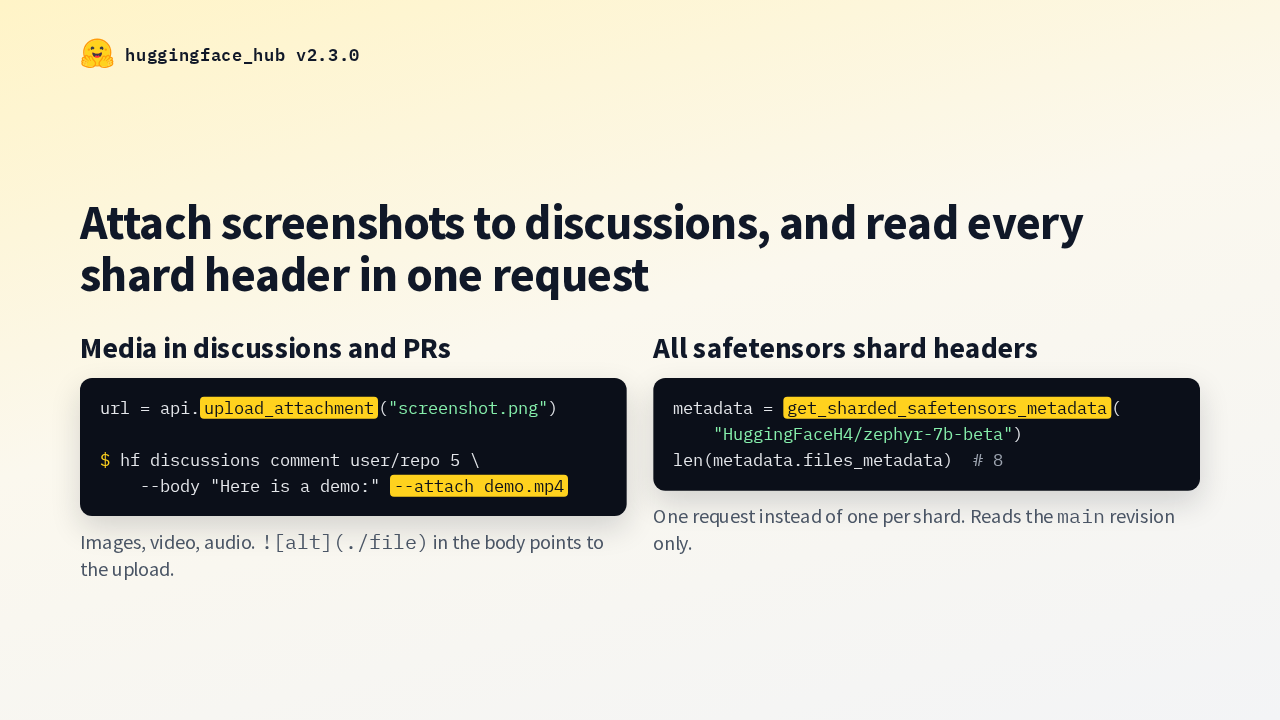
Two new calls. Upload attachment sends an image, video or audio file to the Hub and returns its URL, and the discussions commands take an attach option that embeds it. And get sharded safetensors metadata reads every shard header of a model in one request.
Slide text
huggingface_hub v2.3.0
Attach screenshots to discussions, and read every shard header in one request
Media in discussions and PRs
url = api.upload_attachment("screenshot.png")
$ hf discussions comment user/repo 5 \
--body "Here is a demo:" --attach demo.mp4
Images, video, audio.  in the body points to the upload.
One request instead of one per shard. Reads the main revision only.
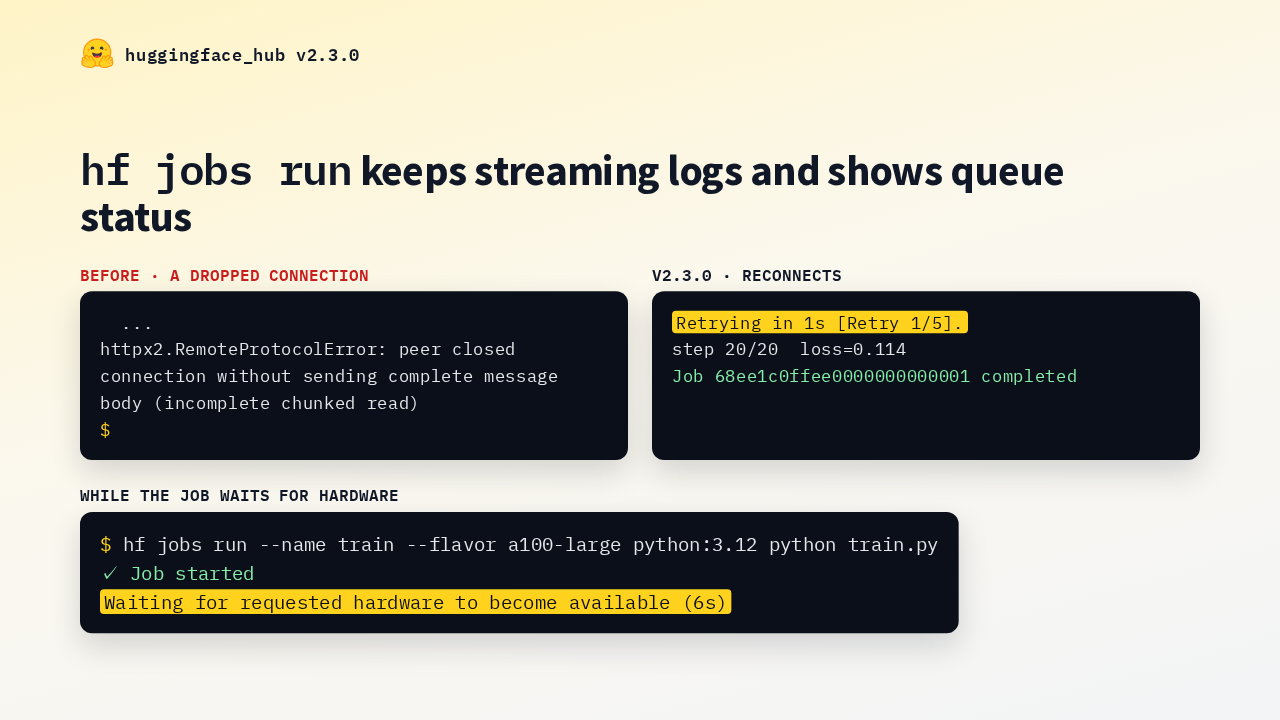
The jobs run command got two fixes. It used to crash after a few dropped log connections. Now it reconnects until the Job finishes, and control C exits right away with a hint. While a Job waits for hardware, it now shows the Hub's status message and how long it has waited.
Slide text
huggingface_hub v2.3.0
hf jobs run keeps streaming logs and shows queue status
Before · a dropped connection
...
httpx2.RemoteProtocolError: peer closed connection without sending complete message body (incomplete chunked read)
$
$ hf jobs run --name train --flavor a100-large python:3.12 python train.py
✓ Job startedWaiting for requested hardware to become available (6s)
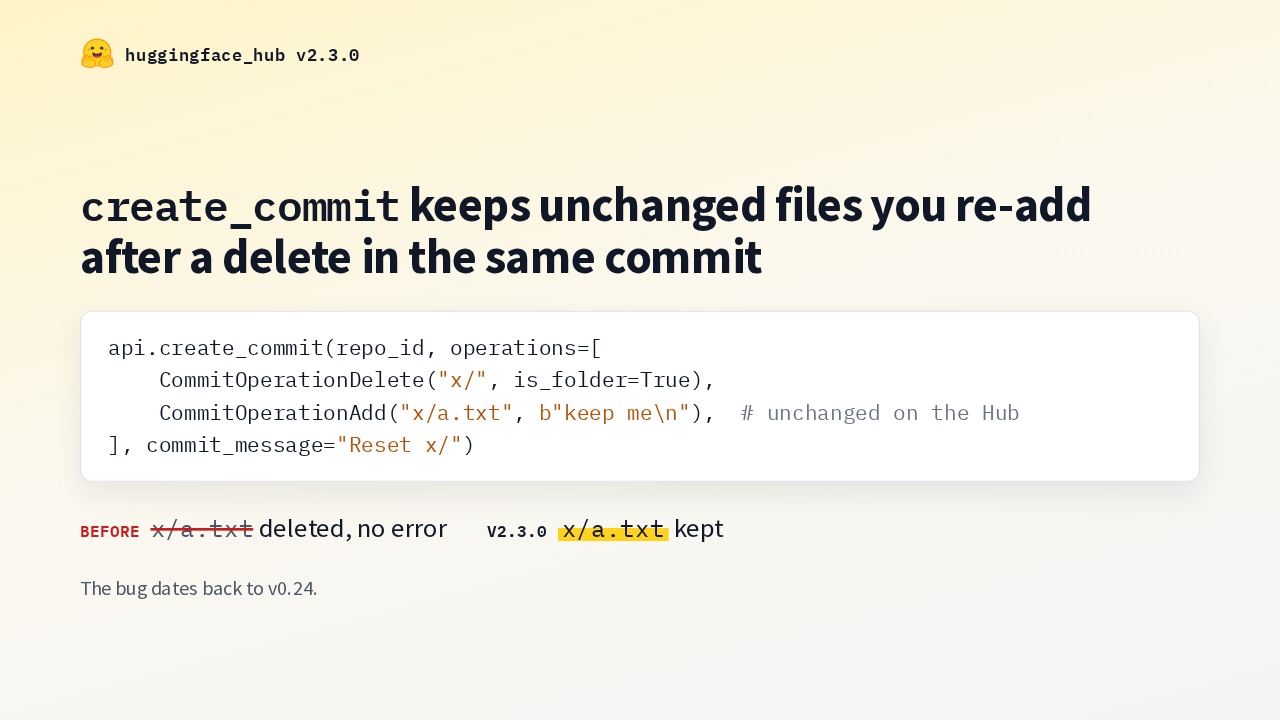
This fix is about lost data. Create commit skips uploads whose content is already on the Hub. So a commit that deleted a folder and pushed the same files back sent only the delete. The files vanished without an error, since version 0.24. Now they're kept.
Slide text
huggingface_hub v2.3.0
create_commit keeps unchanged files you re-add after a delete in the same commit
api.create_commit(repo_id, operations=[
CommitOperationDelete("x/", is_folder=True),
CommitOperationAdd("x/a.txt", b"keep me\n"), # unchanged on the Hub
], commit_message="Reset x/")
Beforex/a.txt deleted, no errorv2.3.0x/a.txt kept
The bug dates back to v0.24.
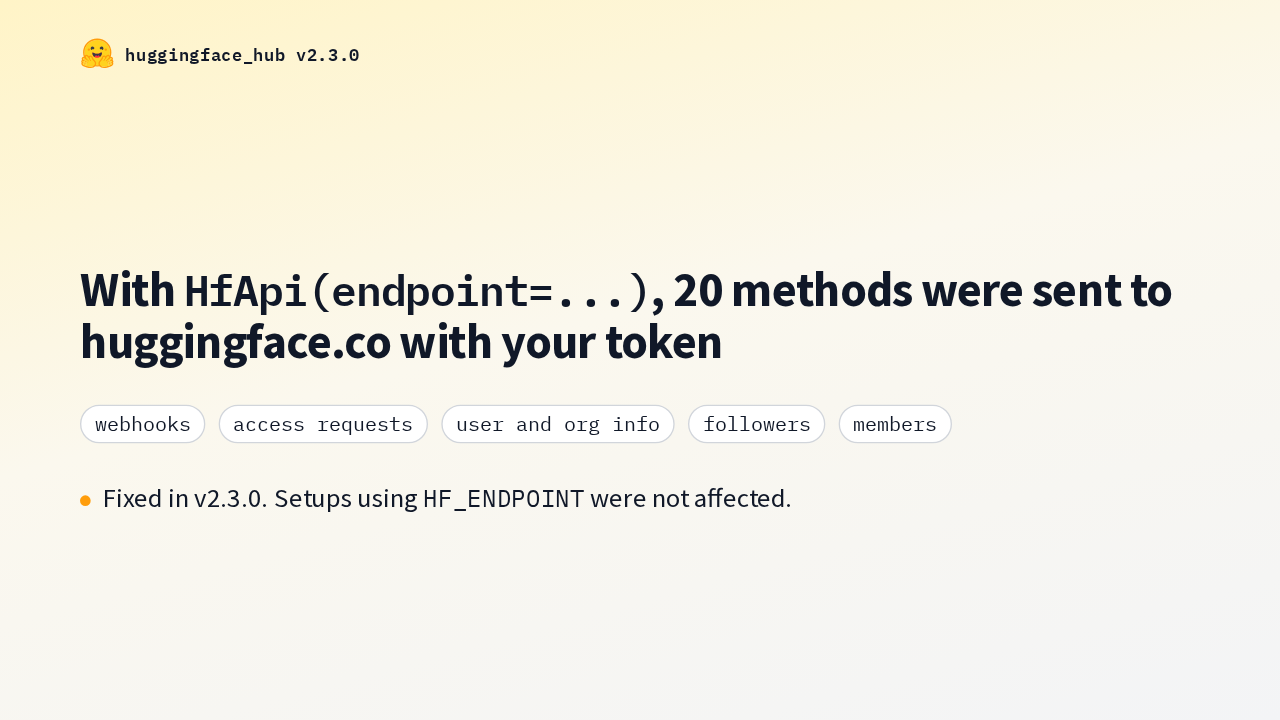
If you set a custom endpoint on HfApi, 20 methods ignored it. Webhooks, access requests, user and org info, followers and members went to huggingface dot co with that instance's token. Now they go to your endpoint. If you set the endpoint through the HF_ENDPOINT environment variable instead, you were not affected.
Slide text
huggingface_hub v2.3.0
With HfApi(endpoint=...), 20 methods were sent to huggingface.co with your token
webhooksaccess requestsuser and org infofollowersmembers
Fixed in v2.3.0. Setups using HF_ENDPOINT were not affected.
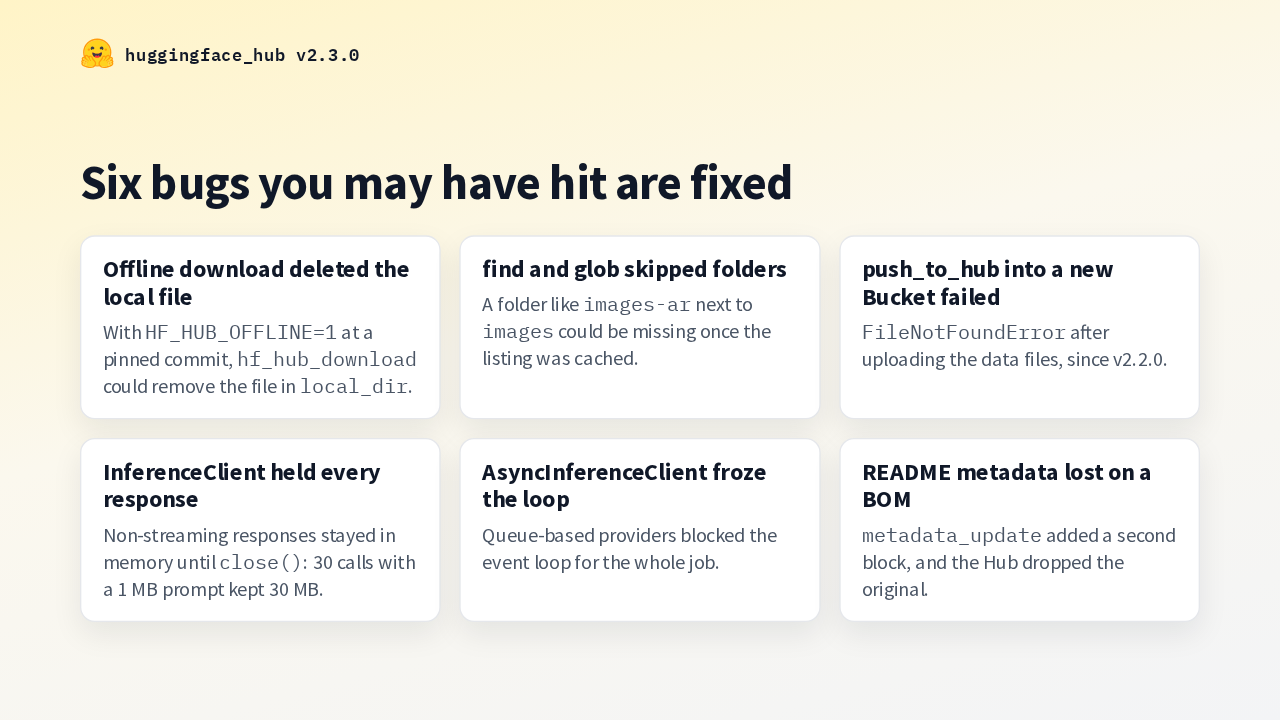
These are fixed too. Offline downloads at a pinned commit could delete your local file. Cached listings could make glob skip a folder. Pushing a dataset into a new Bucket failed. And a reused inference client kept every non-streaming response in memory.
Slide text
huggingface_hub v2.3.0
Six bugs you may have hit are fixed
Offline download deleted the local file
With HF_HUB_OFFLINE=1 at a pinned commit, hf_hub_download could remove the file in local_dir.
find and glob skipped folders
A folder like images-ar next to images could be missing once the listing was cached.
push_to_hub into a new Bucket failed
FileNotFoundError after uploading the data files, since v2.2.0.
InferenceClient held every response
Non-streaming responses stayed in memory until close(): 30 calls with a 1 MB prompt kept 30 MB.
AsyncInferenceClient froze the loop
Queue-based providers blocked the event loop for the whole job.
README metadata lost on a BOM
metadata_update added a second block, and the Hub dropped the original.
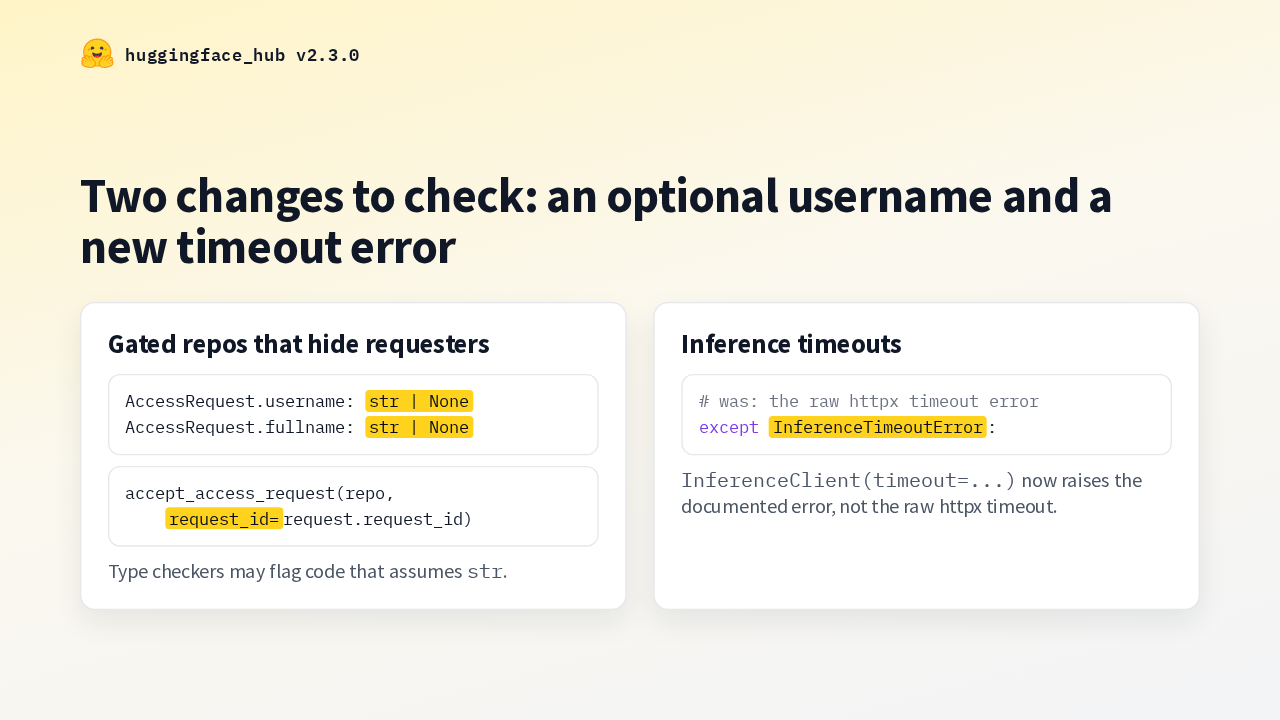
Two changes need a look before you upgrade. Gated repos can now hide who's requesting access, so access requests carry a request ID to accept by, and the username is typed as optional, which type checkers may flag. And inference timeouts now raise inference timeout error, so code that catches the raw httpx timeout should catch that instead.
Slide text
huggingface_hub v2.3.0
Two changes to check: an optional username and a new timeout error
# was: the raw httpx timeout errorexceptInferenceTimeoutError:
InferenceClient(timeout=...) now raises the documented error, not the raw httpx timeout.
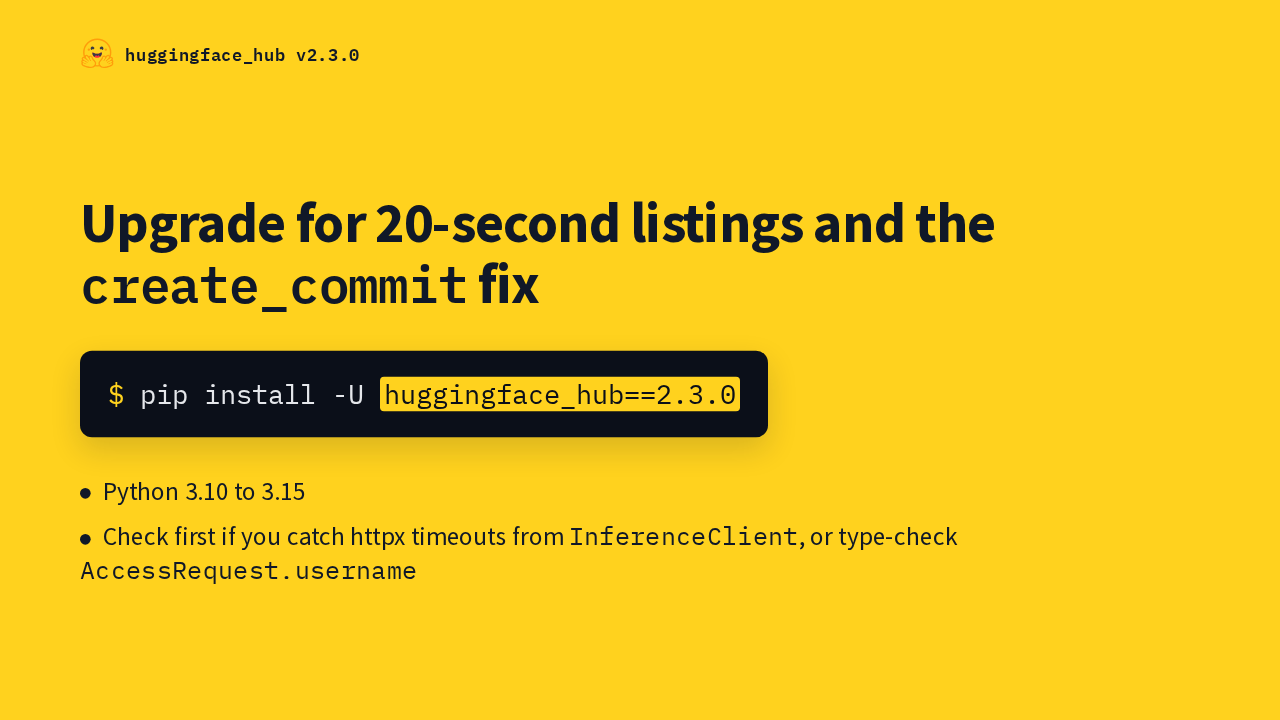
Live follow is opt-in, so most people will notice the faster listings and the commit fix first. Upgrade with pip. Python 3.15 is now supported. First, check code that catches inference timeouts or assumes a username is set. Then the Objaverse listing that took 13 minutes takes 20 seconds.
Slide text
huggingface_hub v2.3.0
Upgrade for 20-second listings and the create_commit fix
$ pip install -U huggingface_hub==2.3.0
Python 3.10 to 3.15
Check first if you catch httpx timeouts from InferenceClient, or type-check AccessRequest.username
 0:00Large repos list in seconds
 0:18Listing objaverse, before and after
 0:40live_follow for Buckets
 0:58upload_attachment and sharded safetensors metadata
 1:16hf jobs run keeps streaming
 1:34create_commit keeps re-added files
 1:51Custom endpoint respected
 2:12Fixes you may have hit
 2:29What could break
 2:51Upgrade