The encoder on the Neural Engine
[00:00:00.000 --> 00:00:18.292]
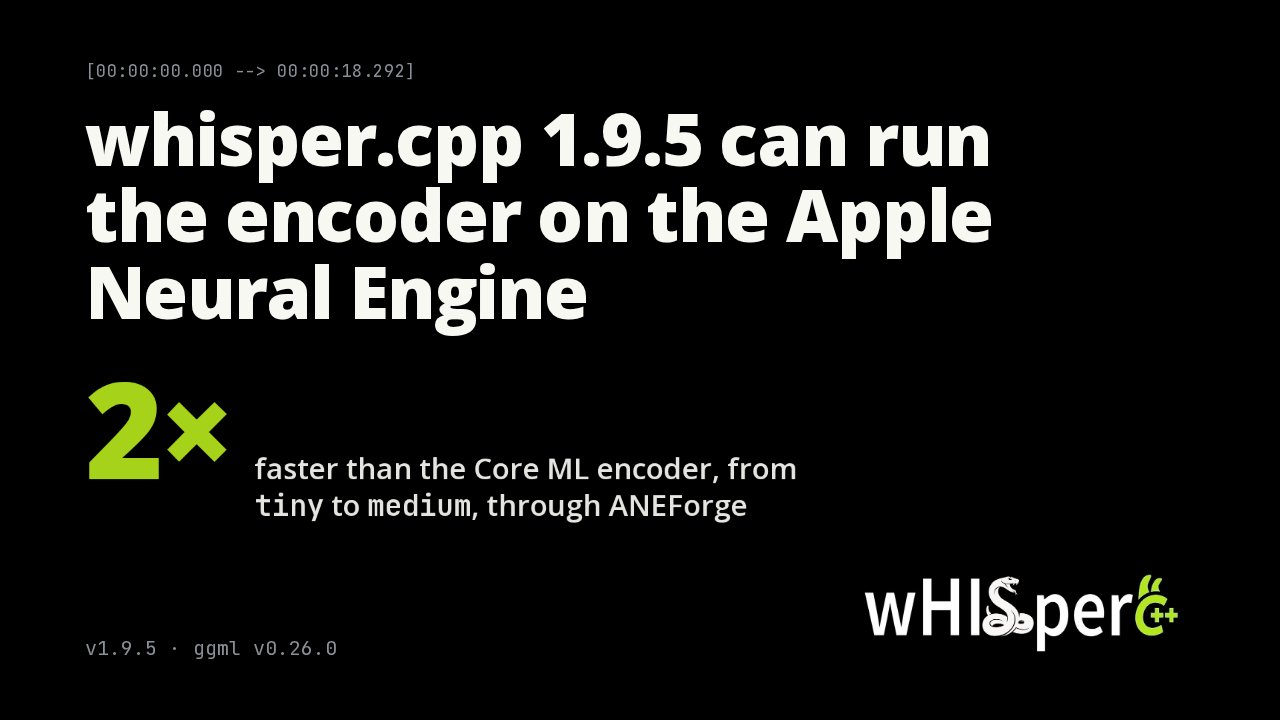
whisper.cpp 1.9.5 can run the encoder on the Apple Neural Engine
v1.9.5 · ggml v0.26.0

whisper.cpp 1.9.5 is a maintenance release on ggml 0.26, with one new option for Macs. On Apple Silicon, the encoder can now run on the Neural Engine through ANEForge, skipping Core ML. It's about twice as fast as the Core ML encoder, from tiny to medium.
Encoder time per call
[00:00:18.292 --> 00:00:39.277]
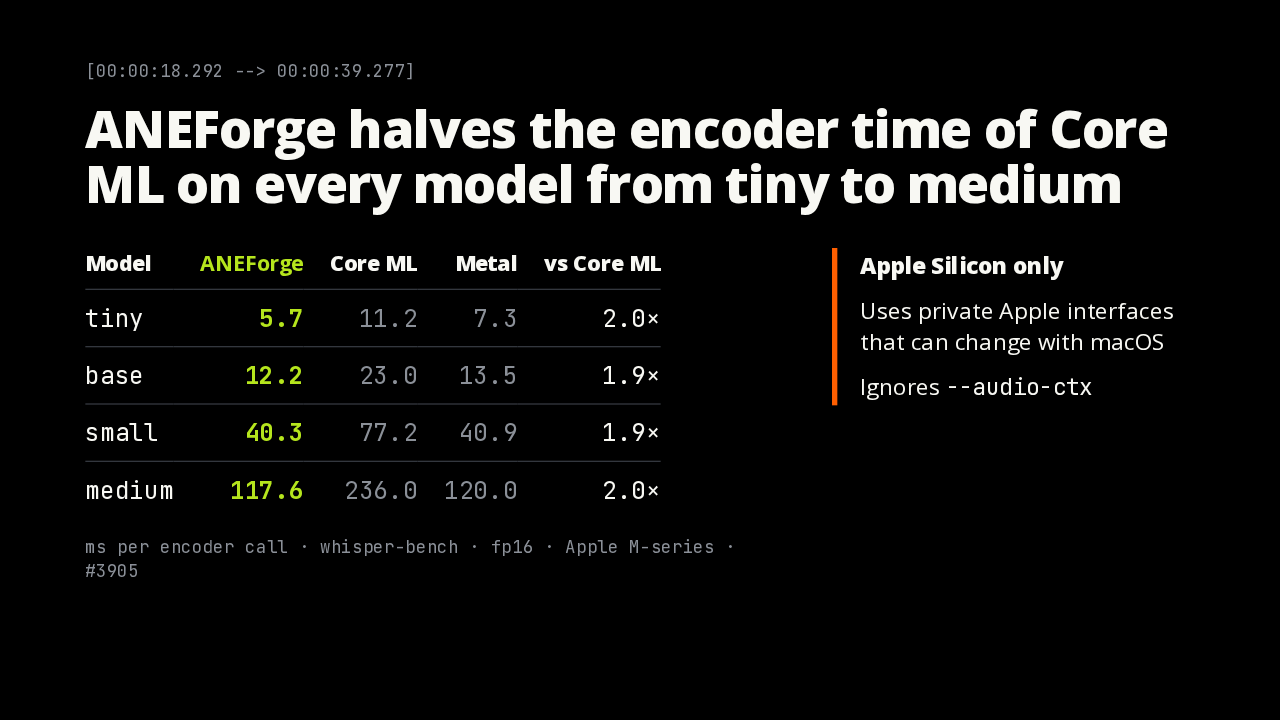
ANEForge halves the encoder time of Core ML on every model from tiny to medium
| Model | ANEForge | Core ML | Metal | vs Core ML |
|---|---|---|---|---|
| tiny | 5.7 | 11.2 | 7.3 | 2.0× |
| base | 12.2 | 23.0 | 13.5 | 1.9× |
| small | 40.3 | 77.2 | 40.9 | 1.9× |
| medium | 117.6 | 236.0 | 120.0 | 2.0× |
ms per encoder call · whisper-bench · fp16 · Apple M-series · #3905
Apple Silicon only
Uses private Apple interfaces that can change with macOS
Ignores --audio-ctx
Here's the encoder time per call, in milliseconds. On every model from tiny to medium, ANEForge takes about half the time of Core ML, and roughly matches the Metal GPU encoder. It's Apple Silicon only, it relies on private Apple interfaces that can change with macOS, and it ignores the audio context option.
Turning it on
[00:00:39.277 --> 00:01:02.569]
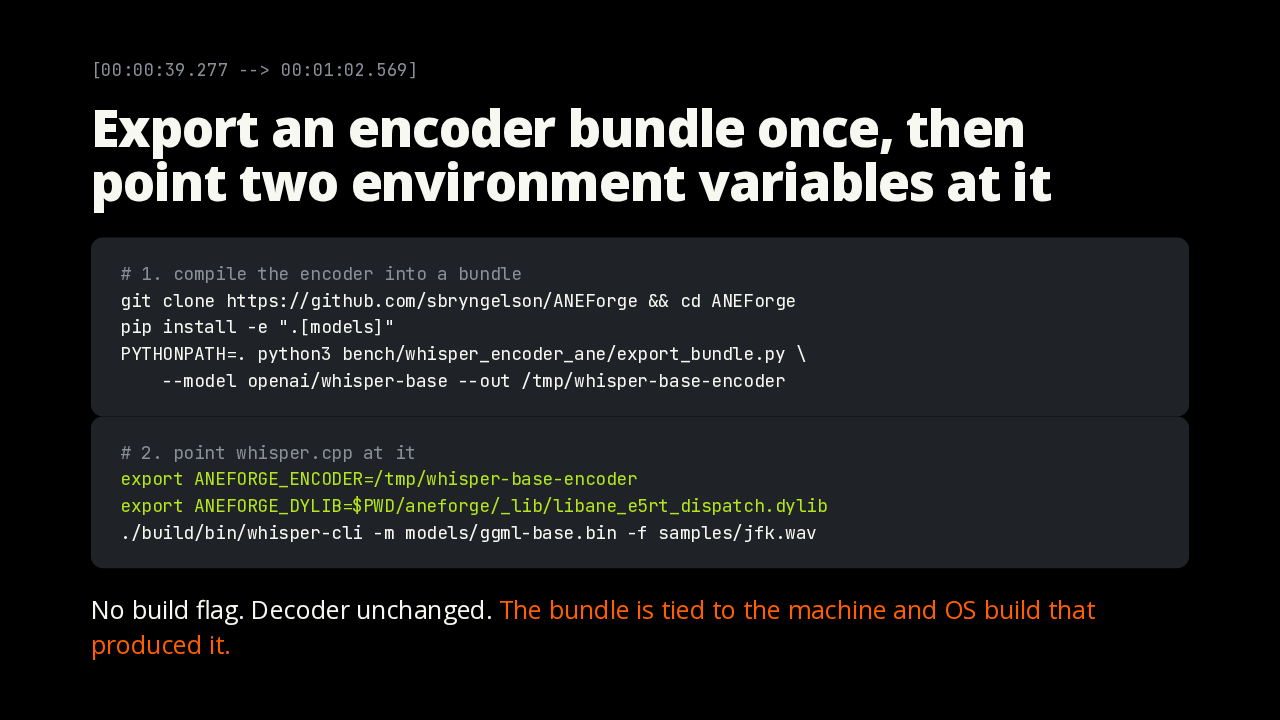
Export an encoder bundle once, then point two environment variables at it
No build flag. Decoder unchanged. The bundle is tied to the machine and OS build that produced it.
First you compile the encoder into a bundle with the Python tools in the ANEForge repository. Then you set two environment variables, for the bundle and the dispatch library, and run whisper-cli as usual. There's no build flag. The bundle only works on the machine and OS build that made it, so a macOS update means a new export.
Fixes
[00:01:02.569 --> 00:01:21.631]
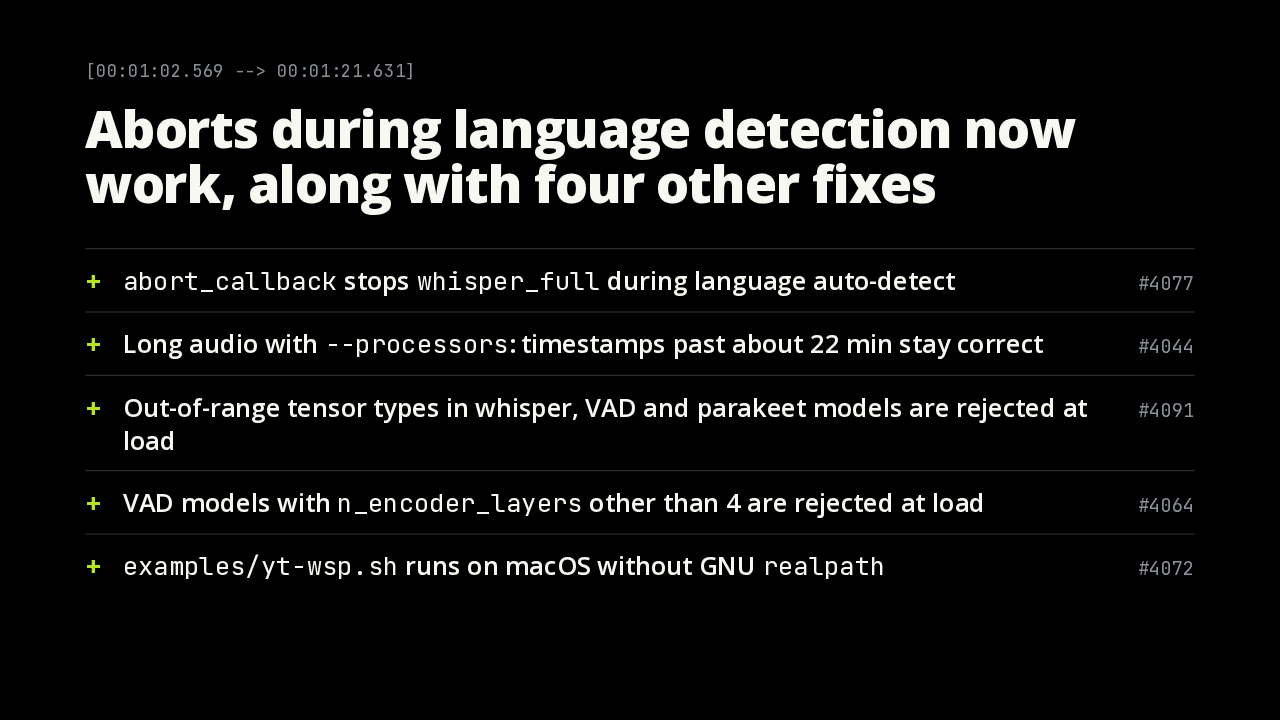
Aborts during language detection now work, along with four other fixes
The abort callback now also covers language detection. Long files run with several processors no longer get corrupted timestamps past about 22 minutes, mostly a Windows problem. Malformed model and VAD files are rejected at load instead of crashing. And the yt-dlp transcription script now runs on macOS.
ggml 0.26.0
[00:01:21.631 --> 00:01:37.231]
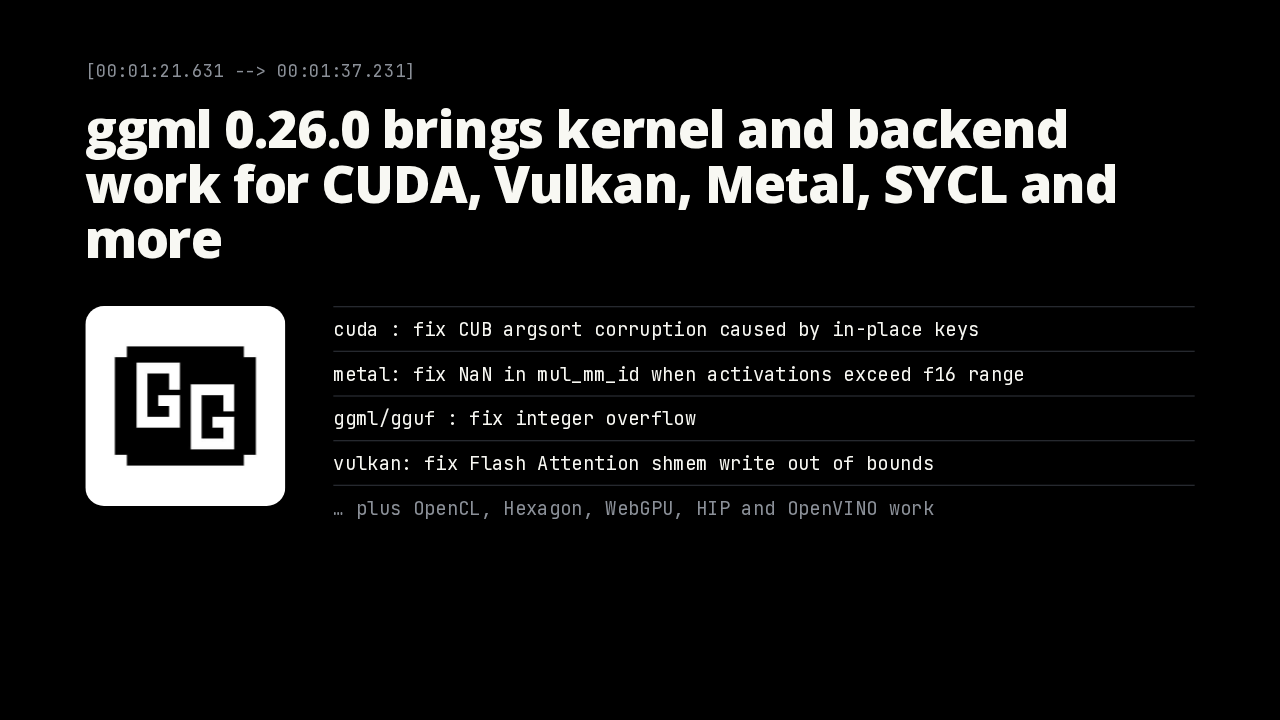
ggml 0.26.0 brings kernel and backend work for CUDA, Vulkan, Metal, SYCL and more

cuda : fix CUB argsort corruption caused by in-place keys
metal: fix NaN in mul_mm_id when activations exceed f16 range
ggml/gguf : fix integer overflow
vulkan: fix Flash Attention shmem write out of bounds
… plus OpenCL, Hexagon, WebGPU, HIP and OpenVINO work
Most of the commits come from the ggml sync to 0.26. That's kernel and backend work across the GPU and accelerator backends, including fixes for an argsort corruption on CUDA and NaNs on Metal. You get it by rebuilding.
Breaking: whisper-cli exit codes
[00:01:37.231 --> 00:02:00.139]
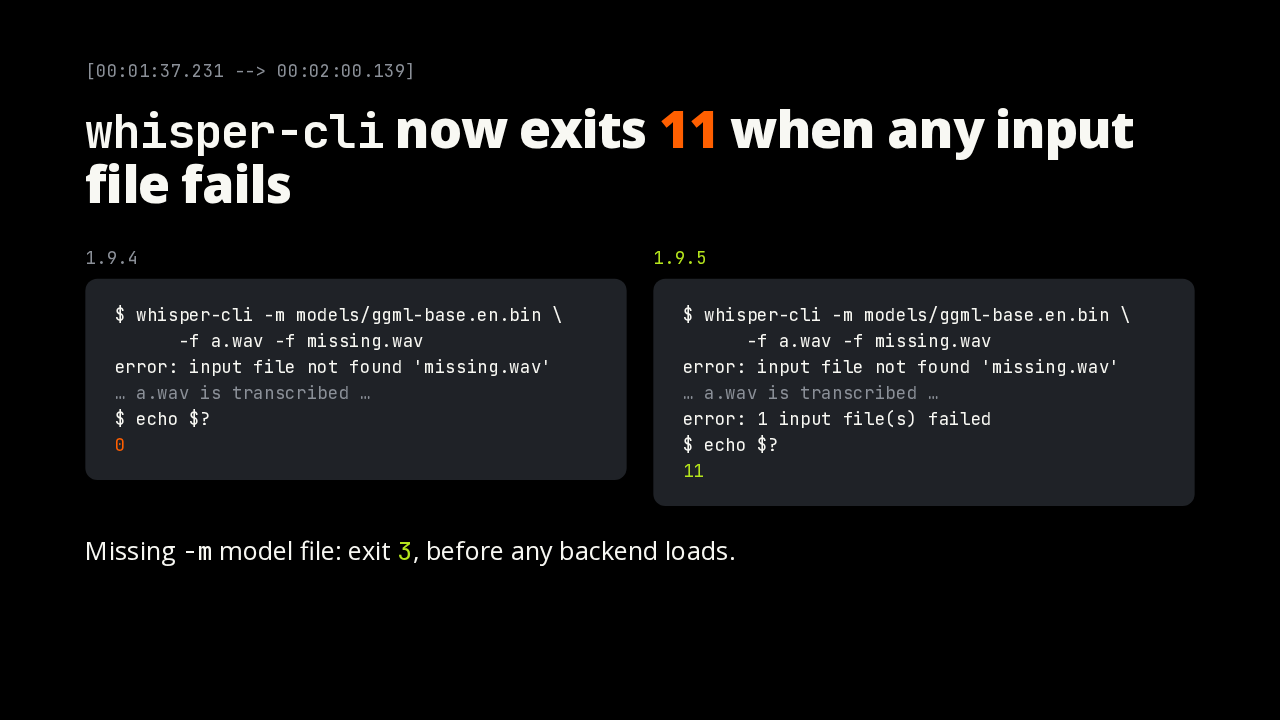
whisper-cli now exits 11 when any input file fails
1.9.4
1.9.5
Missing -m model file: exit 3, before any backend loads.
Now the changes that can break a script. whisper-cli used to skip a missing or unreadable input file and still exit zero. Now it finishes the other files, prints how many failed, and exits 11. A missing model file exits 3, before any backend loads. If a batch job counts a partial run as success, check for 11.
Breaking: the Vulkan Docker image
[00:02:00.139 --> 00:02:21.124]
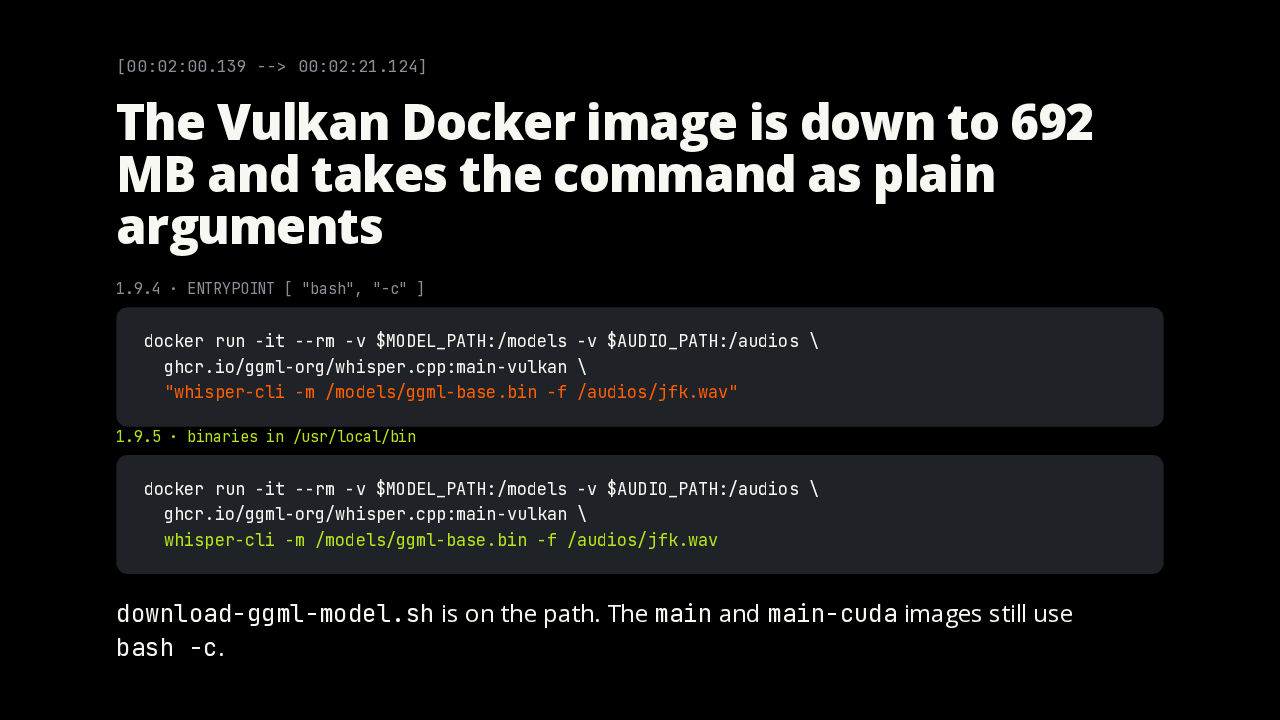
The Vulkan Docker image is down to 692 MB and takes the command as plain arguments
1.9.4 · ENTRYPOINT [ "bash", "-c" ]
1.9.5 · binaries in /usr/local/bin
download-ggml-model.sh is on the path. The main and main-cuda images still use bash -c.
The Vulkan image is now about 690 megabytes, roughly 40 percent of its old size, because it keeps only the tools and shared libraries. It also dropped the bash -c entry point, so the command goes in as plain arguments, without the quotes. The main and CUDA images still take the quoted form.
Breaking: renamed files and versions
[00:02:21.124 --> 00:02:40.186]
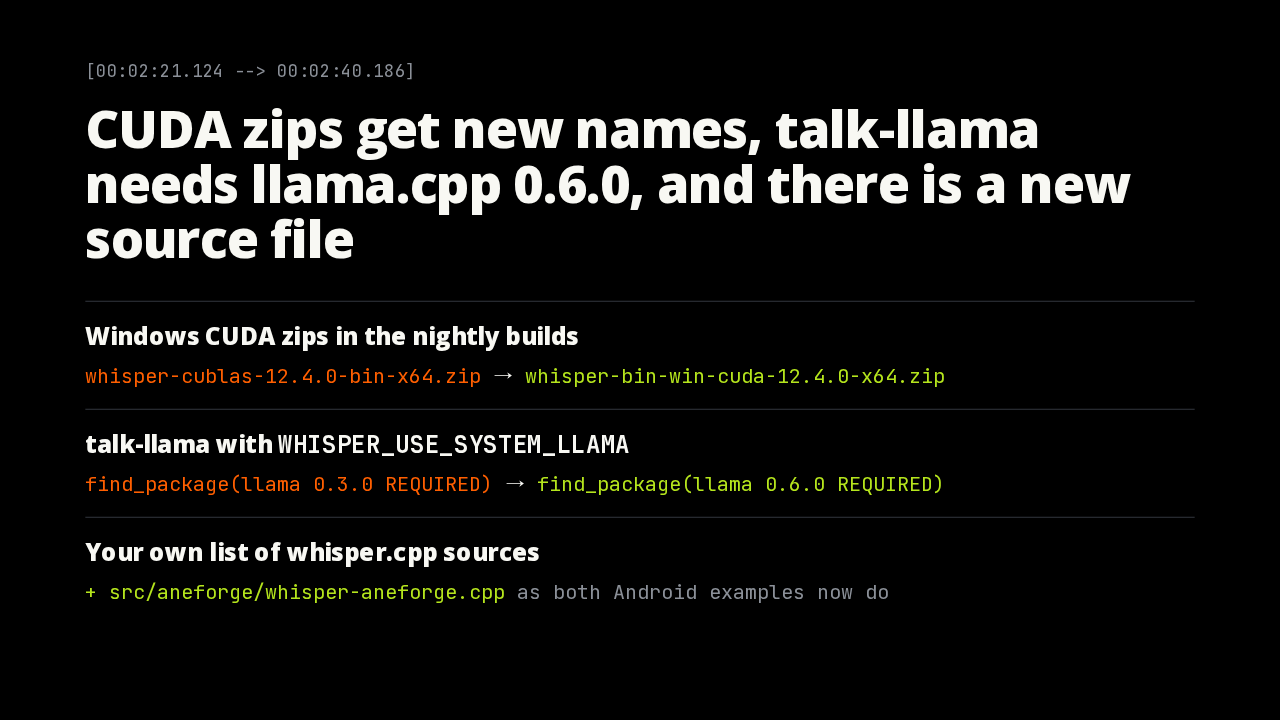
CUDA zips get new names, talk-llama needs llama.cpp 0.6.0, and there is a new source file
Windows CUDA zips in the nightly builds
whisper-cublas-12.4.0-bin-x64.zip → whisper-bin-win-cuda-12.4.0-x64.zip
talk-llama with WHISPER_USE_SYSTEM_LLAMA
find_package(llama 0.3.0 REQUIRED) → find_package(llama 0.6.0 REQUIRED)
Your own list of whisper.cpp sources
+ src/aneforge/whisper-aneforge.cpp as both Android examples now do
Some download scripts and custom builds need an edit. Windows CUDA zips in the nightly builds are now called whisper bin win CUDA, then the toolkit and the architecture. talk llama needs llama.cpp 0.6, including a system install. And a hand-written source list needs the new ANEForge file.
Upgrade
[00:02:40.186 --> 00:03:01.940]
Upgrade to whisper.cpp v1.9.5
Prebuilt binaries: nightly build b5454.
Wait if a script still expects exit 0 after a failed file, or quotes its command for the Vulkan image.
To upgrade, check out the v1.9.5 tag and rebuild, or take the binaries from nightly build b5454. Wait only if a script still expects exit zero after a failed file, or quotes its command for the Vulkan image. Everyone else gets ggml 0.26, the fixes, and on a Mac, an encoder on the Neural Engine.