whisper.cpp 1.9.5 can run the encoder on the Apple Neural Engine
2 days ago
whisper.cpp 1.9.5 is a maintenance release on ggml 0.26, with one new option for Macs. On Apple Silicon, the encoder can now run on the Neural Engine through ANEForge, skipping Core ML. It's about twice as fast as the Core ML encoder, from tiny to medium.
Ask about this presentation
Chapters
Show transcriptHide transcript
whisper.cpp 1.9.5 is a maintenance release on ggml 0.26, with one new option for Macs. On Apple Silicon, the encoder can now run on the Neural Engine through ANEForge, skipping Core ML. It's about twice as fast as the Core ML encoder, from tiny to medium.
Slide text
[00:00:00.000 --> 00:00:18.292]
whisper.cpp 1.9.5 can run the encoder on the Apple Neural Engine
2× faster than the Core ML encoder, from tiny to medium, through ANEForgev1.9.5 · ggml v0.26.0

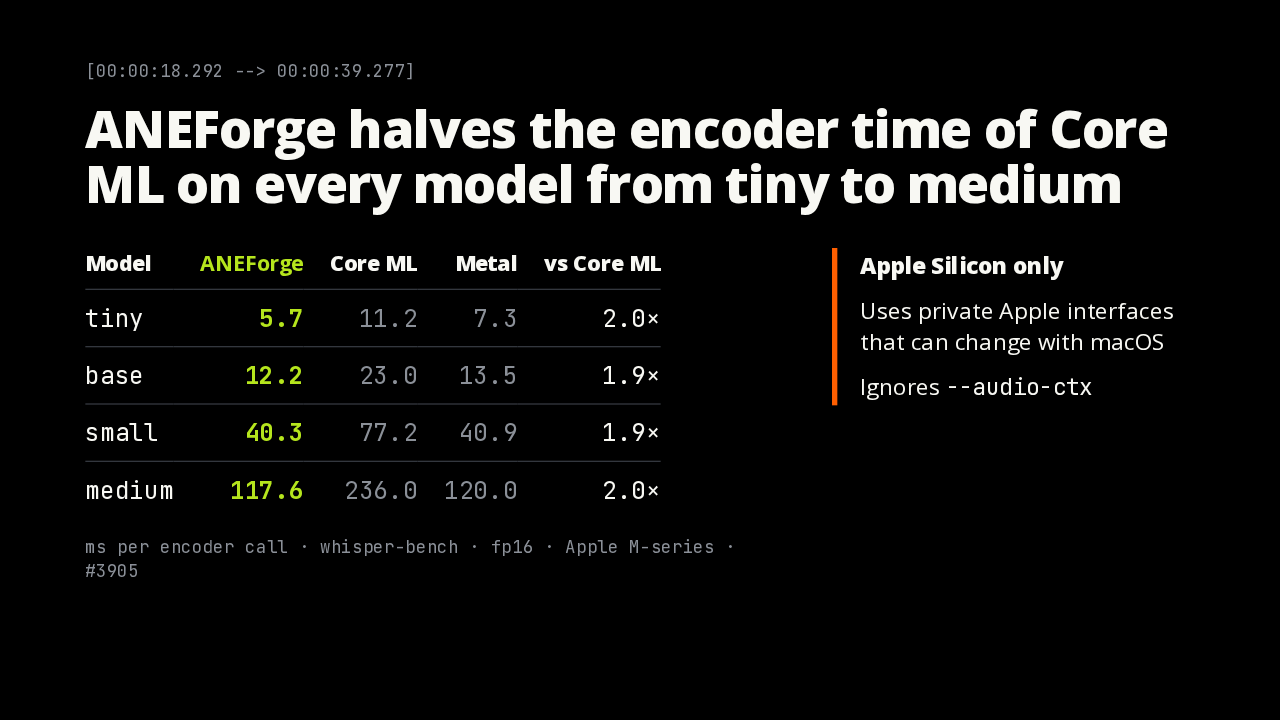
Here's the encoder time per call, in milliseconds. On every model from tiny to medium, ANEForge takes about half the time of Core ML, and roughly matches the Metal GPU encoder. It's Apple Silicon only, it relies on private Apple interfaces that can change with macOS, and it ignores the audio context option.
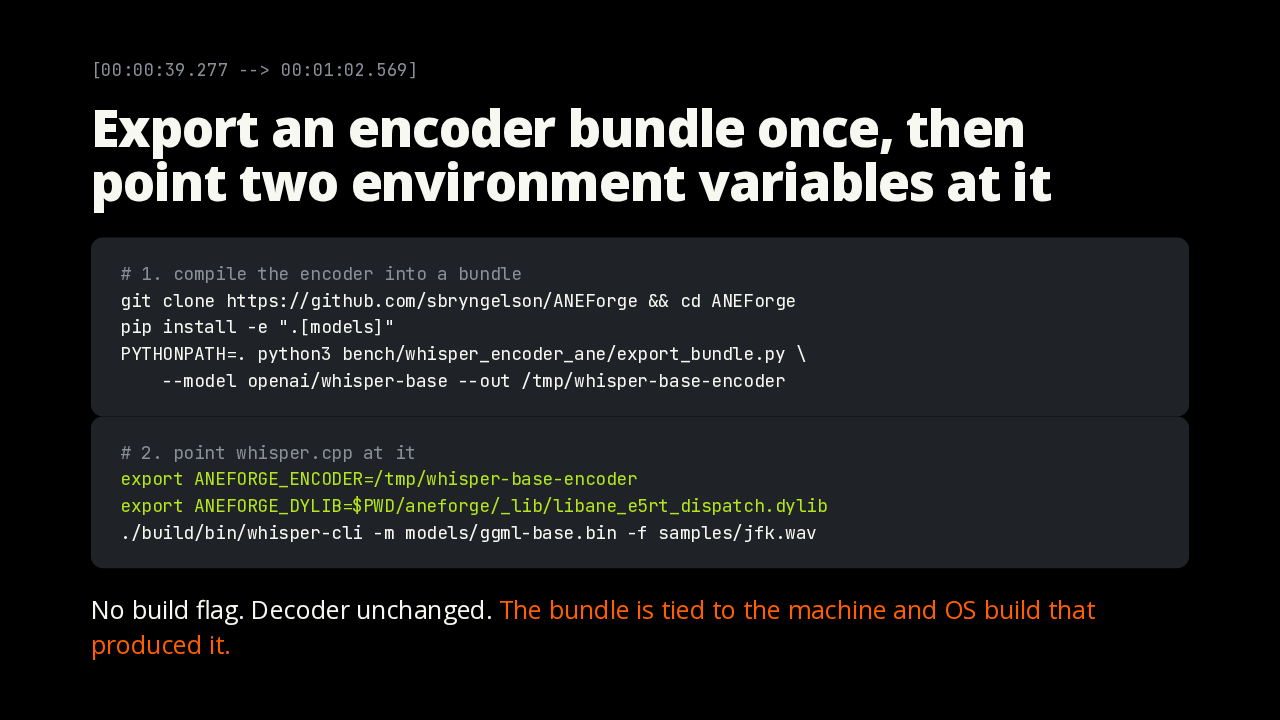
First you compile the encoder into a bundle with the Python tools in the ANEForge repository. Then you set two environment variables, for the bundle and the dispatch library, and run whisper-cli as usual. There's no build flag. The bundle only works on the machine and OS build that made it, so a macOS update means a new export.
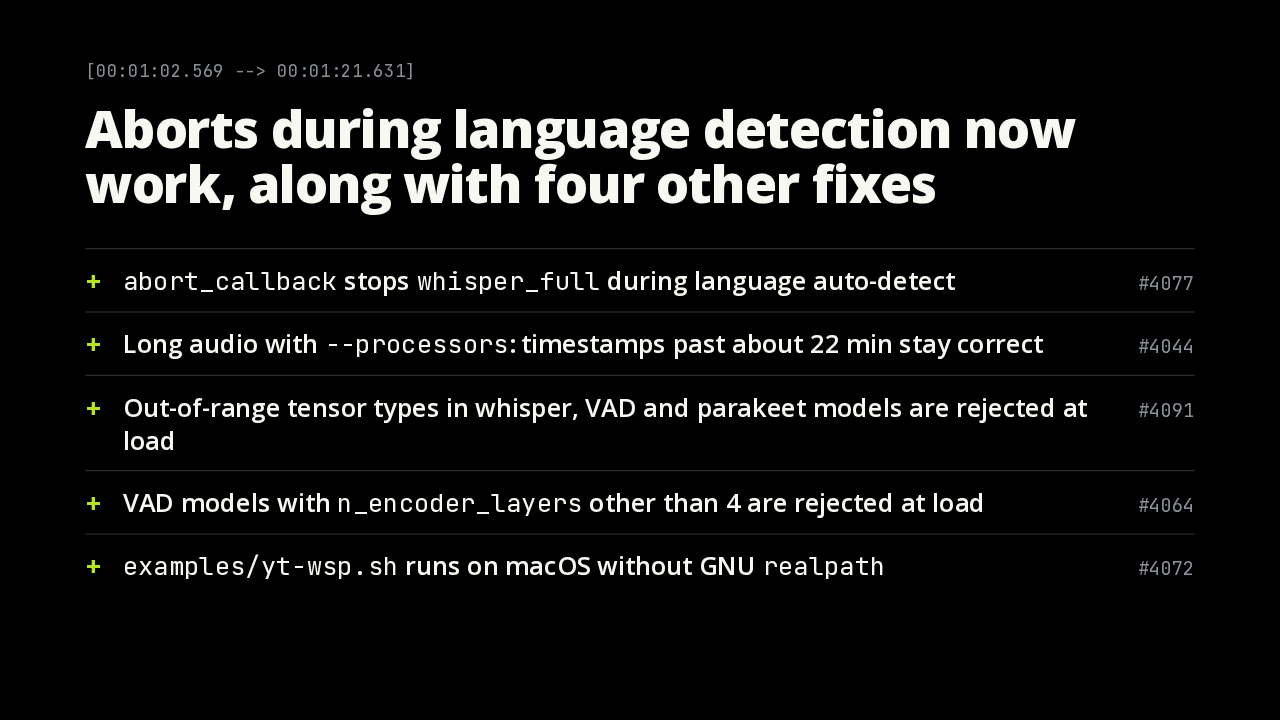
The abort callback now also covers language detection. Long files run with several processors no longer get corrupted timestamps past about 22 minutes, mostly a Windows problem. Malformed model and VAD files are rejected at load instead of crashing. And the yt-dlp transcription script now runs on macOS.
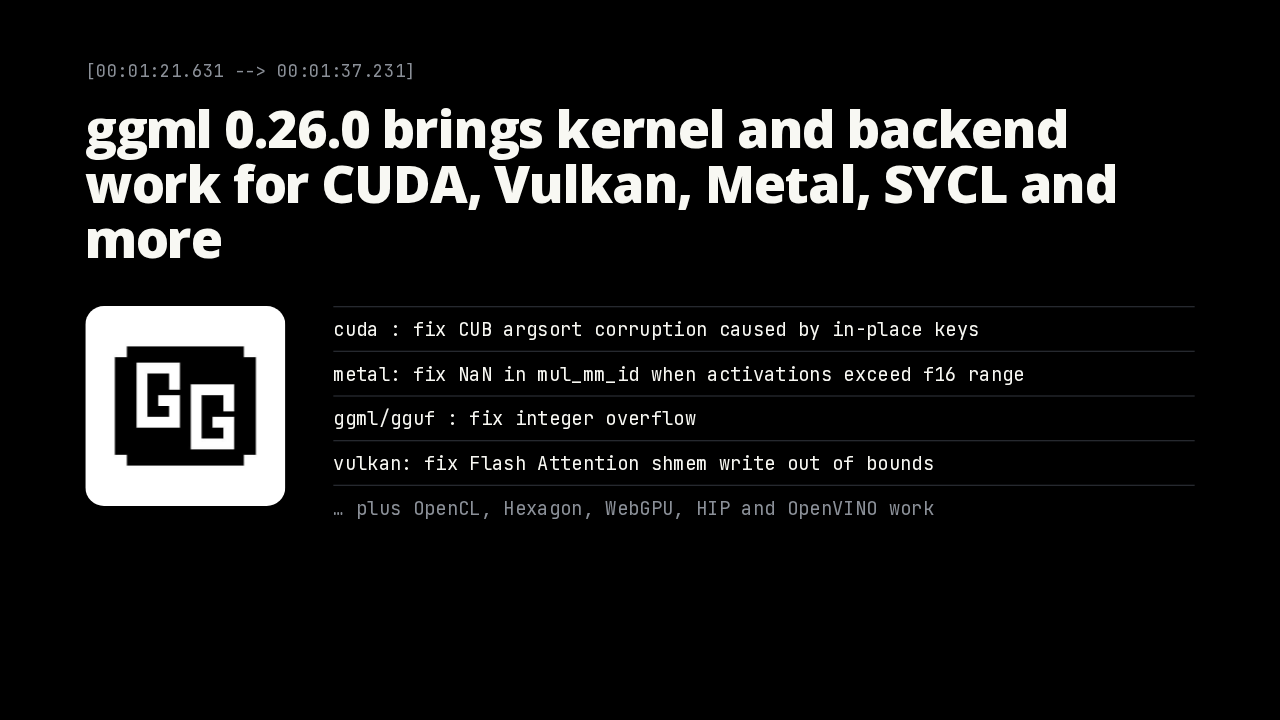
Most of the commits come from the ggml sync to 0.26. That's kernel and backend work across the GPU and accelerator backends, including fixes for an argsort corruption on CUDA and NaNs on Metal. You get it by rebuilding.
Slide text
[00:01:21.631 --> 00:01:37.231]
ggml 0.26.0 brings kernel and backend work for CUDA, Vulkan, Metal, SYCL and more

cuda : fix CUB argsort corruption caused by in-place keys
metal: fix NaN in mul_mm_id when activations exceed f16 range
ggml/gguf : fix integer overflow
vulkan: fix Flash Attention shmem write out of bounds
… plus OpenCL, Hexagon, WebGPU, HIP and OpenVINO work
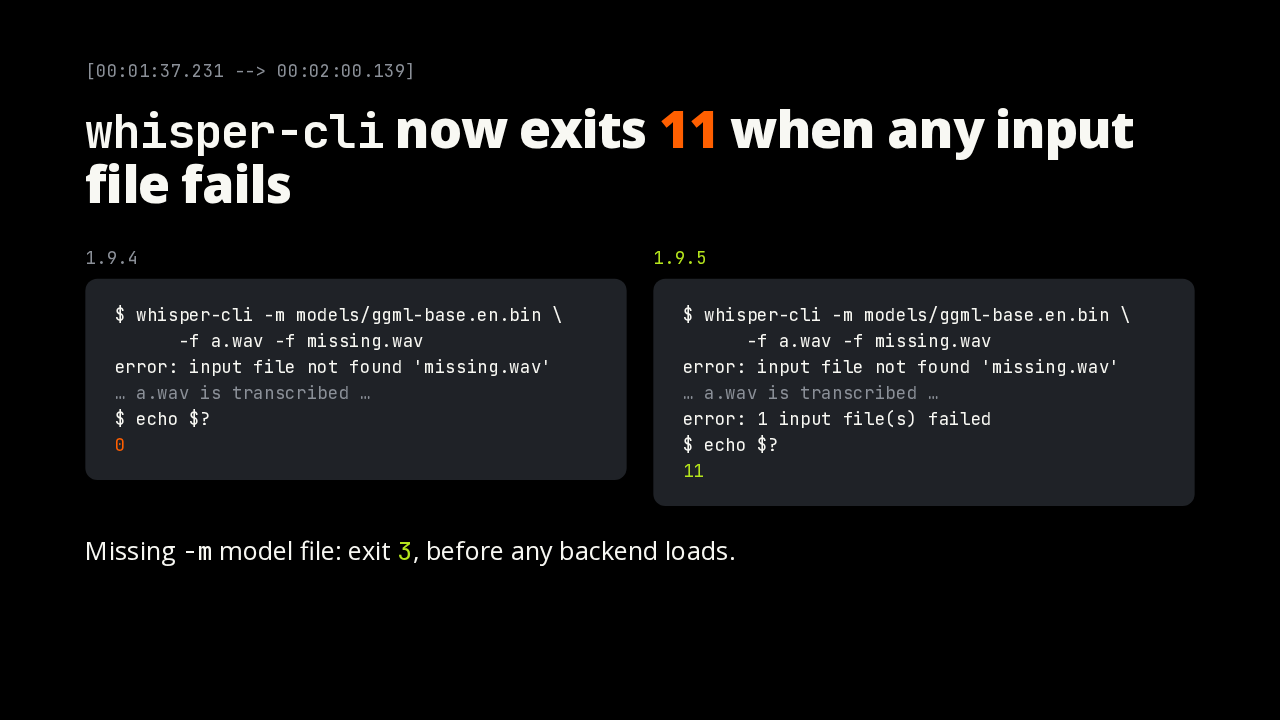
Now the changes that can break a script. whisper-cli used to skip a missing or unreadable input file and still exit zero. Now it finishes the other files, prints how many failed, and exits 11. A missing model file exits 3, before any backend loads. If a batch job counts a partial run as success, check for 11.
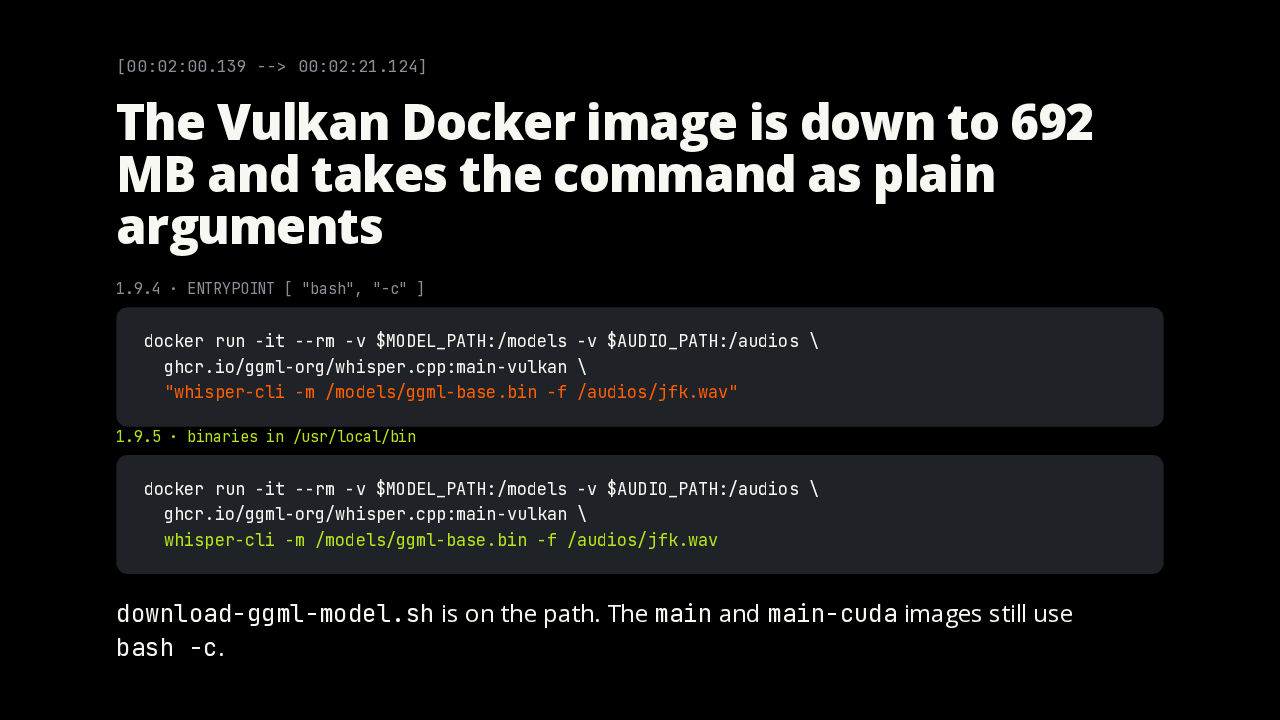
The Vulkan image is now about 690 megabytes, roughly 40 percent of its old size, because it keeps only the tools and shared libraries. It also dropped the bash -c entry point, so the command goes in as plain arguments, without the quotes. The main and CUDA images still take the quoted form.
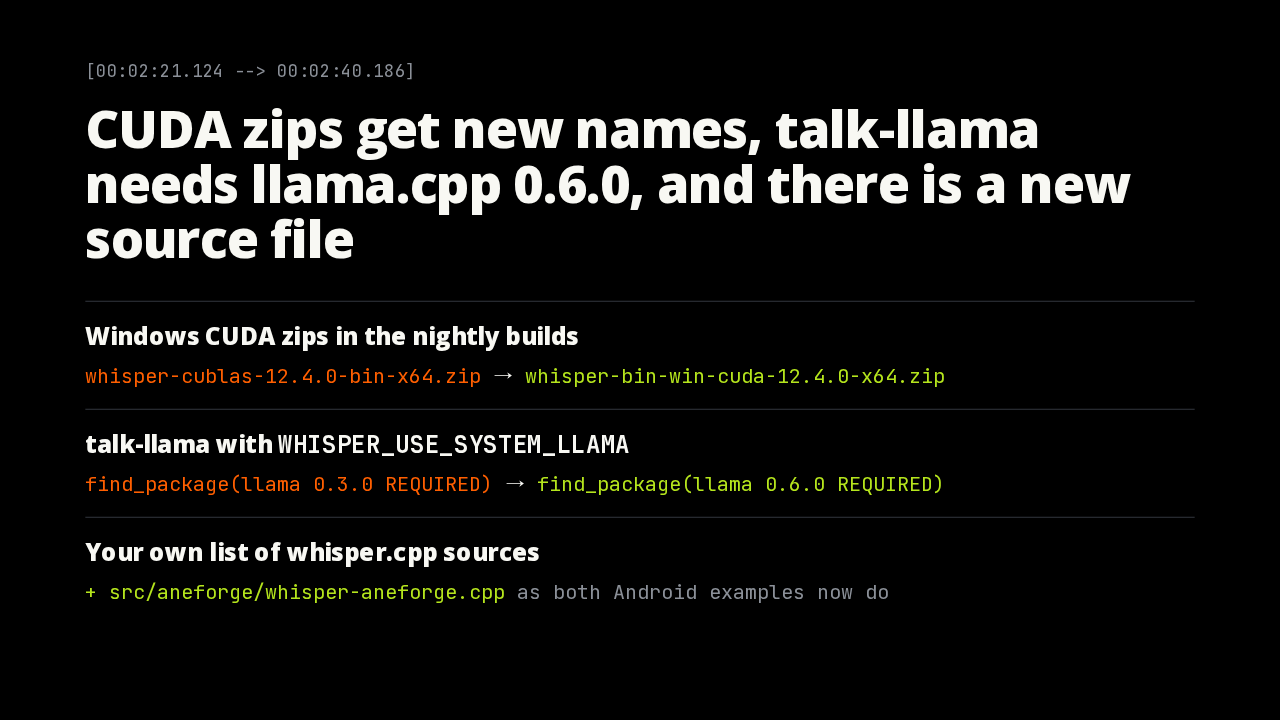
Some download scripts and custom builds need an edit. Windows CUDA zips in the nightly builds are now called whisper bin win CUDA, then the toolkit and the architecture. talk llama needs llama.cpp 0.6, including a system install. And a hand-written source list needs the new ANEForge file.
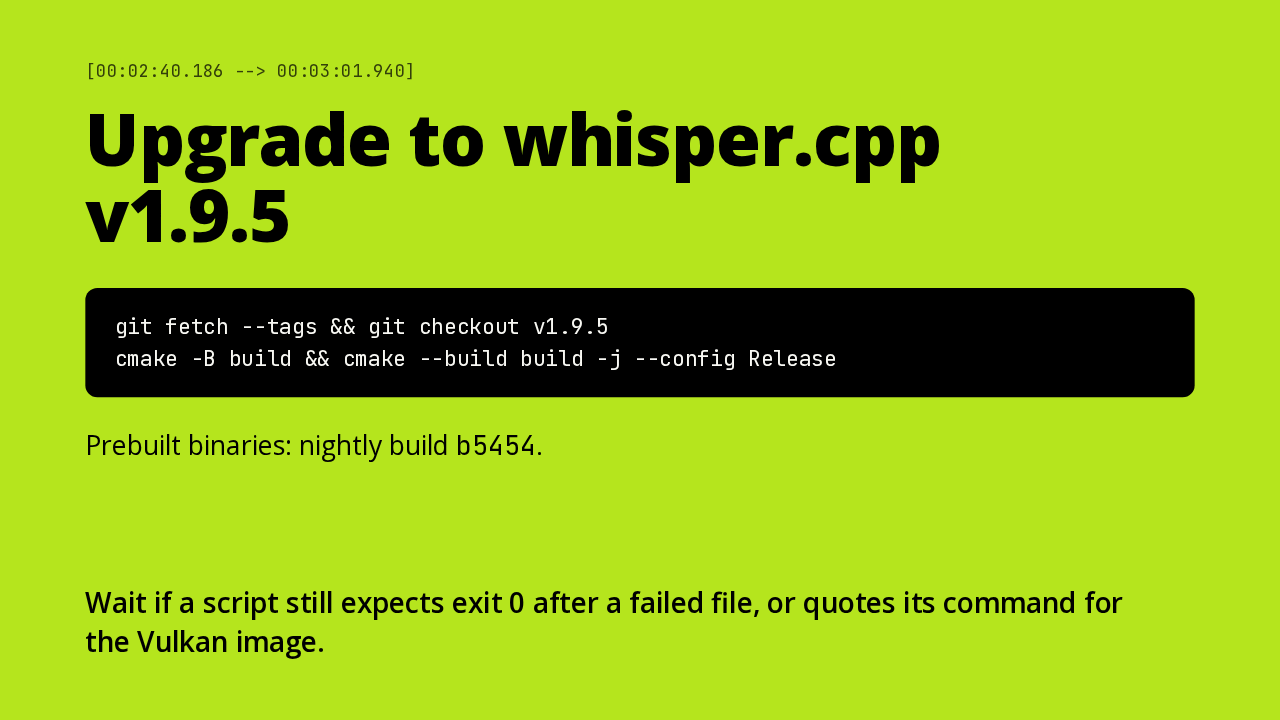
To upgrade, check out the v1.9.5 tag and rebuild, or take the binaries from nightly build b5454. Wait only if a script still expects exit zero after a failed file, or quotes its command for the Vulkan image. Everyone else gets ggml 0.26, the fixes, and on a Mac, an encoder on the Neural Engine.