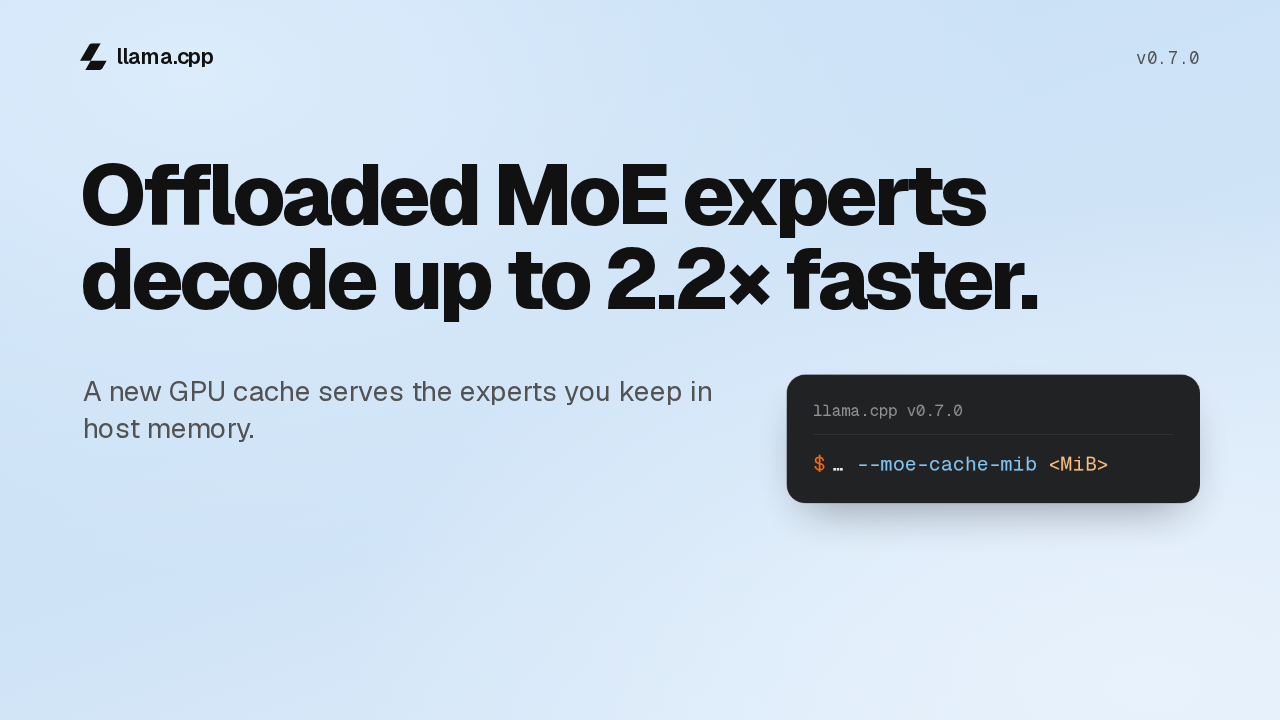
Offloaded MoE experts decode up to 2.2× faster.
2 days ago
The top highlight of llama.cpp v0.7.0 is a cache for mixture of experts models. If you offload a model's experts to host memory, decode gets up to 2.2 times faster. The cache is set with one flag, --moe-cache-mib. And one change to check before you upgrade: the server's default port is now 9931.
Ask about this presentation
Chapters
Show transcriptHide transcript
The top highlight of llama.cpp v0.7.0 is a cache for mixture of experts models. If you offload a model's experts to host memory, decode gets up to 2.2 times faster. The cache is set with one flag, --moe-cache-mib. And one change to check before you upgrade: the server's default port is now 9931.
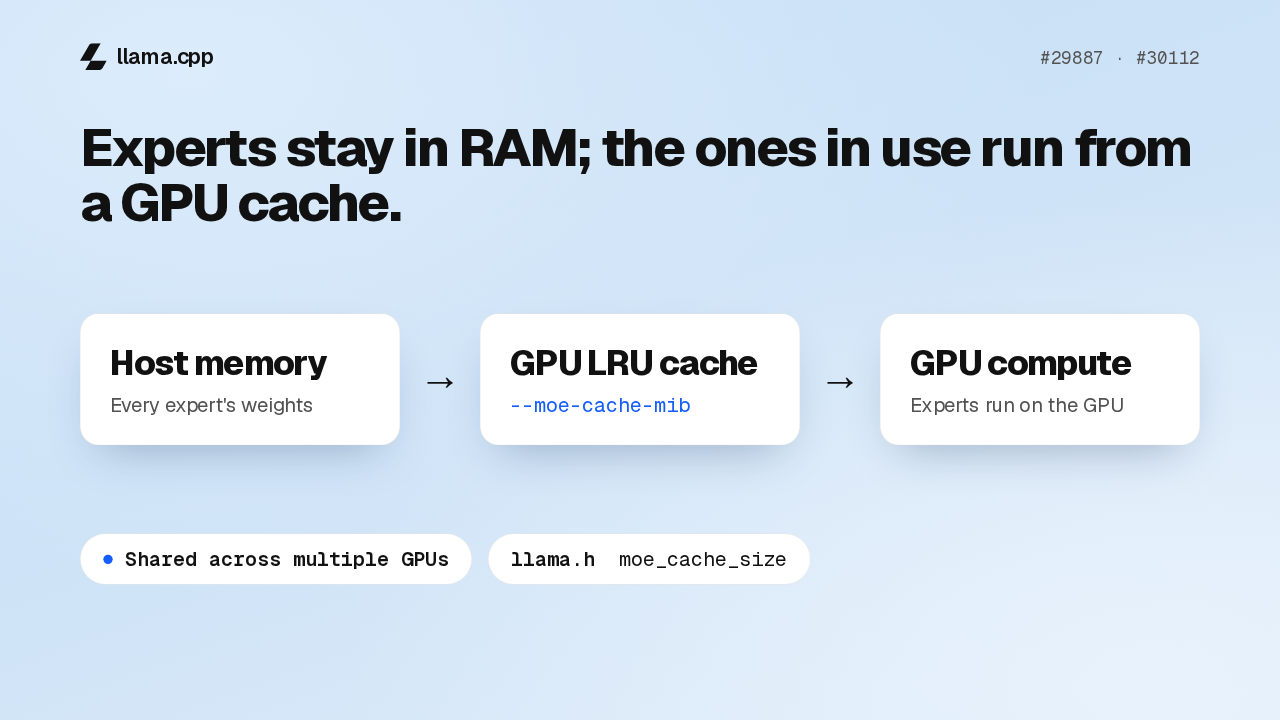
The experts stay in host memory. Now a least recently used cache on the GPU holds the experts in use, and they run there. You size the cache in mebibytes with the flag. The cache is shared across multiple GPUs, and library users get the same setting as moe_cache_size in llama.h.
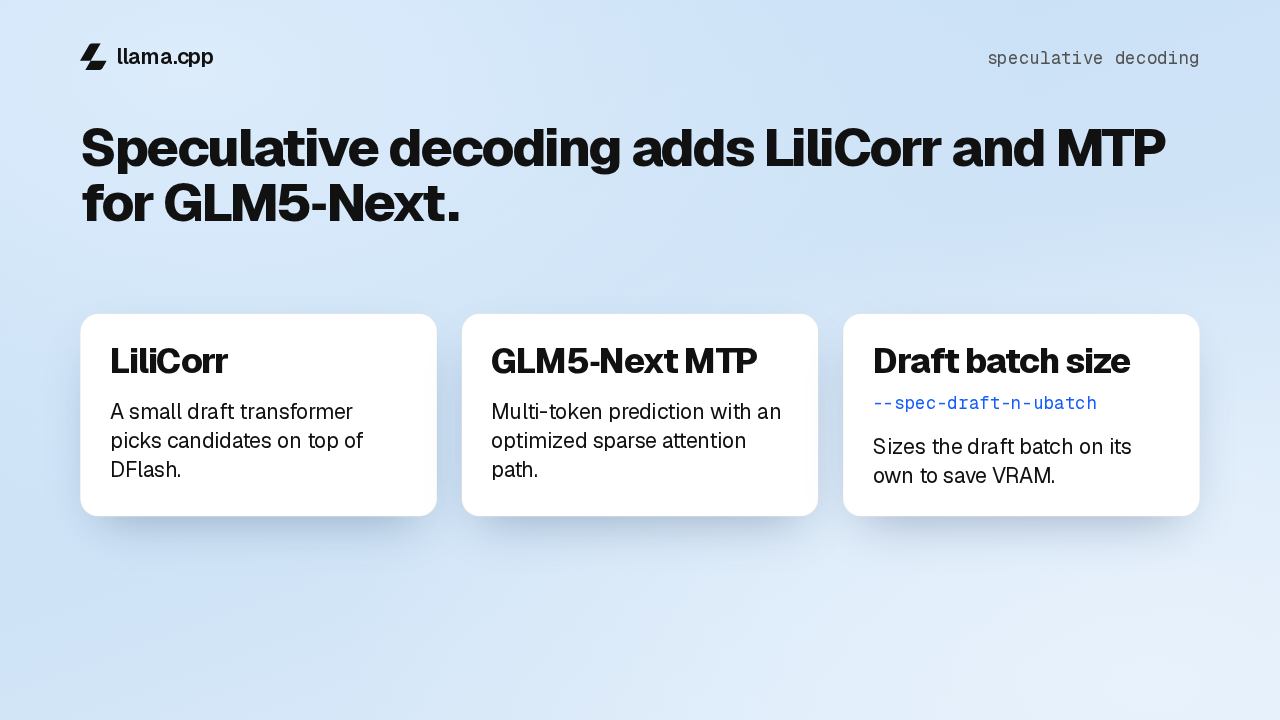
Speculative decoding gets two new paths. LiliCorr uses a small draft transformer to pick candidates, built on top of DFlash. GLM5-Next gets multi-token prediction, with an optimized sparse attention path. And a new flag, --spec-draft-n-ubatch, sizes the draft model's batch separately, so the draft takes less VRAM.
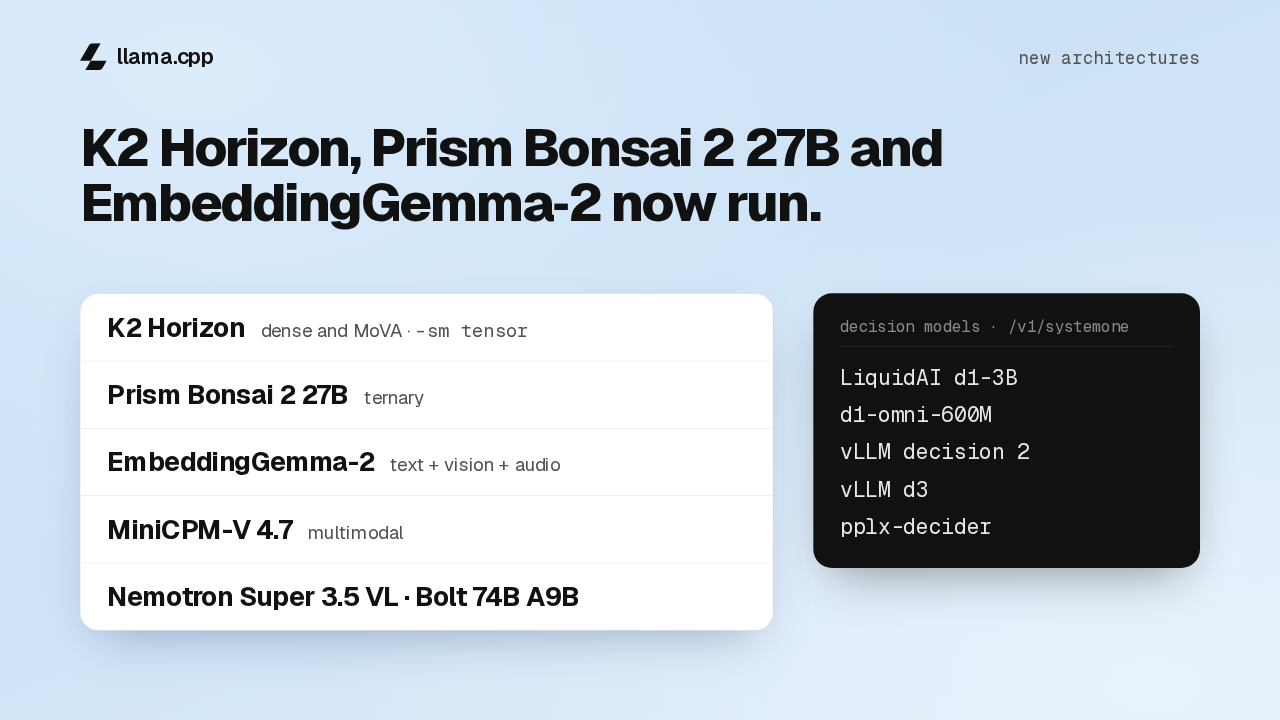
K2 Horizon arrives in dense and MoVA variants, with tensor splitting. Prism Bonsai 2 27B is a ternary model, and EmbeddingGemma-2 embeds text, images and audio. MiniCPM-V 4.7, Nemotron Super 3.5 VL and Nemotron Bolt join them. And five decision models are served on the /v1/systemone endpoint: two from LiquidAI, vLLM decision 2 and d3, and pplx-decider.
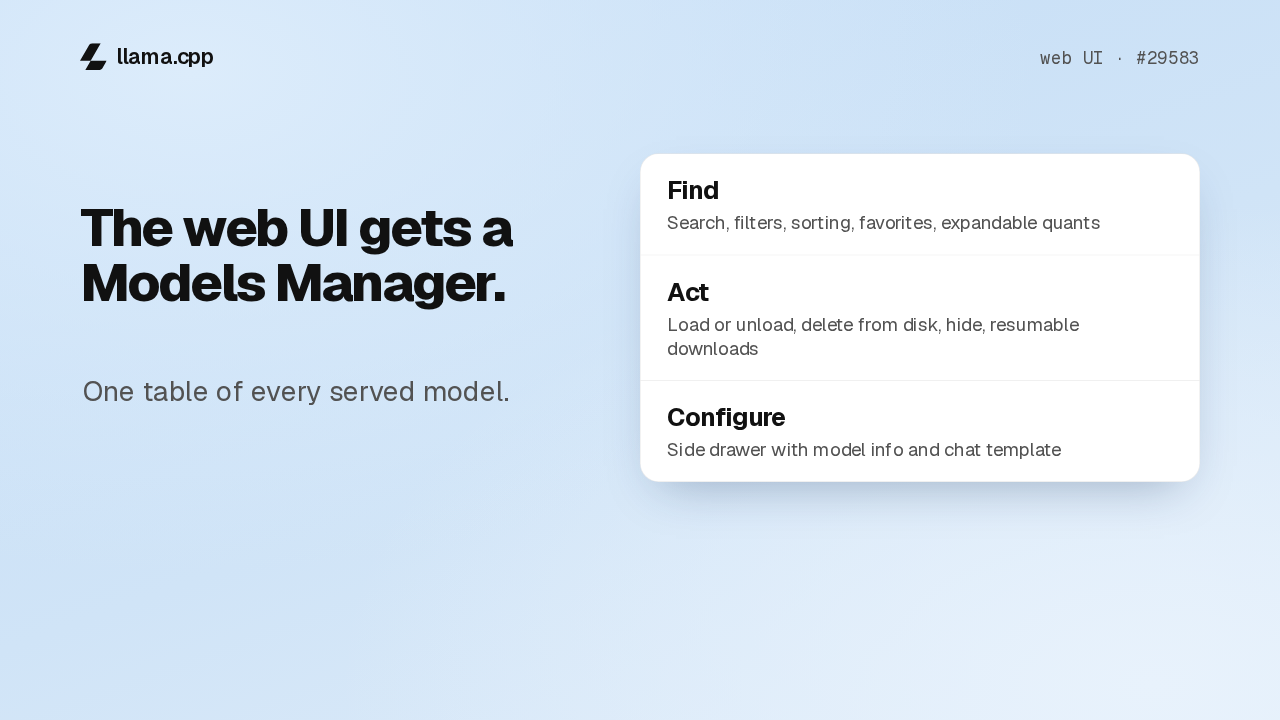
If you use the built-in web UI, there's a new Models Manager. It's one table of every served model, with search, filters, sorting and favorites. From a row you can load a model, delete it, or resume a download. A side drawer shows its info and chat template.
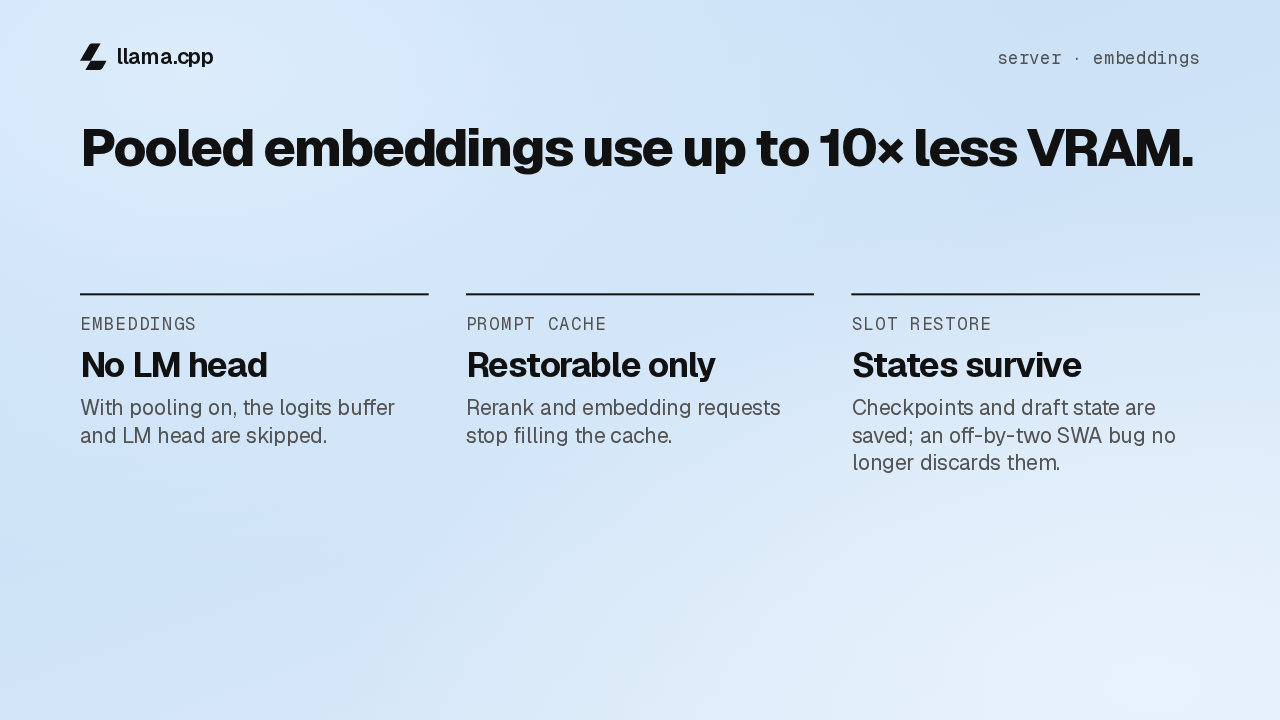
If you serve embeddings, with pooling on the logits buffer and the LM head are skipped, for up to ten times less VRAM. The prompt cache now saves only states it can restore, so rerank and embedding requests stop filling it. And slot save and restore keeps context checkpoints and the draft state, while an off-by-two fix stops restored states being thrown away.
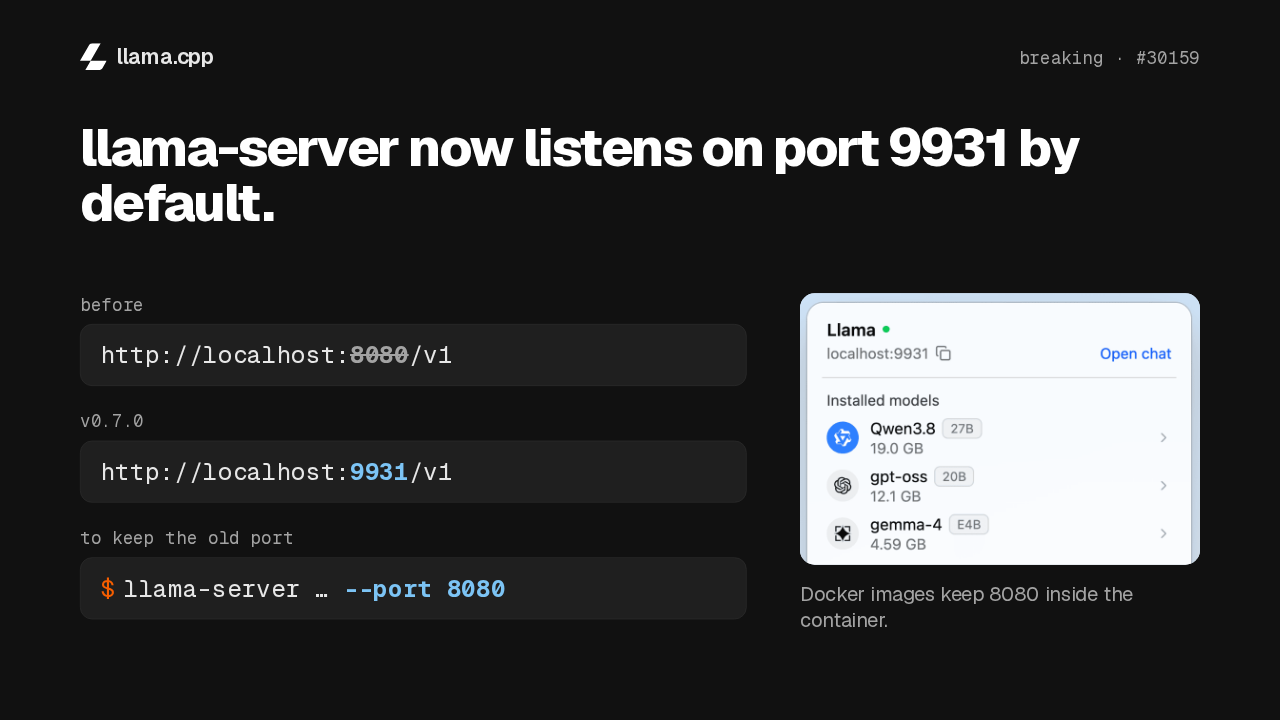
The server now listens on port 9931 instead of 8080, so any client pointed at localhost 8080 stops connecting after you upgrade. The fix is one flag: pass --port 8080, or point your clients at 9931. Docker images keep 8080 inside the container.
Slide text
llama.cppbreaking · #30159llama-server now listens on port 9931 by default.
beforehttp://localhost:8080/v1v0.7.0http://localhost:9931/v1to keep the old port$llama-server … --port 8080
Docker images keep 8080 inside the container.
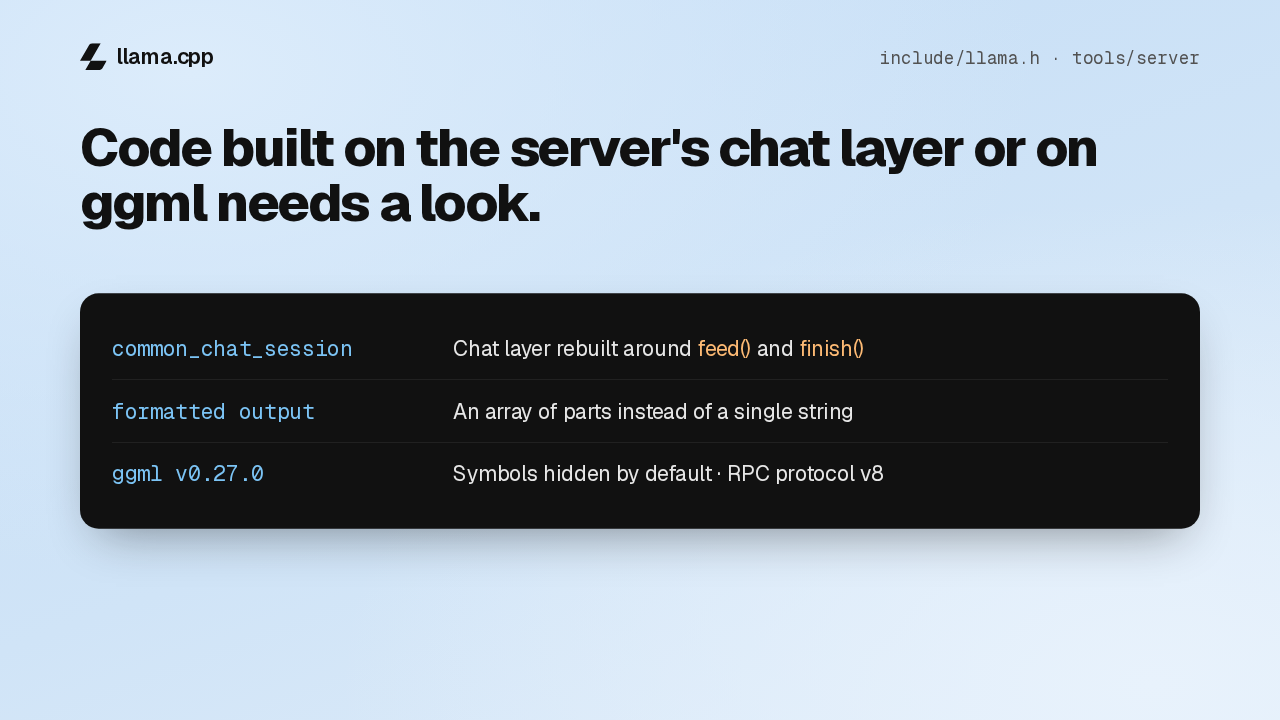
This one is for code built on llama.cpp. If you build on the server's chat code, it is now organised around common_chat_session, with feed and finish. Formatted chat output is an array of parts instead of one string. And ggml 0.27 hides symbols by default and moves RPC to protocol version 8.
If your own code builds on the server's chat layer, port it to common_chat_session when you upgrade. Offloaded experts decode up to 2.2 times faster, and the one thing to check first is the port. The release is tagged v0.7.0, matching nightly build b11669.