SAELens 6.54 folds decoder norms as the SAE loads
18 minutes ago
SAELens 6.54 adds one argument to its loaders. Pass fold_W_dec_norm equals True, and the SAE comes back with every decoder row scaled to unit length. If you compare activations between features, or try to reproduce values from another tool, this is likely the setting you want.
Ask about this presentation
Chapters
Show transcriptHide transcript
SAELens 6.54 adds one argument to its loaders. Pass fold_W_dec_norm equals True, and the SAE comes back with every decoder row scaled to unit length. If you compare activations between features, or try to reproduce values from another tool, this is likely the setting you want.
Slide text

SAELens 6.54 folds decoder norms as the SAE loads
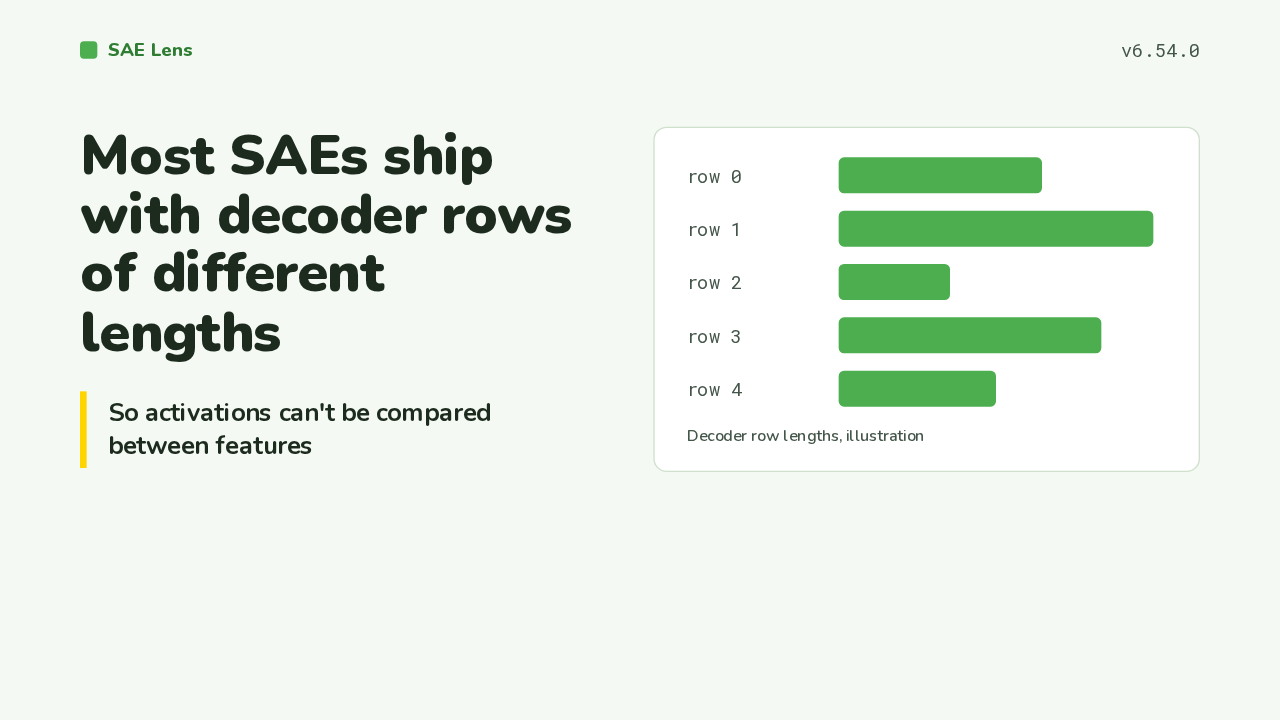
fold_W_dec_norm=TrueMost SAEs aren't trained with a unit-norm decoder. When decoder rows have different lengths, a feature's activation size and the length of its decoder direction are tangled together. So activations can't be compared between features, and analyses that assume a unit-norm decoder won't reproduce. It's also a common reason values fail to match Neuronpedia dashboards, which are computed after folding.
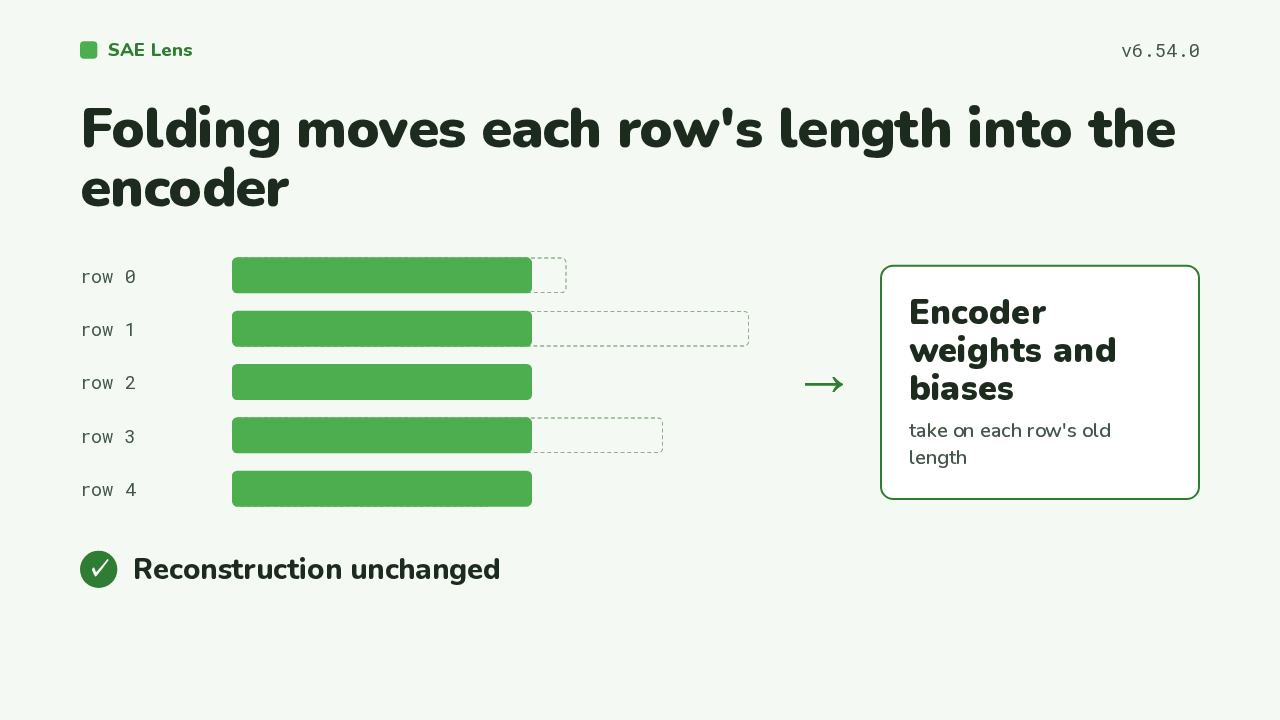
Folding rescales every decoder row to unit length and moves that length into the encoder weights and biases. It's a reparameterization, so the reconstruction stays the same. What changes is the feature activations. They're rescaled onto a footing you can compare from one feature to the next.
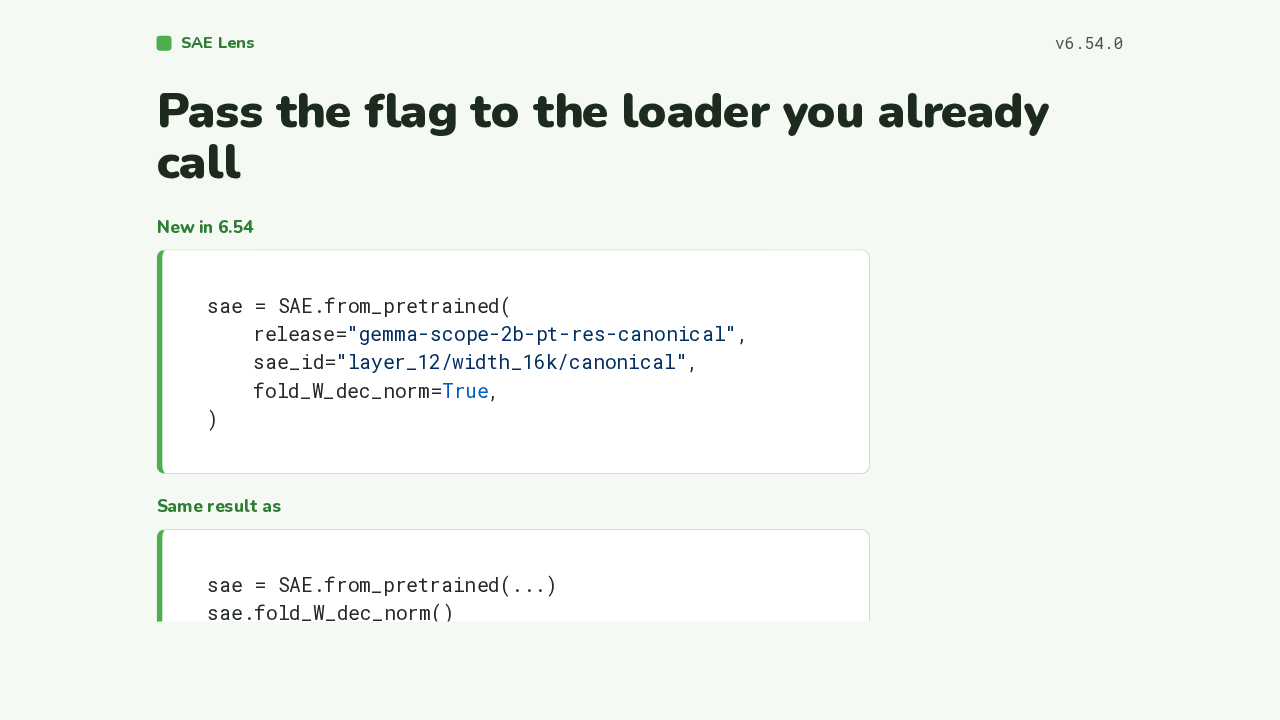
Here's the example from the usage docs, loading a Gemma Scope SAE. The new keyword goes straight into from_pretrained. It gives the same result as loading first and then calling the fold method yourself, which you could already do before this release.
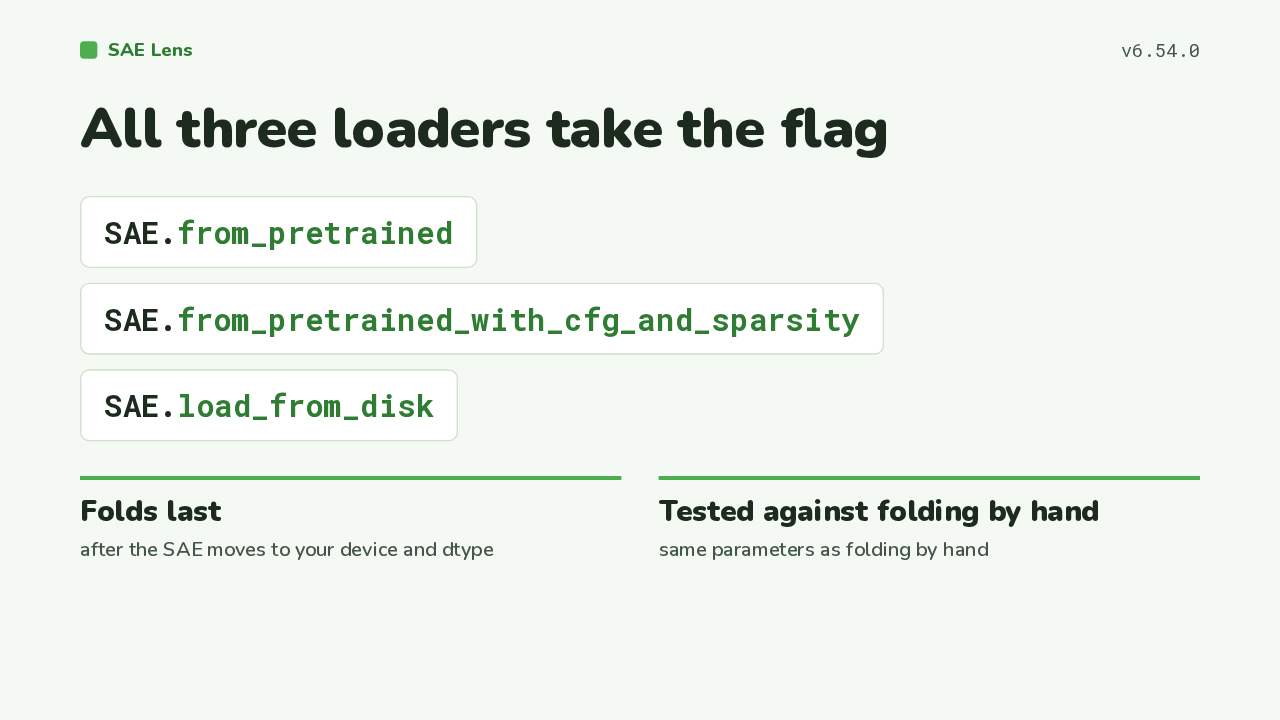
The flag works on all three loading paths: from_pretrained, the variant that also returns the config and sparsity, and load_from_disk for SAEs you saved yourself. The fold runs last, after the SAE is on your chosen device and data type. New tests check that folding on load gives the same parameters as loading and then folding, for every foldable architecture loaded from disk, and for a standard SAE through from_pretrained.
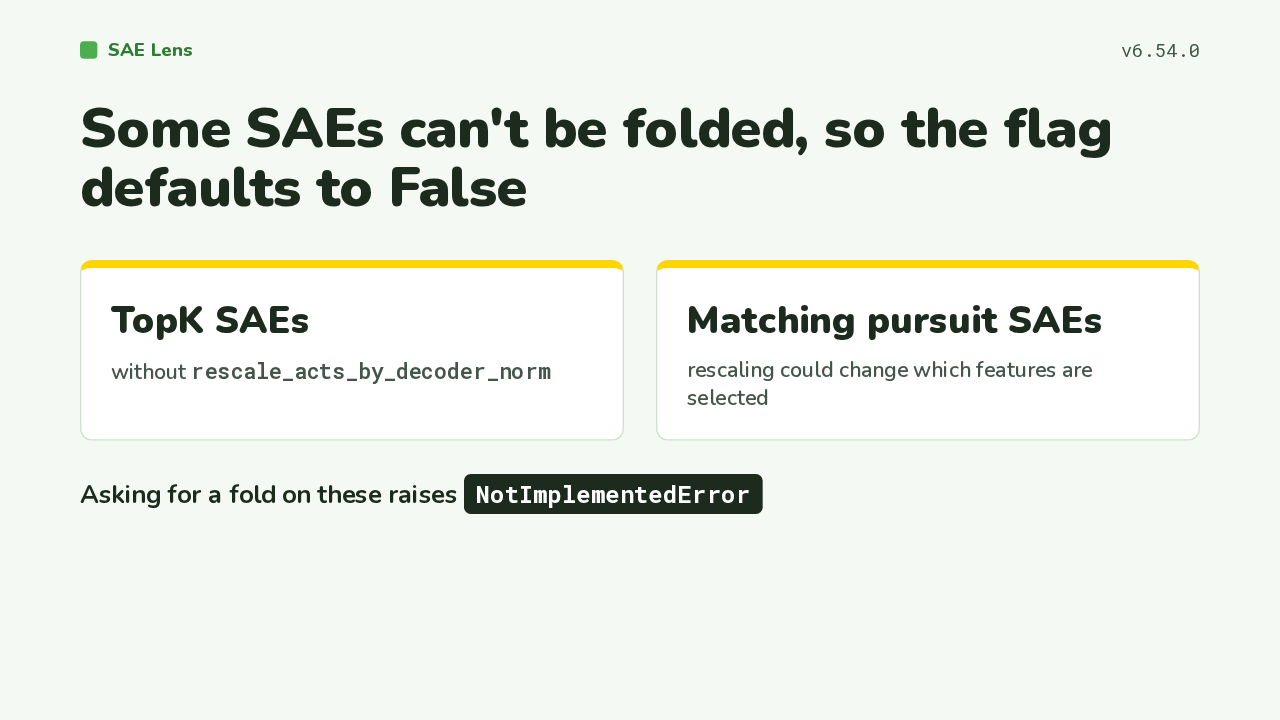
Folding isn't supported for every architecture, which is why the flag defaults to False. That includes TopK SAEs without the setting that rescales activations by decoder norm, and matching pursuit SAEs. In both, rescaling activations could change which features get selected. Ask for a fold on one of these and you get a NotImplementedError.
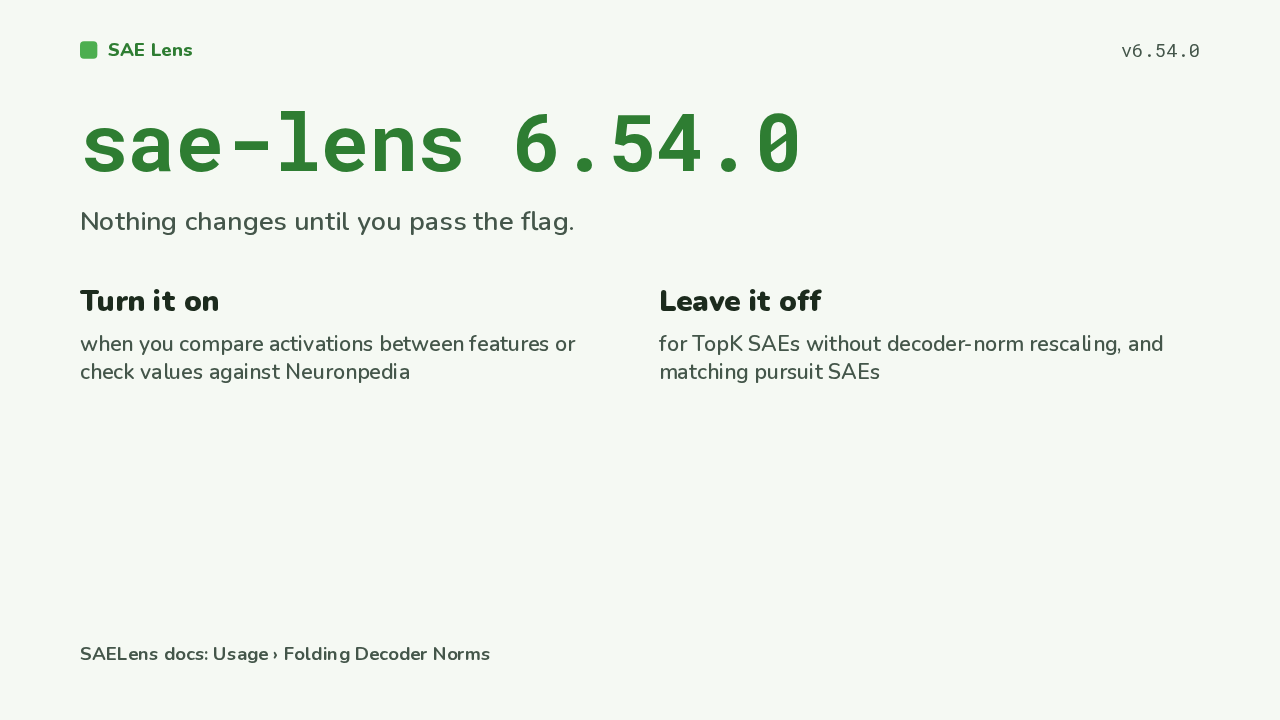
Upgrading to SAELens 6.54 changes nothing in your existing code, because the flag defaults to False. If you compare activations between features, or check your numbers against Neuronpedia, pass the flag and your SAE loads with its decoder norms folded. Leave it off for TopK SAEs without decoder-norm rescaling, and for matching pursuit SAEs. The full write-up is in the usage docs, under Folding Decoder Norms.