handy now cuts long recordings at pauses and transcribes them in chunks
2 days ago
Handy now transcribes long recordings in pieces. When a model doesn't handle long audio on its own, and you talk past forty seconds, Handy cuts the audio at your pauses into chunks of about thirty seconds, and decodes each one on its own. CJ calls it a long awaited feature.
Ask about this presentation
Chapters
Show transcriptHide transcript
Handy now transcribes long recordings in pieces. When a model doesn't handle long audio on its own, and you talk past forty seconds, Handy cuts the audio at your pauses into chunks of about thirty seconds, and decodes each one on its own. CJ calls it a long awaited feature.
Slide text
 pull request
handy now cuts long recordings at pauses and transcribes them in chunks
“long awaited feature for chunking long form audio” cjpais
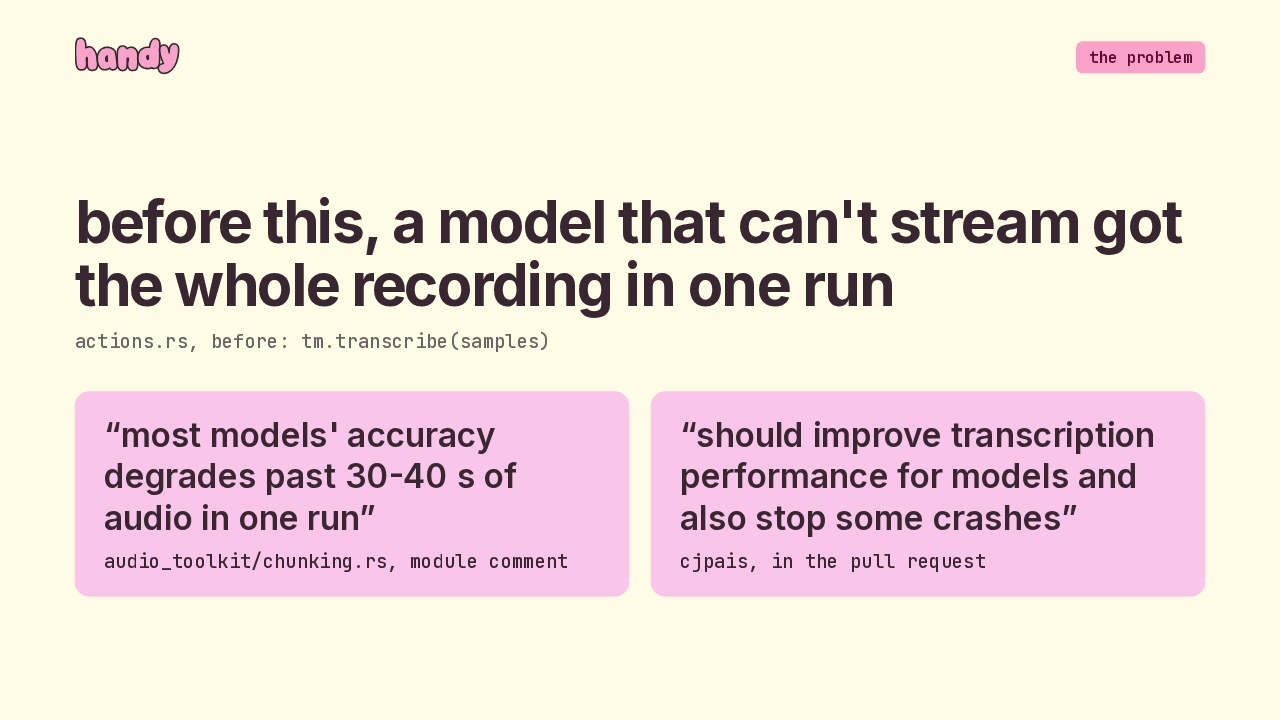
Before this, a model that can't stream got the whole recording in one run, however long it was. The new chunking module says why that hurts: most models lose accuracy past thirty to forty seconds of audio in one run. CJ puts it simply: better transcription for those models, and an end to some crashes.
Slide text
the problembefore this, a model that can't stream got the whole recording in one run
actions.rs, before: tm.transcribe(samples)
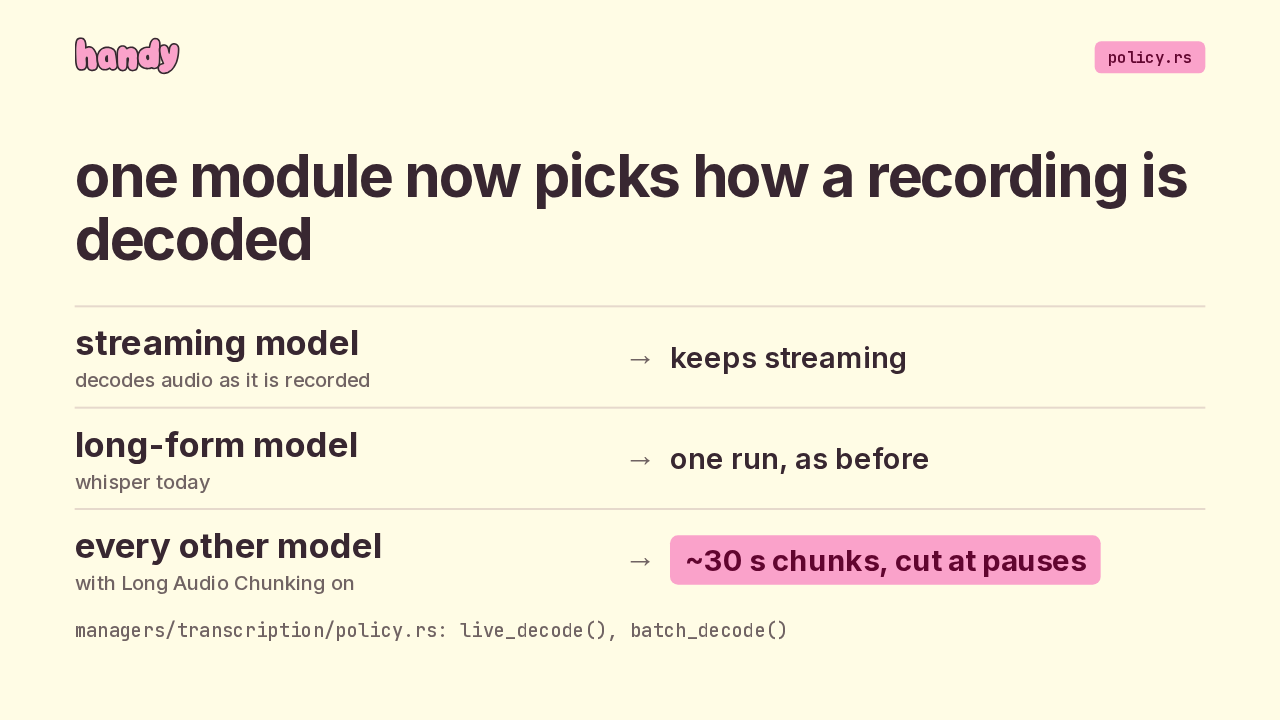
“most models' accuracy degrades past 30-40 s of audio in one run”audio_toolkit/chunking.rs, module comment“should improve transcription performance for models and also stop some crashes”cjpais, in the pull requestOne new module now picks the path. A streaming model keeps streaming, since it handles long audio itself. A model that stays accurate on long audio, which today means Whisper, still gets a single run. Every other model, with the new setting on, is cut at pauses.
Slide text
policy.rsone module now picks how a recording is decoded
streaming modeldecodes audio as it is recorded→keeps streaminglong-form modelwhisper today→one run, as beforeevery other modelwith Long Audio Chunking on→~30 s chunks, cut at pausesmanagers/transcription/policy.rs: live_decode(), batch_decode()
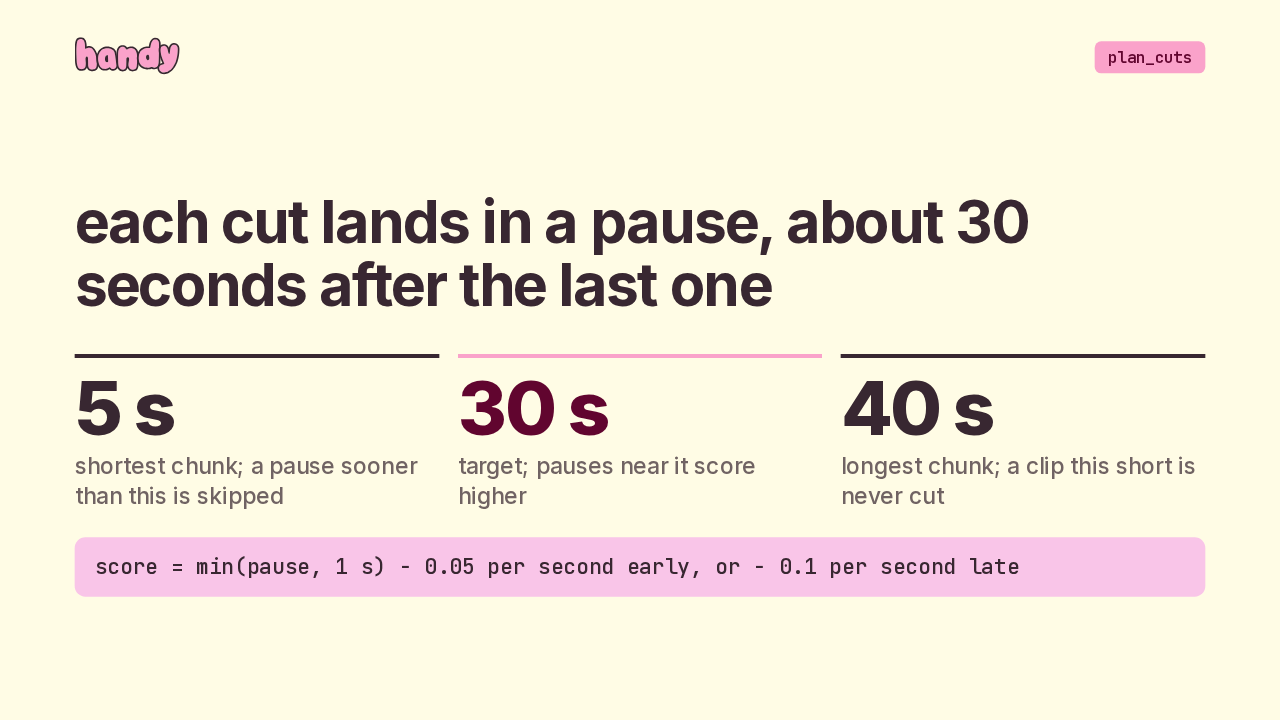
The cut plan is greedy, left to right. Audio of forty seconds or less is never cut. Past that, each cut goes in the middle of a pause, five to forty seconds after the last one. Longer pauses score higher, up to one second, and every second off the thirty second target costs a little, twice as much when it's late. With no pause at all, it's a hard cut at forty.
Slide text
plan_cutseach cut lands in a pause, about 30 seconds after the last one
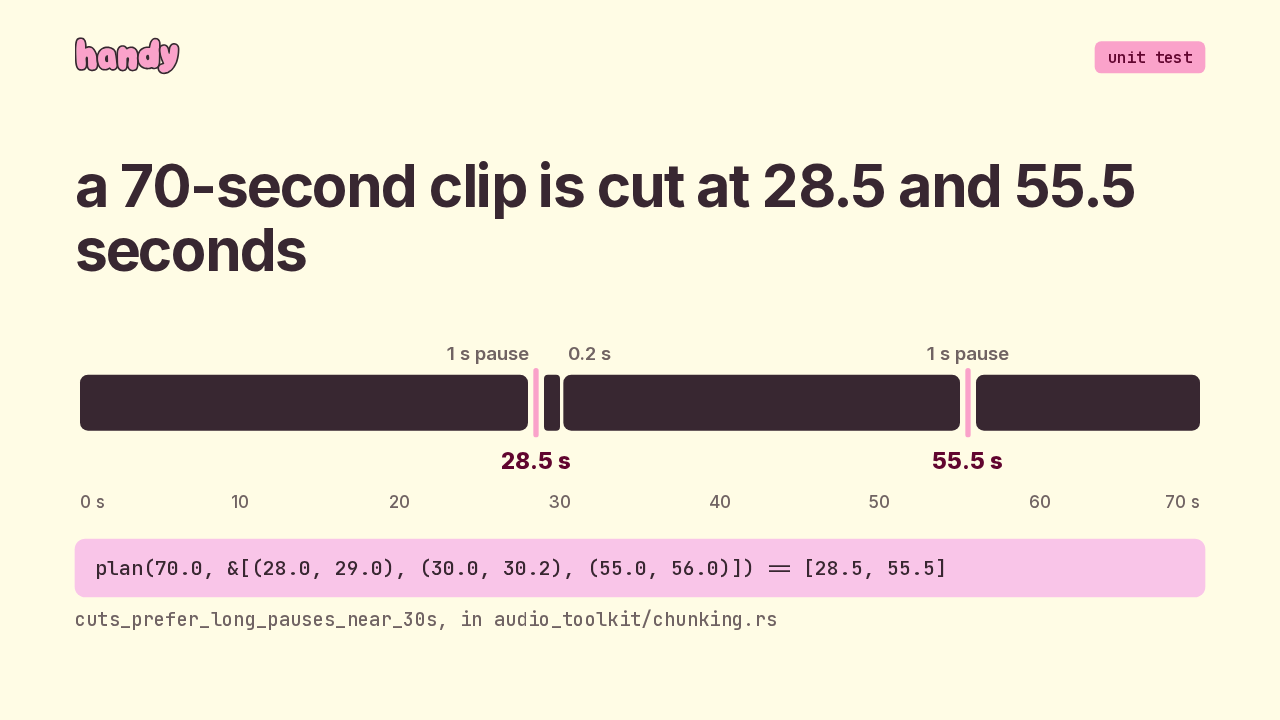
5 sshortest chunk; a pause sooner than this is skipped30 starget; pauses near it score higher40 slongest chunk; a clip this short is never cutscore = min(pause, 1 s) − 0.05 per second early, or − 0.1 per second lateHere's one of the unit tests, drawn to scale: a seventy second clip with a full second pause at twenty eight, a short one right at thirty, and another full second at fifty five. The planner prefers the long pause, and cuts at twenty eight and a half. That leaves over forty seconds, so it cuts again at fifty five and a half.
Slide text
unit testa 70-second clip is cut at 28.5 and 55.5 seconds
1 s pause 0.2 s 1 s pause 0 s 102030 405060 70 s 28.5 s 55.5 splan(70.0, &[(28.0, 29.0), (30.0, 30.2), (55.0, 56.0)]) == [28.5, 55.5]cuts_prefer_long_pauses_near_30s, in audio_toolkit/chunking.rs
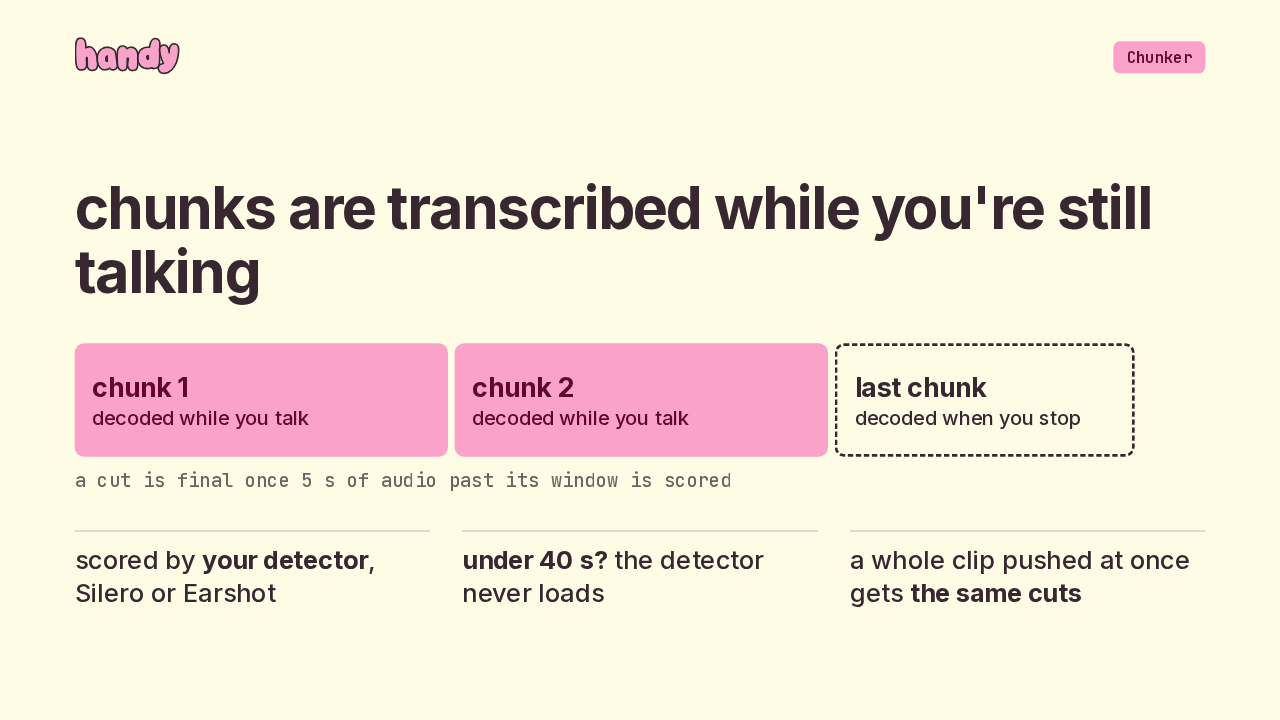
For a recording, this happens live. A chunk comes back once its cut is certain, five seconds past its window, and it's decoded while you keep talking. When you stop, only the last chunk is left. Scoring uses the voice activity detector you picked, Silero or Earshot, and a recording short enough to be one chunk never loads it.
Slide text
Chunkerchunks are transcribed while you're still talking
chunk 1decoded while you talkchunk 2decoded while you talklast chunkdecoded when you stopa cut is final once 5 s of audio past its window is scored
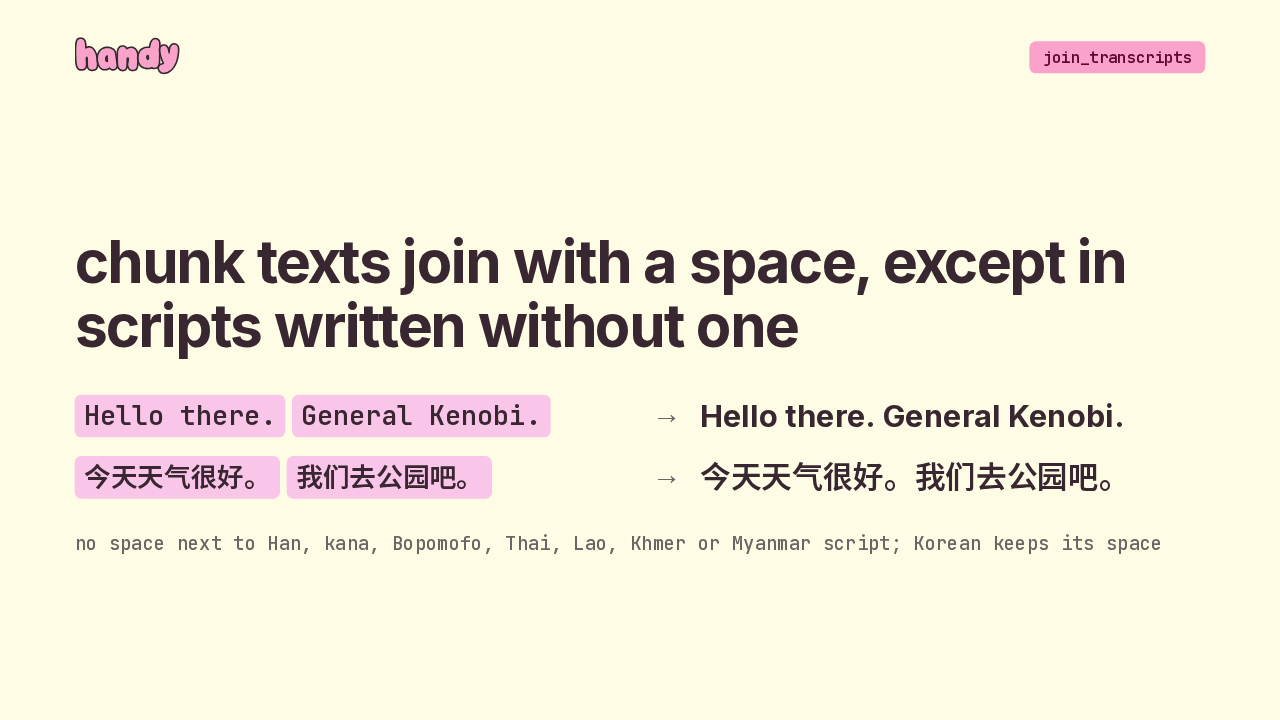
scored by your detector, Silero or Earshotunder 40 s? the detector never loadsa whole clip pushed at once gets the same cutsEach chunk comes back as its own transcript, and a new join function stitches them together in order. It puts a space between chunks, unless either side is a script written without spaces, like Chinese, Japanese or Thai. Korean uses spaces, so it keeps one.
Slide text
join_transcriptschunk texts join with a space, except in scripts written without one
Hello there. General Kenobi.→Hello there. General Kenobi.今天天气很好。 我们去公园吧。→今天天气很好。我们去公园吧。no space next to Han, kana, Bopomofo, Thai, Lao, Khmer or Myanmar script; Korean keeps its space
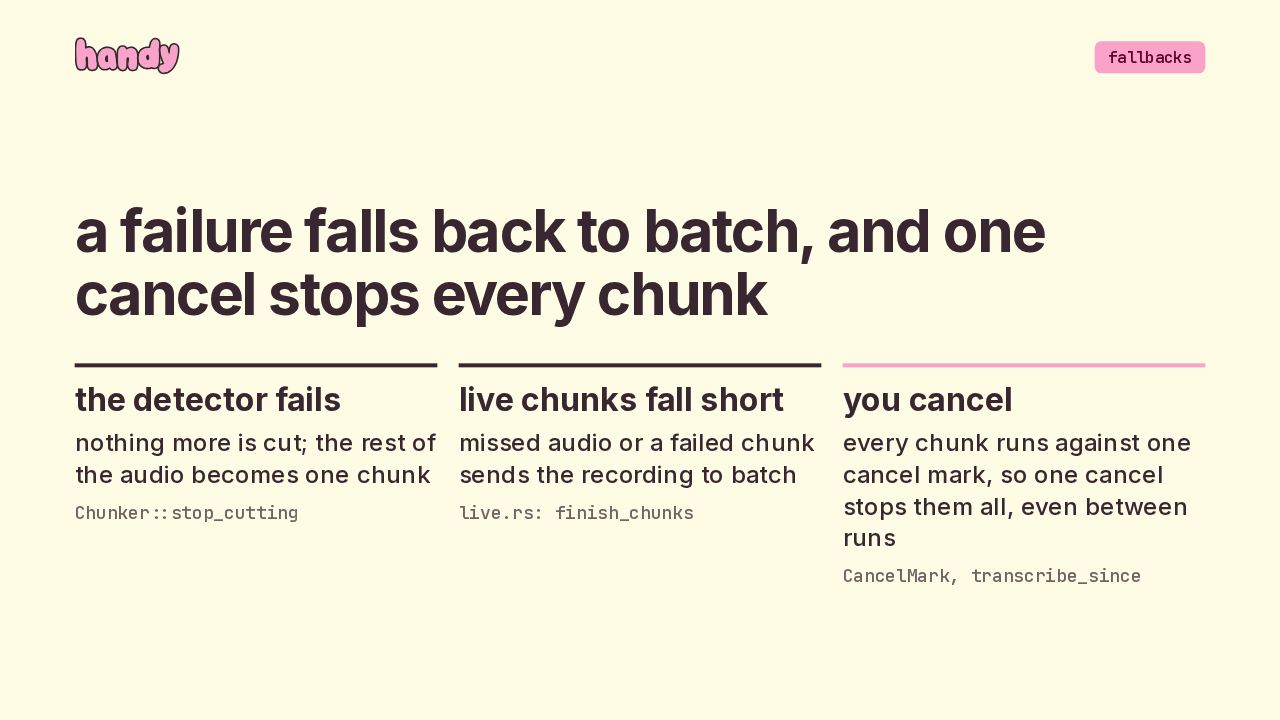
When chunking goes wrong, the audio still gets transcribed. If the detector can't run, the rest of the audio becomes one chunk. If the live chunks missed audio, or one of them fails, the recording is transcribed in batch. And every chunk runs against one cancel mark, so a single cancel stops them all, even between runs.
Slide text
fallbacksa failure falls back to batch, and one cancel stops every chunk
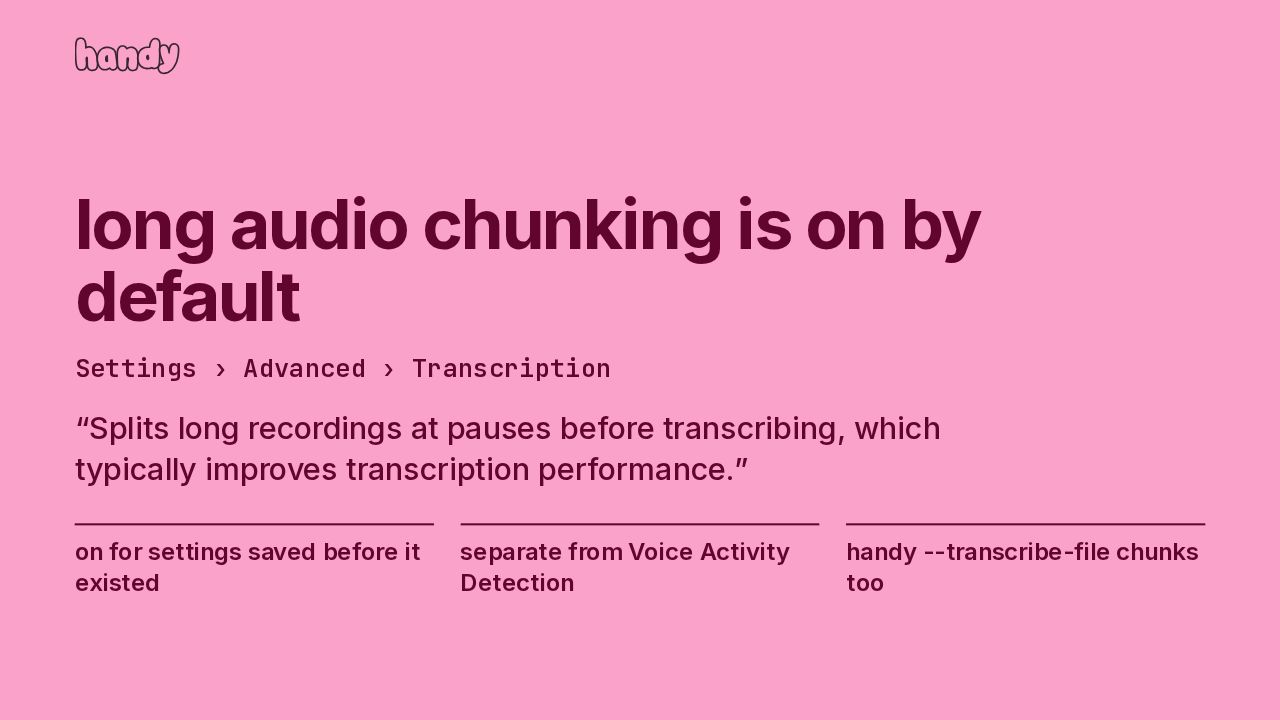
the detector failsnothing more is cut; the rest of the audio becomes one chunkChunker::stop_cuttinglive chunks fall shortmissed audio or a failed chunk sends the recording to batchlive.rs: finish_chunksyou cancelevery chunk runs against one cancel mark, so one cancel stops them all, even between runsCancelMark, transcribe_sinceThere's one new switch, Long Audio Chunking, under Advanced. It's on by default, even for settings saved before it existed. It's separate from voice activity detection, which still only decides whether silence is dropped. And the command line's transcribe file flag chunks long audio the same way.
Slide text
long audio chunking is on by default
Settings › Advanced › Transcription
“Splits long recordings at pauses before transcribing, which typically improves transcription performance.”
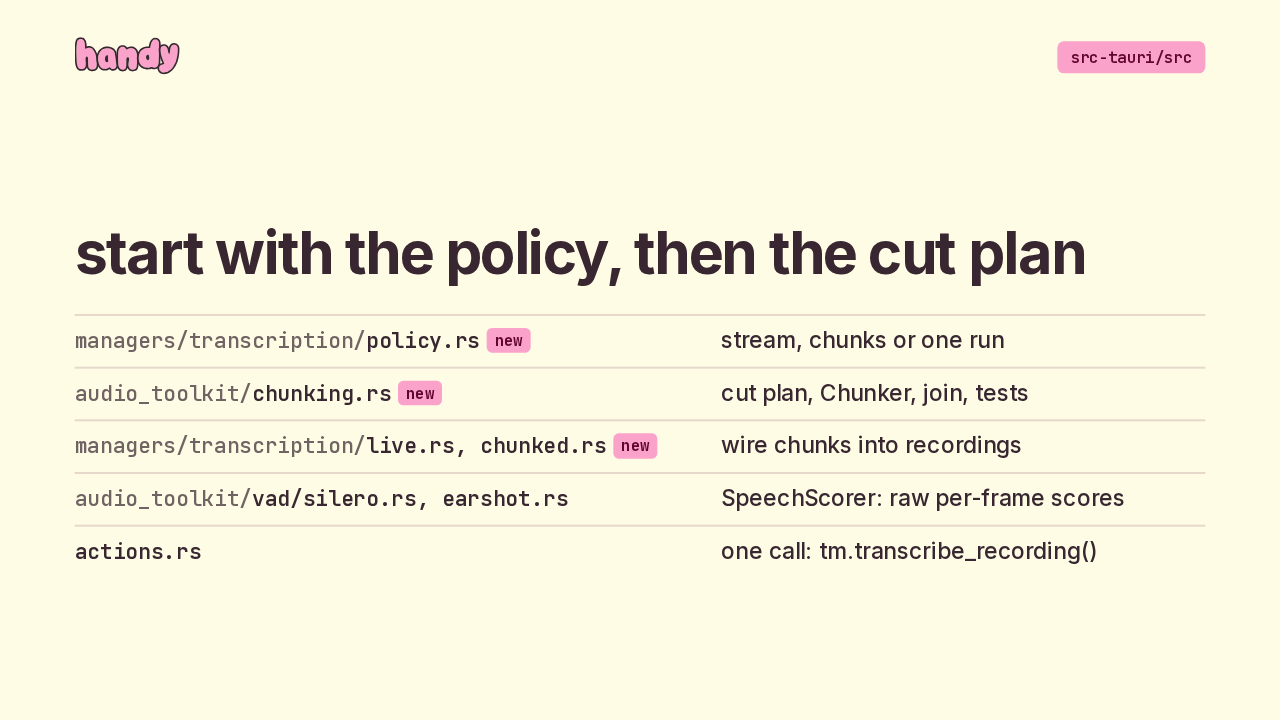
on for settings saved before it existedseparate from Voice Activity Detectionhandy --transcribe-file chunks tooTo read the diff, start with the policy module, which is under seventy lines. Then the chunking module: the cut plan, the chunker, the join, and their tests. Two new files wire it into recordings, the voice detectors gained a trait that returns their raw scores, and the transcribe action now makes a single call.
Slide text
src-tauri/srcstart with the policy, then the cut plan
managers/transcription/policy.rsnewstream, chunks or one runaudio_toolkit/chunking.rsnewcut plan, Chunker, join, testsmanagers/transcription/live.rs, chunked.rsnewwire chunks into recordingsaudio_toolkit/vad/silero.rs, earshot.rsSpeechScorer: raw per-frame scoresactions.rsone call: tm.transcribe_recording()One limit to keep in mind. The pull request doesn't include before and after accuracy numbers, and the tests for Silero scoring and for cancel are marked ignored, so a default test run skips them. The planner and the join have plain unit tests. That's the change: long recordings, cut at pauses, about thirty seconds apart.
Slide text
limitslong recordings, cut at pauses, about 30 seconds apart
Not in the pull request: before-and-after accuracy numbers. The Silero scoring test and the cancel test are marked #[ignore], so a default test run skips them.